Kimi K3.1 Pro adds sparse attention to the Kimi K3 architecture. Each of K3's 24 Gated Multi-head Latent Attention (MLA) layers gains a lightning indexer that selects the 2,048 most relevant earlier tokens to attend to. This reduces the attention work required for long contexts. Moonshot AI's Kimi K3.1 Pro announcement describes the model's capabilities and availability.
Working with the Moonshot AI team, TokenSpeed enabled text generation with Kimi K3.1 Pro at launch on AMD MI350X, NVIDIA Blackwell, and NVIDIA Vera Rubin. The implementation reuses TokenSpeed's sparse-attention backend and K3 model infrastructure. It includes EAGLE3 speculative decoding on MI350X and decode context parallelism for long contexts.
This post is for inference engineers who want to understand the implementation and its performance trade-offs. It covers the indexer, cache layout, GPU kernels, and long-context serving, followed by measurements on MI350X and GB300. The results cover text generation; multimodal input remains future work. The TokenSpeed model recipes provide deployment examples for other supported models, but do not yet include a Kimi K3.1 Pro recipe.
Highlights
- Sparse attention on the existing stack. K3.1 Pro's sparse layers replace dense MLA in K3's hybrid of Kimi Delta Attention (KDA) and MLA. They reuse TokenSpeed's sparse-attention backend with no vendor-specific model code.
- Index keys in the flat cache. Storing index keys in 8-bit floating point (FP8) increases the key-value (KV) cache block size by 21% in the tested configuration.
- Indexer on AMD. FP8 scoring and parallel top-k selection reduce indexer overhead on MI350X. With 16 requests and 4 verification rows each, K3.1 Pro's decode attention is faster than dense K3's at the tested lengths from 32K to 1M tokens. It reaches about 2.4× the speed from 256K to 1M tokens, excluding projections.
- Long contexts across GPUs. Eight-way KV parallelism (KVP8) and eight-way decode context parallelism (DCP8) shard each request's history and index keys. On 8 GB300 GPUs, this raises KV capacity from 2.43M to 16.35M tokens, approximately 6.7×.
- Agentic serving on MI350X. On multi-turn SWE-smith coding sessions on 8 MI350X GPUs, one session receives 248 output tokens/s. Each of 16 concurrent sessions receives 48 output tokens/s.
- Day 0 on Vera Rubin. K3.1 Pro runs end to end on 8 Vera Rubin GPUs as a single instance, with KVP8/DCP8 attention and DSpark speculative decoding.
Sparse attention in Kimi K3.1 Pro
The following table compares the inference architecture of Kimi K3 and Kimi K3.1 Pro:
| Property | Kimi K3 | Kimi K3.1 Pro |
|---|---|---|
| Layer stack | 93 layers: 69 KDA + 24 Gated MLA | Same |
| Gated MLA attention | Dense: every earlier token | Sparse: 2,048 earlier tokens per query, chosen per layer by a lightning indexer |
| Indexer | None | One per MLA layer; 32 query heads with 128 dimensions per head; bfloat16 (BF16) weights |
| KV cache per token, per MLA layer | One 576-value latent row | Latent row + one 128-dimensional index key |
| KDA, Stable LatentMoE, AttnRes | As in the Kimi K3 architecture description | Unchanged |
Kimi K3 interleaves 69 KDA layers with 24 Gated MLA layers; see the Kimi K3 day 0 post. KDA keeps a fixed-size recurrent state during decoding. Dense MLA reads every earlier token's 576-value latent row, so its decode cost grows with context length.
K3.1 Pro adds a lightning indexer to each Gated MLA layer (Figure 1). For each query token, the indexer's 32 query heads score one 128-dimensional key per earlier token and select the top 2,048 tokens. All 96 attention heads in the layer then attend to the selected tokens. Each layer makes its own selection.
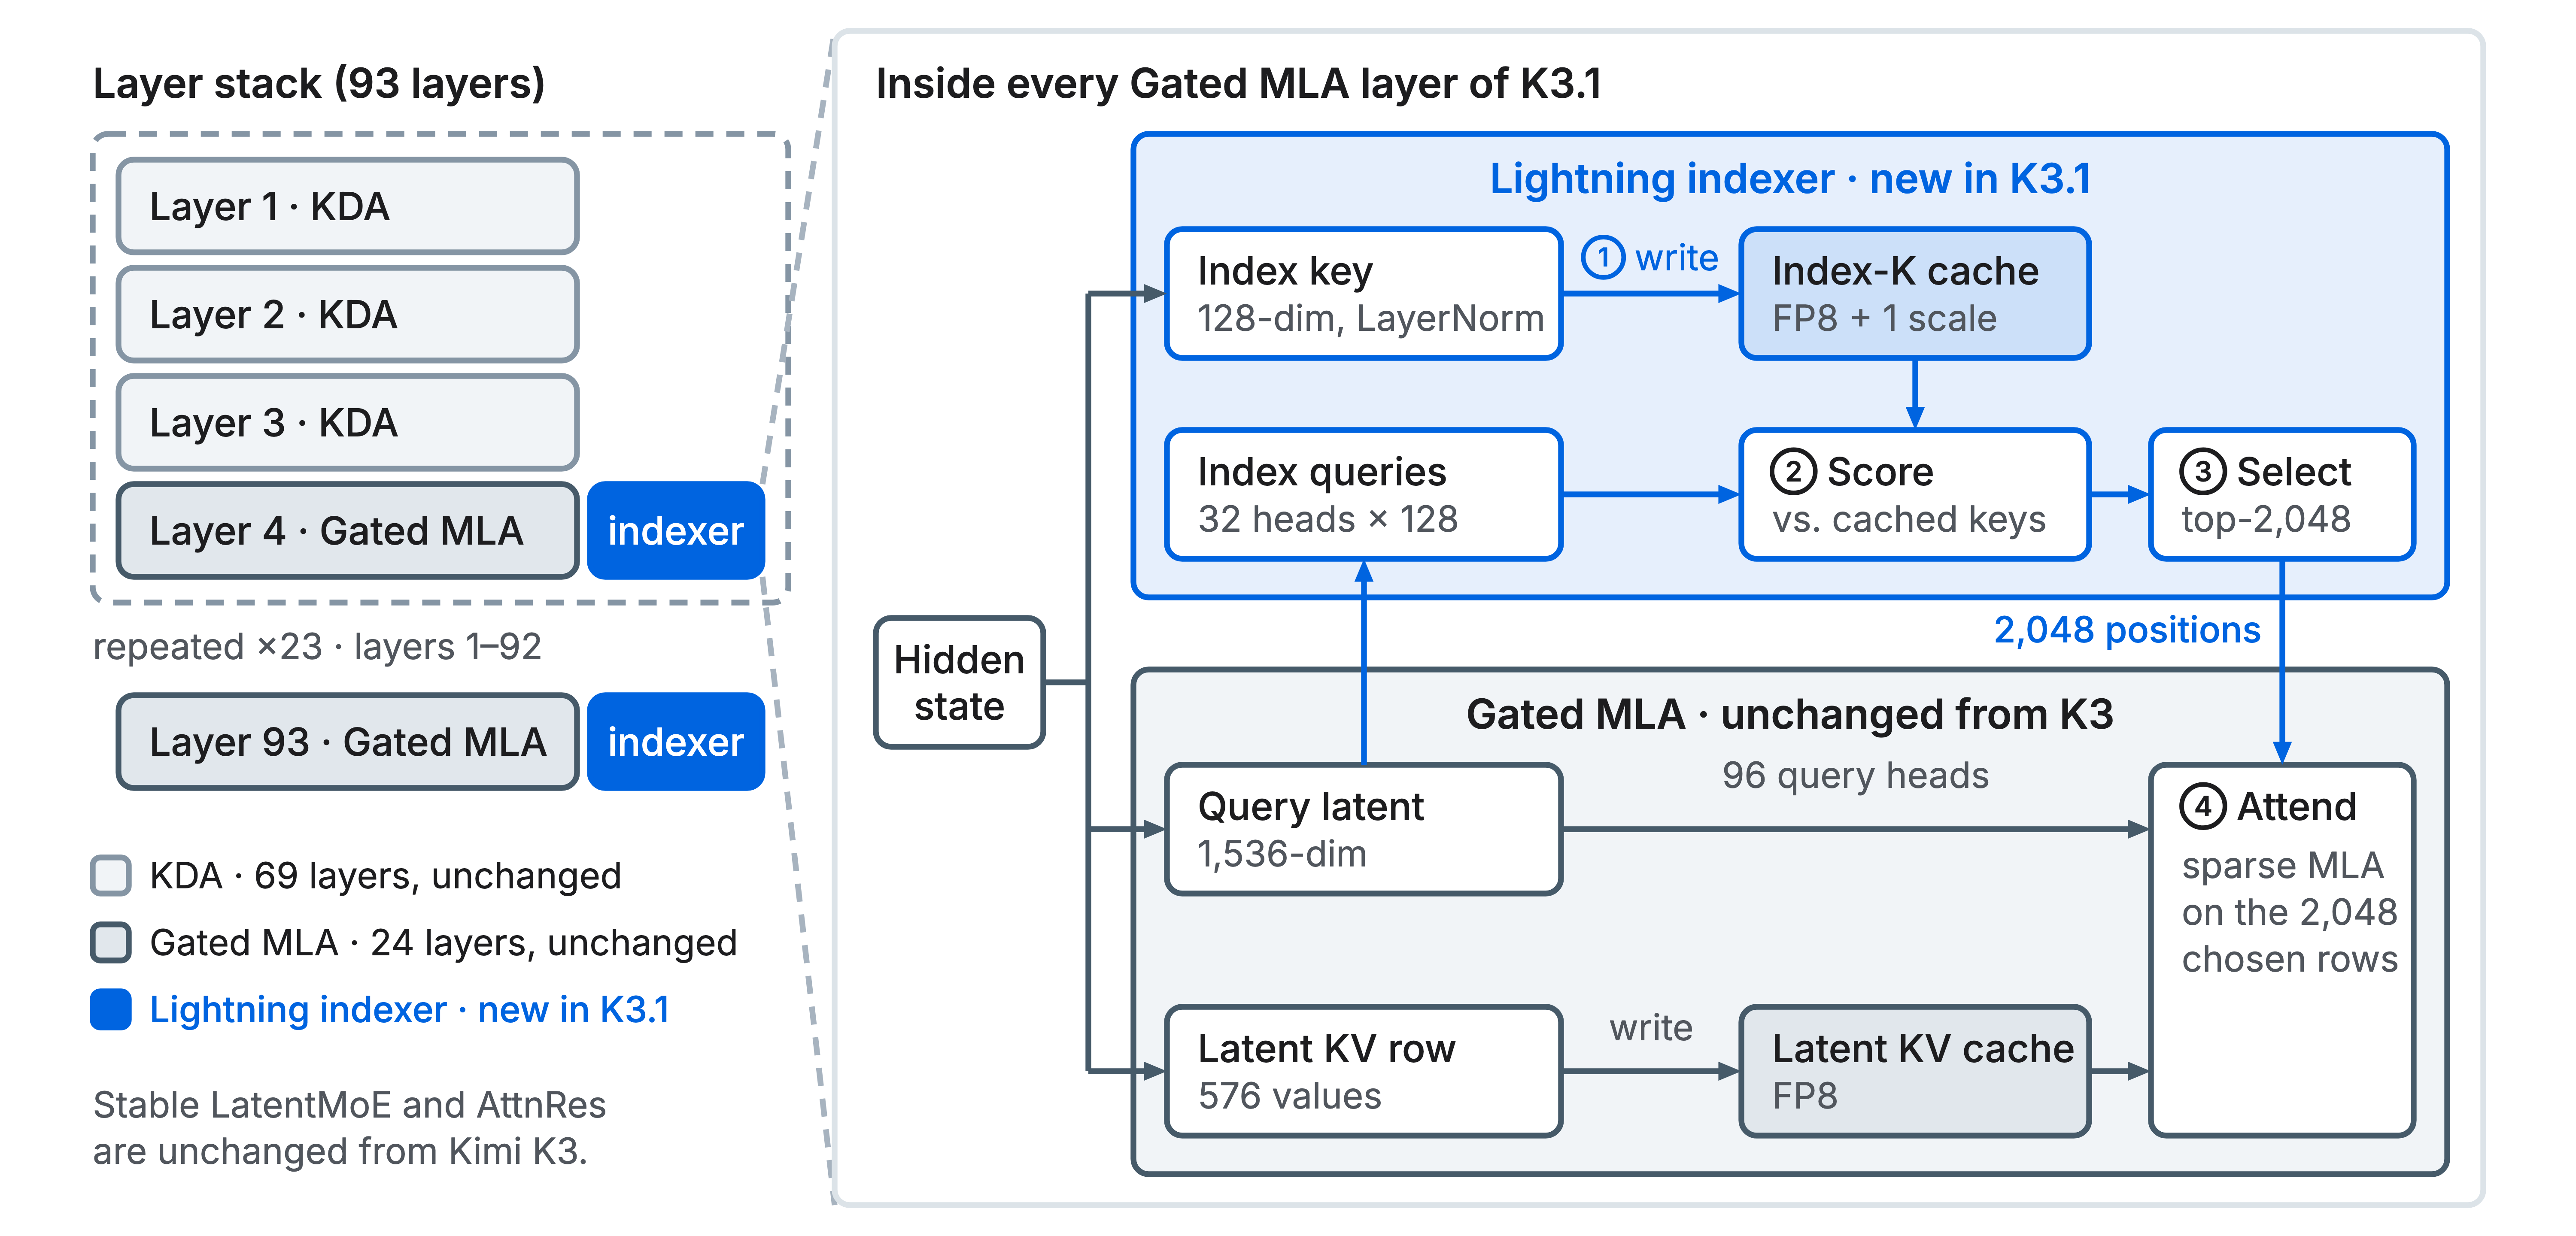
Figure 1. Each of Kimi K3.1 Pro's 24 Gated MLA layers adds a lightning indexer before sparse attention. The numbered callouts match the four implementation steps below.
The indexer still scans every earlier token, but each FP8 index key takes 132 bytes. Sparse MLA reads only 2,048 of the 576-byte FP8 latent rows. At a 128K-token context, the estimated data read per MLA layer per decode token falls from 75.5 MB to 18.5 MB on each tensor-parallel (TP) rank, plus about 1 MB of index scores. This is approximately a 4× reduction in data reads.
With speculative decoding, the MI350X indexer reads each key once for all of a request's verification rows. The estimated saving remains about 3× with 4 verification rows. The absolute saving grows with context length, while the single-row ratio approaches just over 4×. These savings require an extra key per cached token and an indexer scan over the full history.
Integrating sparse attention with the K3 stack
In TokenSpeed, each Gated MLA layer of K3.1 Pro runs in four steps, numbered as in Figure 1:
- Write. One fused kernel normalizes the new token's index key, quantizes it to FP8 with a single scale, and writes it into the cache.
- Score. The indexer's 32 query heads, projected from the layer's query latent, score every cached index key.
- Select. A radix top-k keeps the 2,048 highest-scoring positions for each query.
- Attend. Sparse MLA attends over only those 2,048 latent rows.
TokenSpeed already provides kernels for all four steps on NVIDIA and AMD GPUs, plus a portable Triton fallback. K3.1 Pro adds one model file with no vendor-specific model code. Its sparse layers reuse this backend within K3's hybrid attention architecture.
The loader validates both the sparse-attention configuration and the checkpoint. It rejects missing or unknown configuration keys, a rotary position embedding dimension in the indexer, key normalization other than LayerNorm, and FP8 indexer weights. It also rejects top-k sharing across layers, sparse layers that differ from the configured full-attention layers, and missing or unused indexer tensors.
The following table lists the kernels used for each step:
| Step | NVIDIA Blackwell | AMD MI350X |
|---|---|---|
| Write | Triton: one kernel for the latent row, one for the index key | Triton: one kernel for the latent row, one for the index key |
| Score | DeepGEMM, FP8 index queries and keys | Gluon, FP8 index queries and keys |
| Select | Decode and prefill with DCP use persistent CUDA radix top-k for local candidates, followed by a global top-k merge. Prefill without DCP uses TensorRT-LLM top-k. | Gluon radix top-k, with one or many workgroups per row depending on shape |
| Attend | FlashInfer TRTLLM-GEN sparse MLA | Gluon FP8 sparse MLA |
Storing index keys in the flat KV cache
TokenSpeed's flat KV layout stores a layer's state for a run of tokens in one cache block under one page ID. K3.1 Pro adds an index-key plane next to each MLA layer's latent rows, as Figure 2 shows. The cache allocates, frees, and shards the index keys together with those rows, preserving K3's packing and block granularity. Every full-attention cache block includes index keys, so the memory overhead applies to the entire history pool.
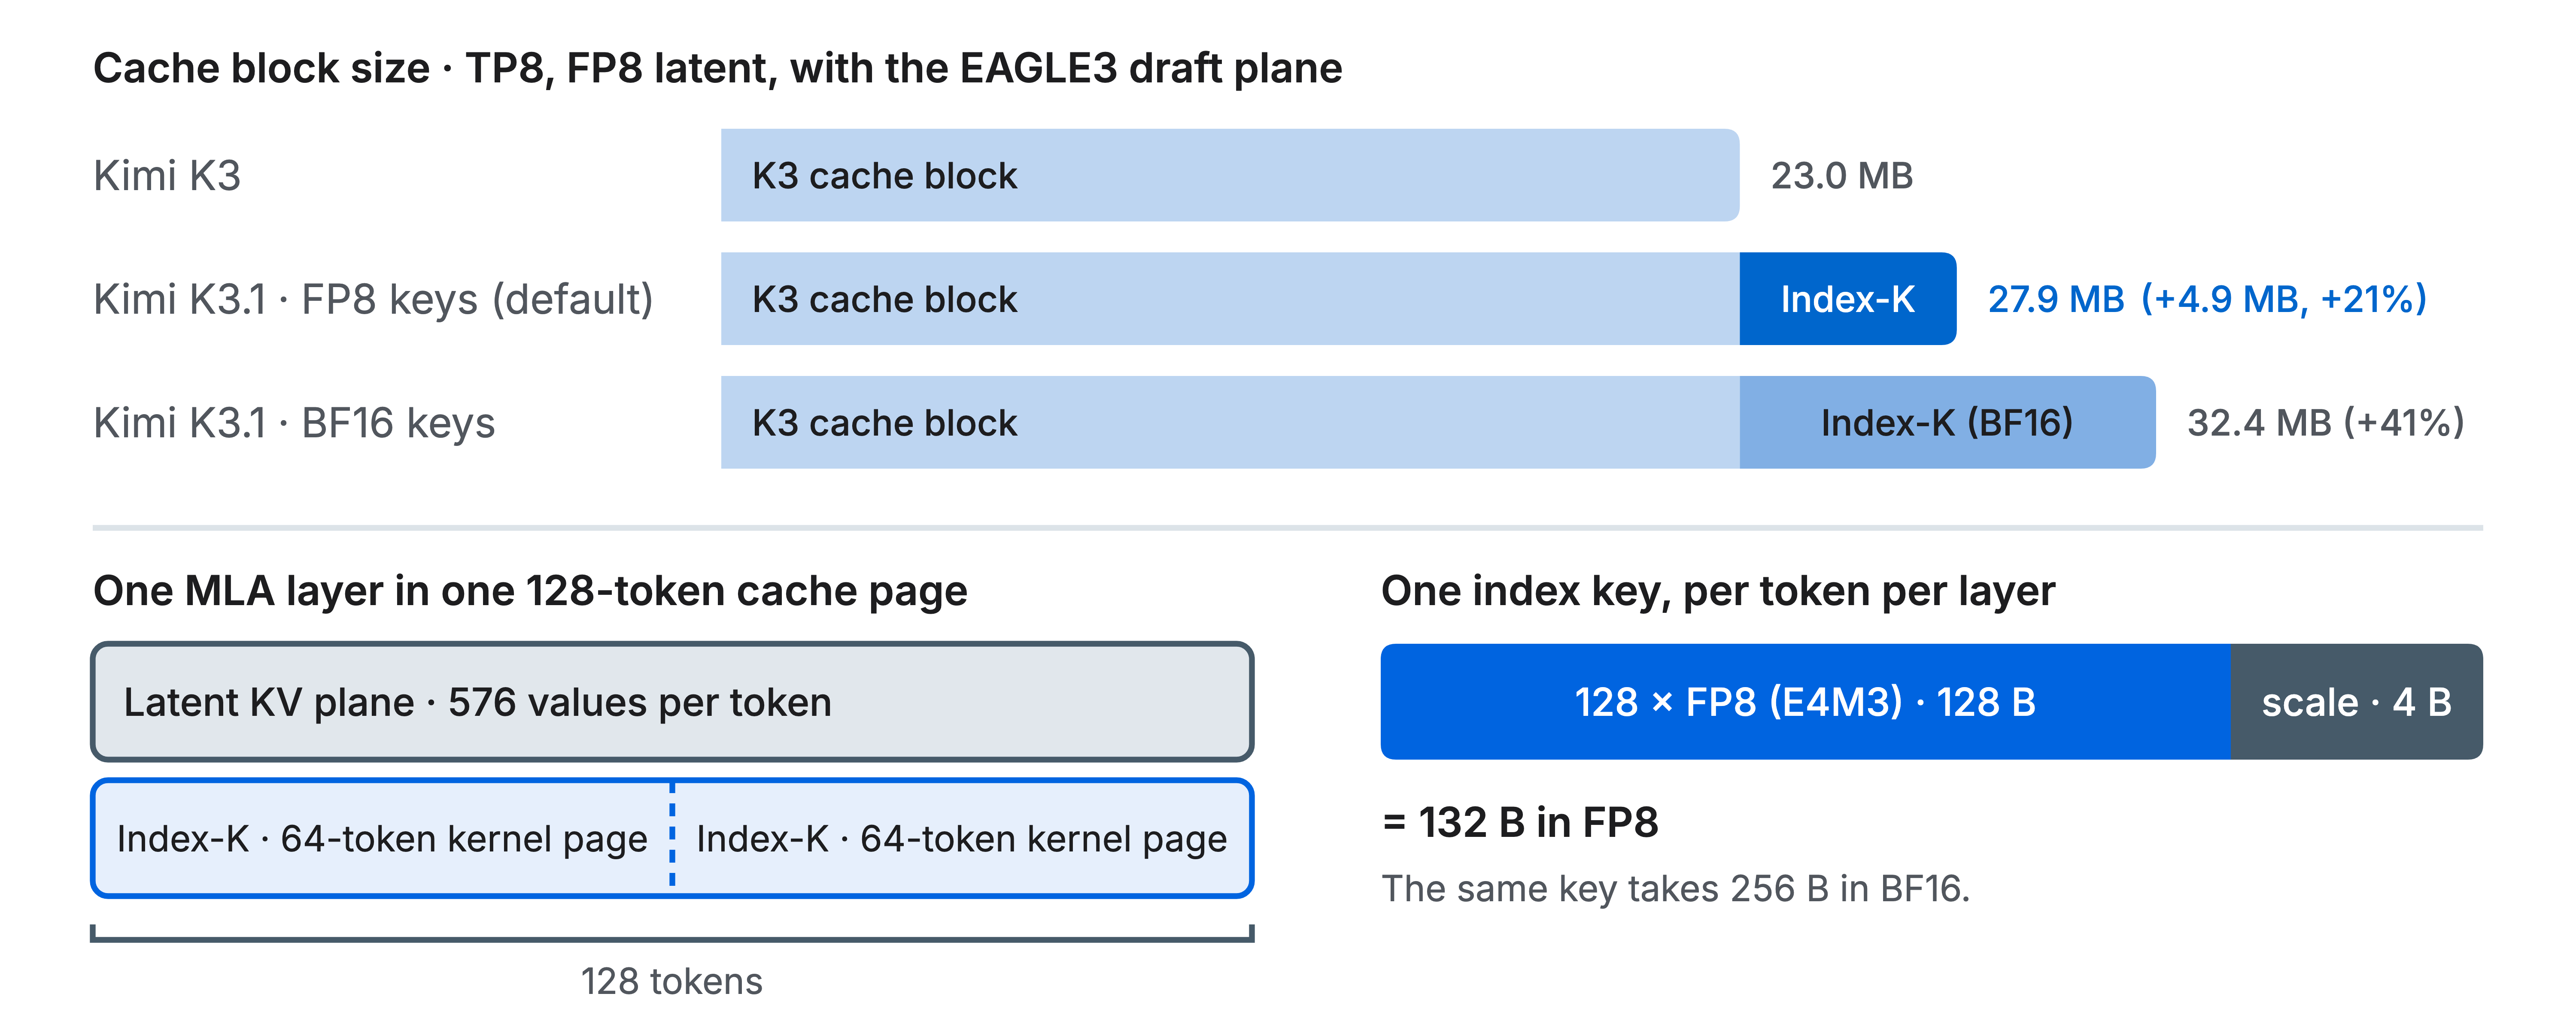
Figure 2. Cache block sizes at TP8 with FP8 latent rows and an EAGLE3 draft plane, followed by the index-key layout for one MLA layer.
Each FP8 index key stores 128 FP8 values and one four-byte scale, totaling 132 bytes per token per layer. A BF16 key takes 256 bytes. The indexer's projection weights remain in BF16.
For the TP8 configuration in Figure 2, with FP8 latent rows and an EAGLE3 draft plane, a K3 cache block takes 23.0 MB. K3.1 Pro takes 27.9 MB with FP8 index keys or 32.4 MB with BF16 keys: overheads of 21% and 41%, respectively. These percentages apply to this cache block configuration.
Compared with a 32-bit floating-point (FP32) indexer, FP8 keys change about 6% of the selected tokens. In two runs each with FP8 and BF16 keys, AIME26 is unchanged and the MRCR two-needle score is about 0.003 lower with FP8 keys. That difference is close to the reported run-to-run spread.
Reducing indexer overhead on AMD MI350X
Sparse attention reduces MLA's work on long contexts, but the indexer still scans every cached token. With EAGLE-3.1 speculative decoding, each layer processes only 4 query rows per request to verify draft tokens. Keeping the GPU occupied during this scan is the main challenge on MI350X. Figure 3 compares decode attention time with dense K3.
The microbenchmark uses FP8 queries and KV on one TP8 rank, with 16 requests and 4 verification rows per request. It excludes projections. Each bar is the mean GPU time of 20 consecutive calls, and the vertical axis is logarithmic.
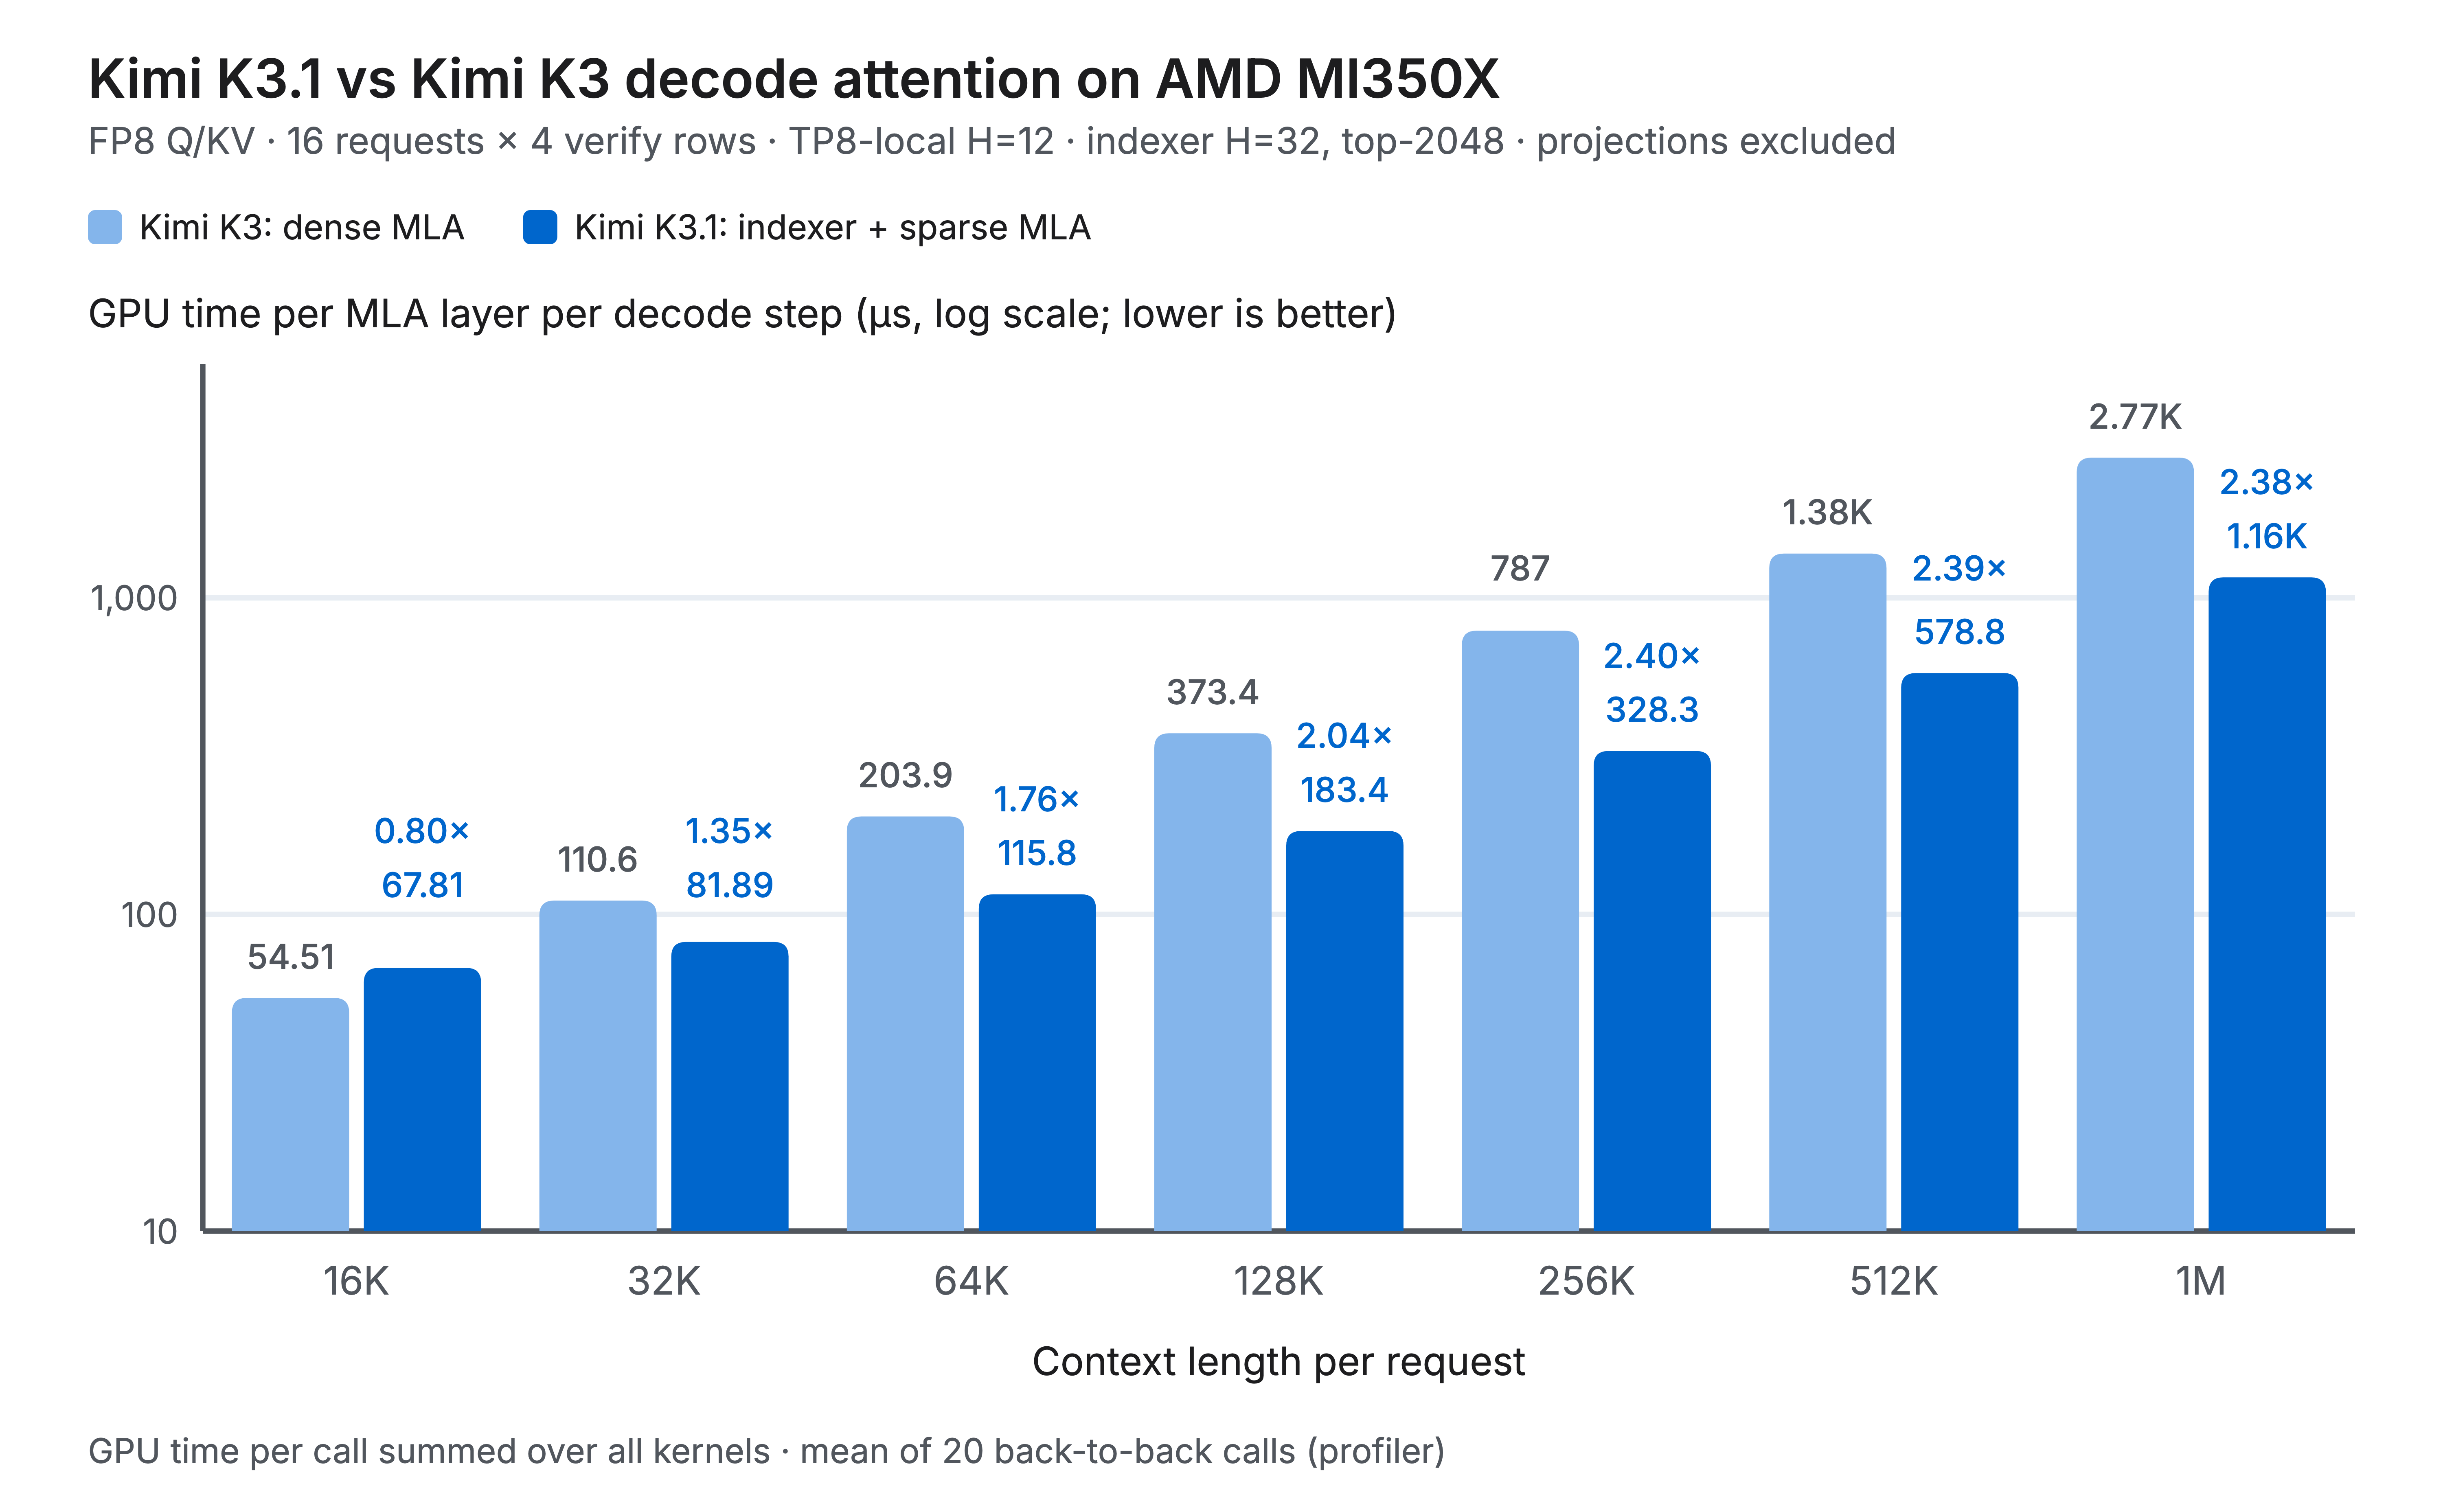
Figure 3. Decode attention time per MLA layer on one MI350X TP8 rank for dense K3 and K3.1 Pro's indexer plus sparse MLA.
Sparse MLA takes 35–41 µs per layer from 16K to 1M tokens, so the indexer drives K3.1 Pro's growth in attention time. Its scan grows linearly with context length. At 16K tokens, K3.1 Pro takes 67.81 µs compared with 54.51 µs for dense K3. It becomes faster at the tested lengths from 32K to 1M tokens and reaches about 2.4× the speed from 256K to 1M tokens. These are attention microbenchmark results, not end-to-end serving speedups.
The scoring kernel processes all of a request's verification rows in one program. It keeps index queries and keys in FP8 and loads each key once for those rows. The top-k kernel spreads each row across multiple workgroups that share a histogram of score prefixes. A single workgroup per row would occupy only 4 of the GPU's 256 compute units for one request. Both kernels size their work using each request's actual context length.
Prefill provides thousands of query rows, but the replicated indexer would make all eight TP ranks repeat the same selection work. TokenSpeed assigns one eighth of the chunk to each GPU and combines the selections with an all-gather. For a full 8,192-row chunk, this makes the selection step 4.8× faster at a 50K-token context and 7.2× faster at 250K tokens. Below 384 rows, the all-gather overhead exceeds the saving, so every GPU selects all rows.
The FP8 sparse-attention kernel keeps the query in registers and fits three workgroups per compute unit to improve occupancy. This reduces an 8,192-row call from 2.01 to 1.37 ms.
Server measurements also exposed a communication-overlap issue. The side stream for Iris, AMD's Triton-based multi-GPU programming framework, shared a hardware queue with the main stream. Moving prefill communication to a high-priority stream reduced time to first token by 8% at concurrency 16.
Sharding long contexts with decode context parallelism
Without KV sharding, every attention-TP rank holds a full copy of the latent cache. TP8 adds compute capacity but no KV capacity for a single request. Sharding also reduces the indexer scan: each GPU scores only the keys stored on that rank.
KV parallelism (--kv-parallel-size N) splits each request's MLA history across N attention-TP ranks. Latent rows and index keys are sharded together; KDA state remains replicated. Decode context parallelism (--decode-context-parallel-size N) computes attention on these shards, as Figure 4 shows:
- Each rank scores its local index keys.
- The ranks exchange candidates to select one global top-2,048 per query.
- Each rank attends to the selected rows it holds.
- The ranks merge the partial outputs using log-sum-exp (LSE).
This exchange adds communication. At KVP8, each rank sends about 119 KiB per verification row per MLA layer for its candidates, query heads, and partial outputs. The end-to-end measurements below show the resulting trade-off between cache capacity and decode speed.
TokenSpeed's sparse-attention backend already supports owner-masked cache writes, candidate exchange, and the LSE merge. A capability flag enables DCP for K3.1 Pro. Two-GPU tests compare token selection and outputs with a single GPU holding the full history, including CUDA graph replay and extension of a cached prefix. Performance also required the optimizations described in the GB300 results.
FlashInfer's TRTLLM-GEN sparse MLA kernel returns the LSE values required for the merge in TokenSpeed's pinned release. The final benchmark build uses this kernel for DCP.
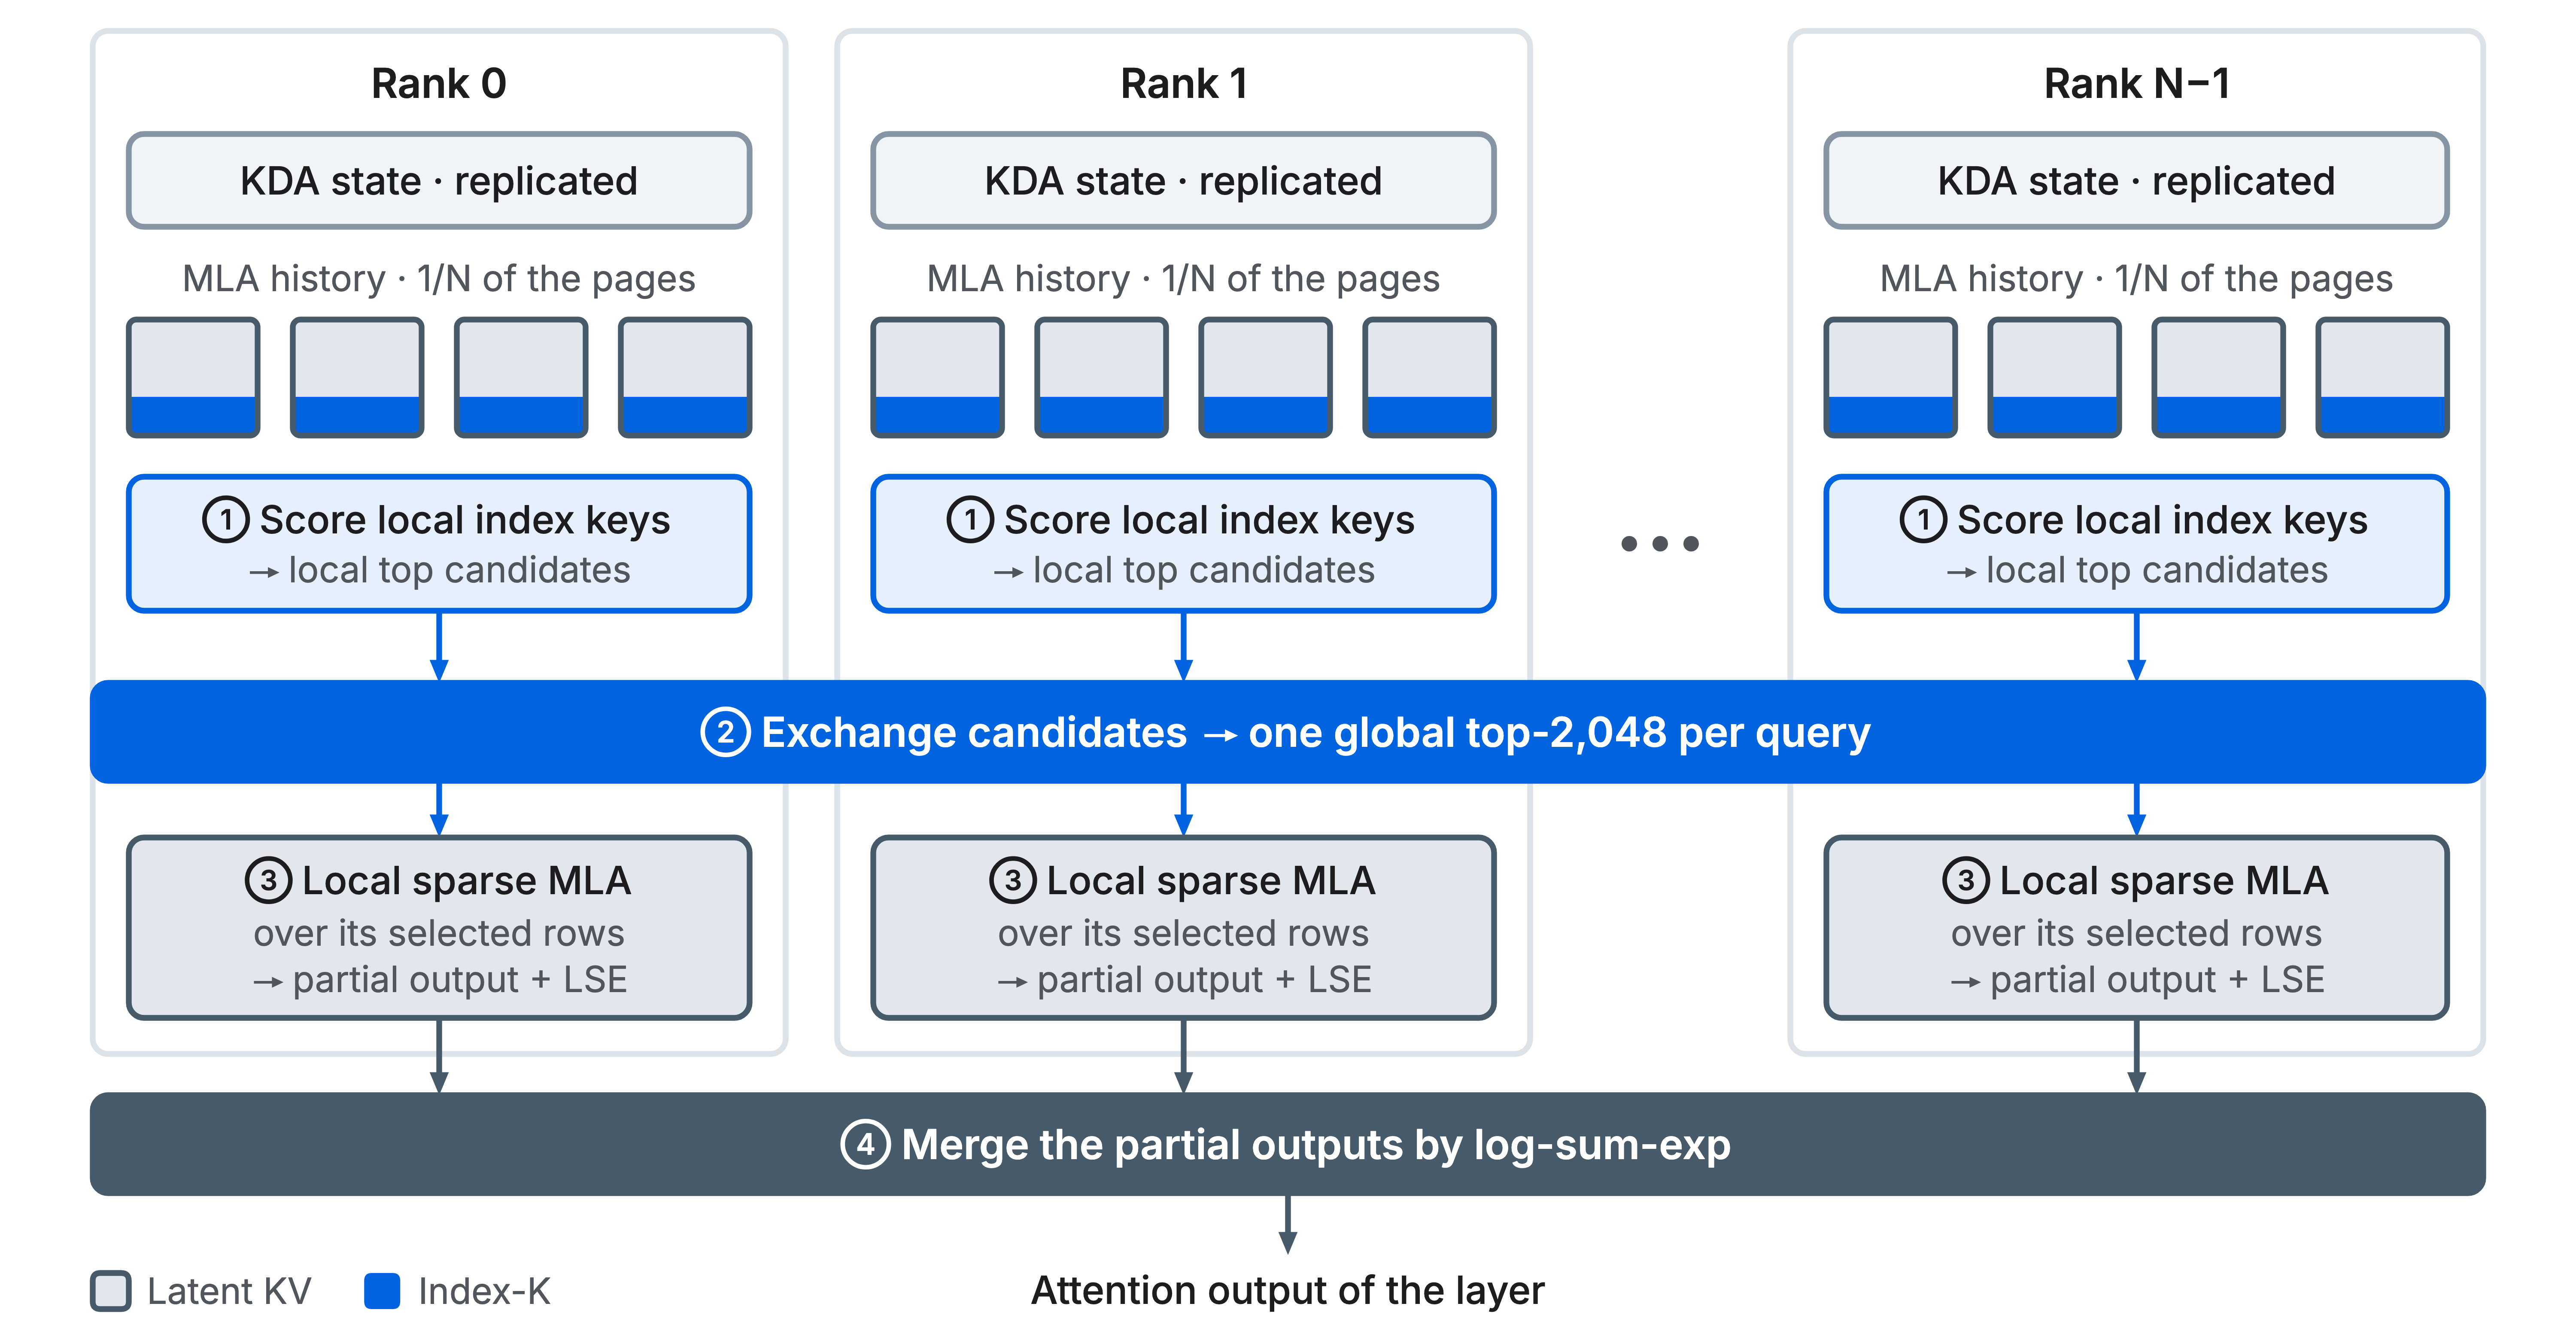
Figure 4. Each rank holds replicated KDA state and 1/N of the MLA history, with latent rows and index keys sharded together. DCP combines the ranks' partial attention outputs.
For reference, the Kimi K3 KV-sharding benchmark uses dense MLA at TP8 on 8 GB300 GPUs across two nodes. On a 128-conversation replay at concurrency 64, KVP8 + DCP8 reached 14.2–14.6 requests/s, compared with 6.97 requests/s at KVP1. With KVP1, the MLA cache held 1.92M tokens instead of 15.18M, the prefix-cache hit rate fell from 94.3% to 87.4%, and the server computed 2.2× the prompt tokens. An earlier Kimi K3 DCP evaluation measured a 1–12% reduction in per-user decode speed at DCP2–8.
These earlier results use Kimi K3 and a different workload. The following section reports Kimi K3.1 Pro measurements separately.
End-to-end serving performance
AMD MI350X on long agentic conversations
Agentic coding workloads repeatedly extend a long conversation. To measure serving performance, we replayed multi-turn SWE-smith coding sessions on 8 MI350X GPUs at TP8. Each conversation starts with approximately 50K prompt tokens, adds approximately 800 tokens per turn over 10–15 turns, and generates 500 tokens per reply. The configuration uses EAGLE3 speculative decoding with Kimi K3's EAGLE-3.1 draft (3 steps, 4 draft tokens), FP8 KV, and GPU prefix caching.
With one active session, K3.1 Pro generates 248 output tokens/s per user (4.03 ms per output token), with a 0.53-second average time to first token. At concurrency 16, each session receives 48 output tokens/s. The sessions' combined history, about 1M tokens, exceeds the GPU prefix cache, so this point adds a host-memory KV cache with 8× the GPU cache capacity. Figure 5 shows the trade-off between per-user output speed and the benchmark's reported total-token throughput.
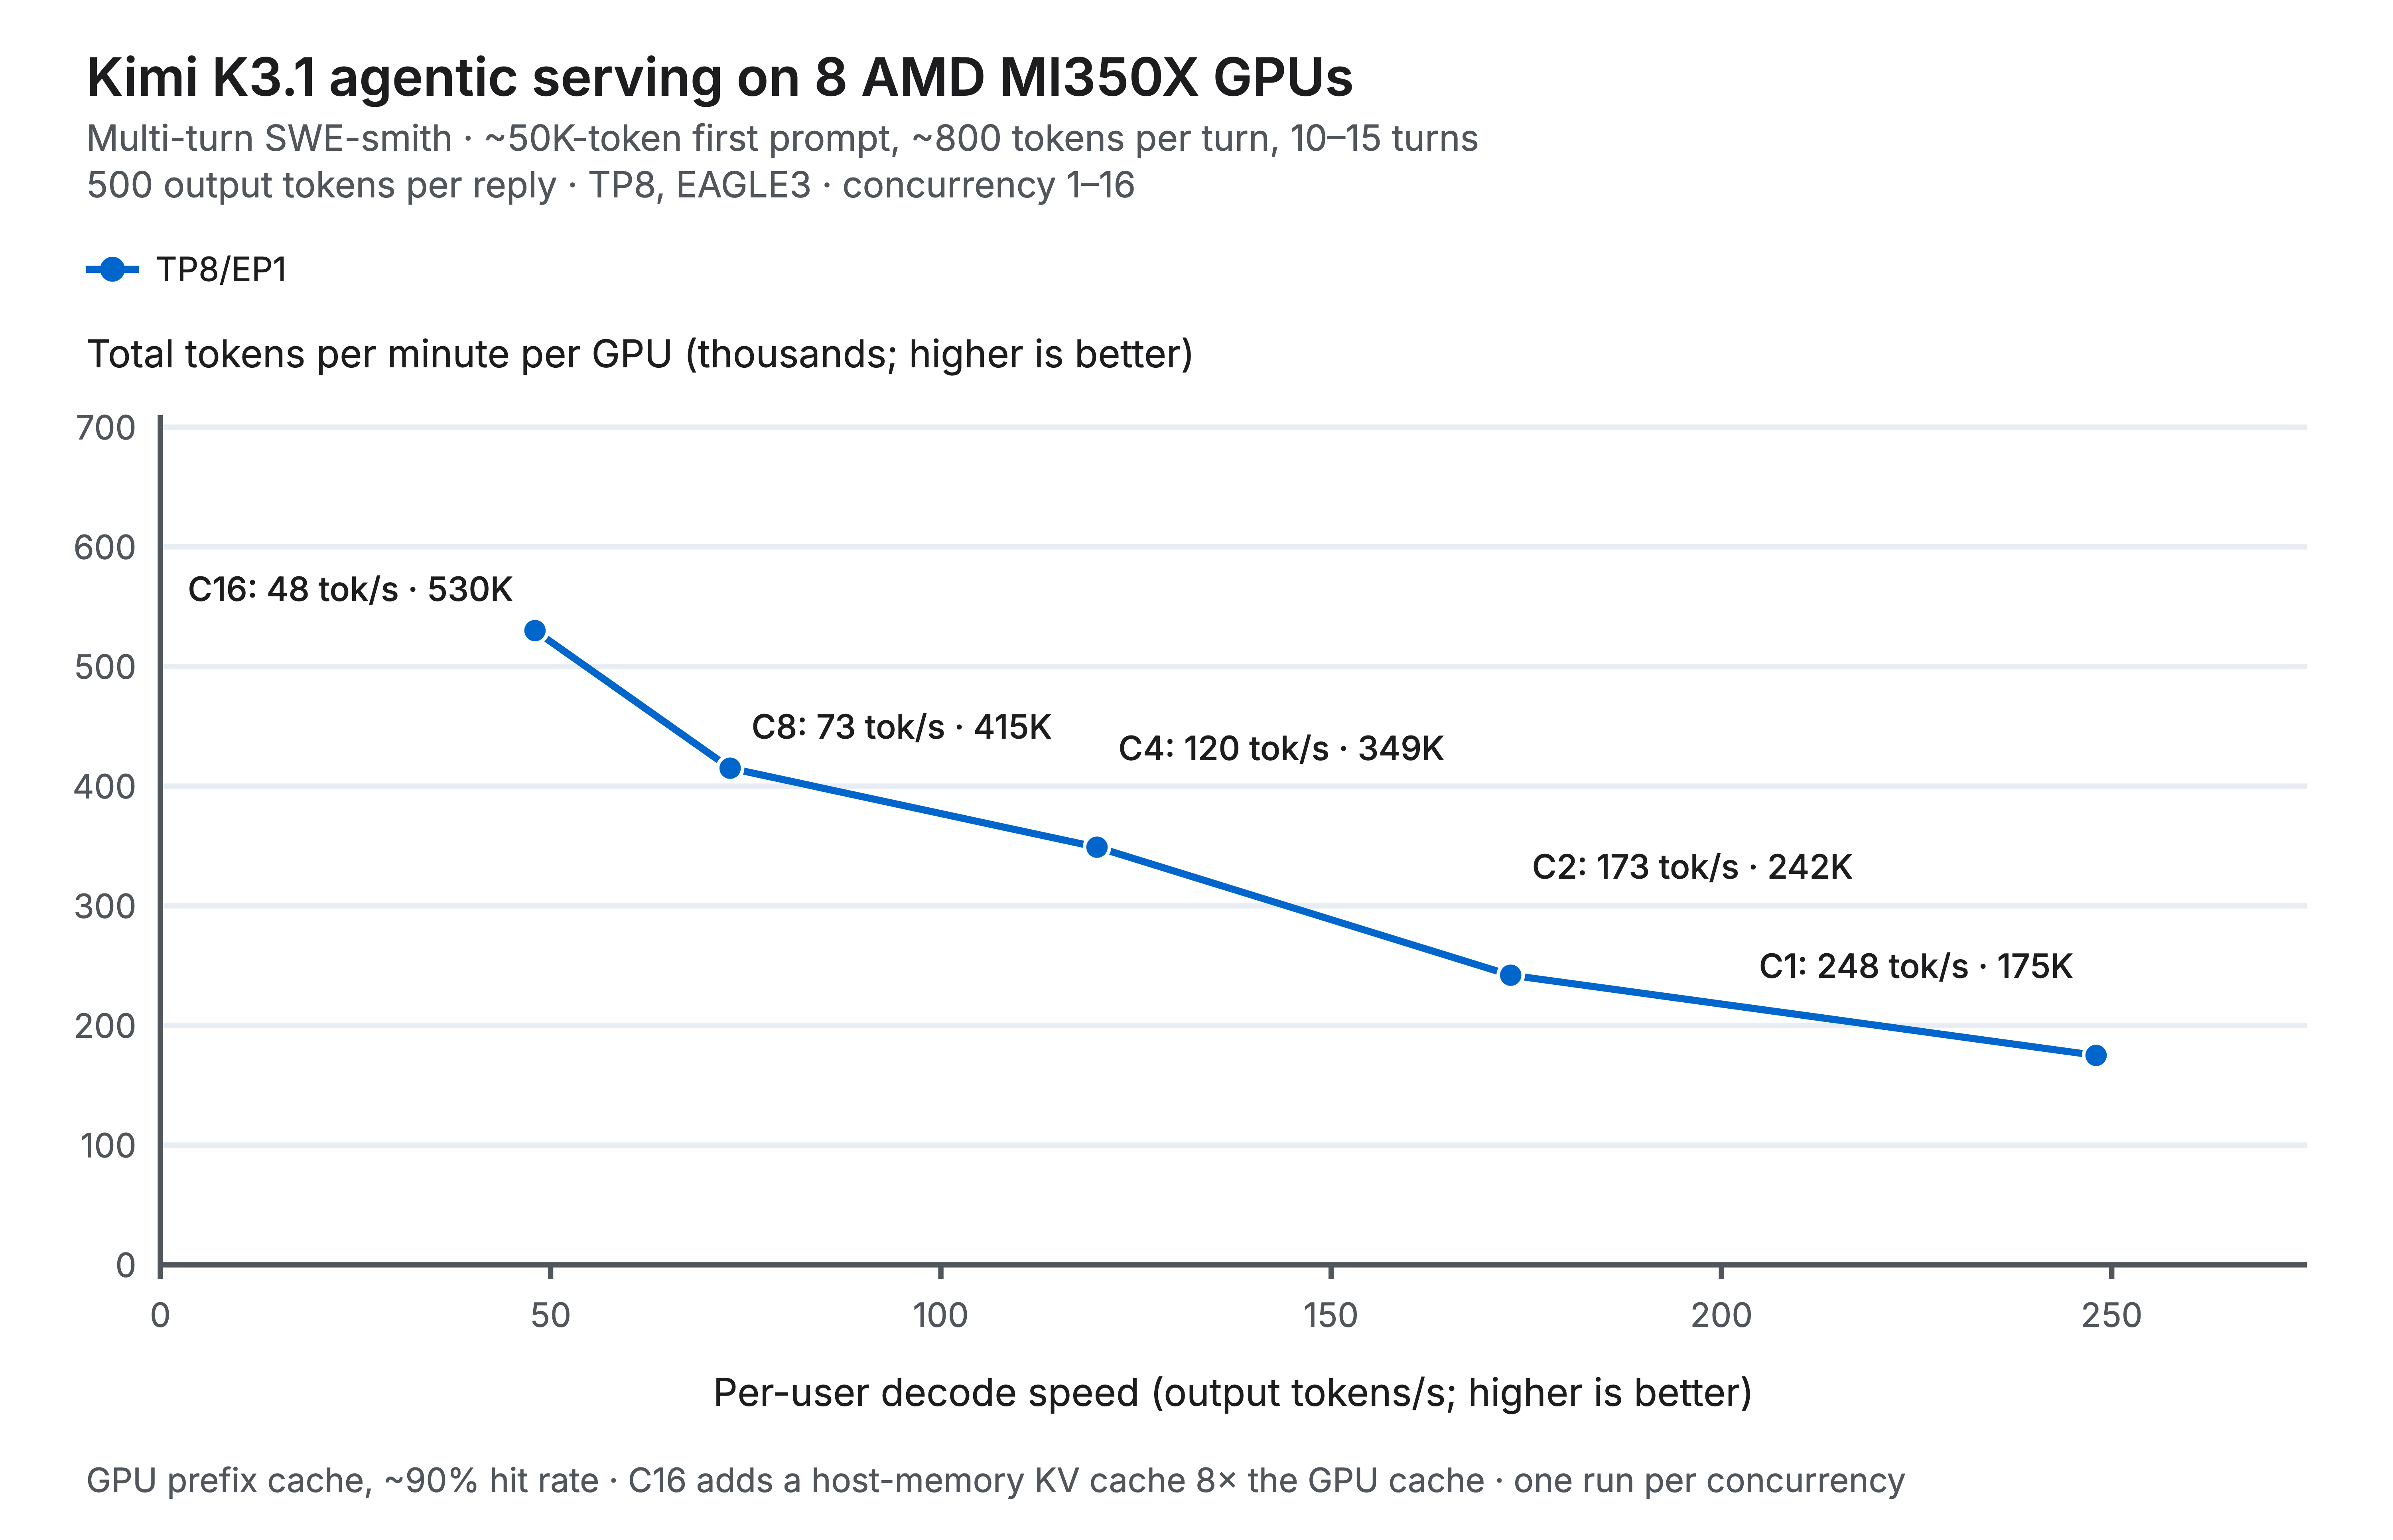
Figure 5. Kimi K3.1 Pro agentic serving on 8 MI350X GPUs. Each point is one run; concurrency 16 also adds a host-memory KV cache.
The chart reports 175K total tokens/min/GPU at concurrency 1 and 530K at concurrency 16. The benchmark summary does not specify how input tokens or prefix-cache hits enter this total, which limits comparisons with other token-throughput measurements. The cache configuration also changes at concurrency 16, so these points do not isolate the effect of concurrency alone.
NVIDIA GB300 with KV and decode context parallelism
The GB300 experiment measures the capacity and performance trade-off of KV and decode context parallelism. Both configurations use one TP8 instance across 8 GB300 GPUs, DeepGEMM index scoring, and FlashInfer TRTLLM-GEN sparse MLA. We replay AgentX coding sessions with an average prompt length of 134K tokens for one hour per concurrency setting, using DSpark speculative decoding with 7 steps. The benchmark summary specifies acceptance fixed at 3.84 but does not define the unit or control method for this setting.
The following table reports KV capacity, request throughput at the stated concurrency, and median per-user decode speed at concurrency 1:
| Setup | KV capacity (tokens) | Request throughput (requests/s) | Median decode speed at concurrency 1 (relative to KVP1) |
|---|---|---|---|
| KVP1, DCP off | 2.43M | 0.31 (concurrency 8) | 1.00× |
| KVP8 + DCP8 | 16.35M | 1.37 (concurrency 64) | 0.92× |
KVP8 holds approximately 6.7× as many KV tokens as KVP1. The measured request throughput is about 4.4× higher, but the comparison uses concurrency 64 for KVP8 and concurrency 8 for KVP1. KVP1 was tested only up to concurrency 8, so this ratio compares the reported operating points and does not establish a speedup at equal concurrency. KVP8's median per-user decode speed is 8% lower at concurrency 1 and 11% higher at concurrency 8.
Figure 6 plots output throughput against per-user decode speed computed from the 90th-percentile inter-token latency. This differs from the median decode metric in the table. KVP8 reaches 164 output tokens/s/GPU at concurrency 64. The Pareto frontier connects the measured points for which neither metric can improve without reducing the other.
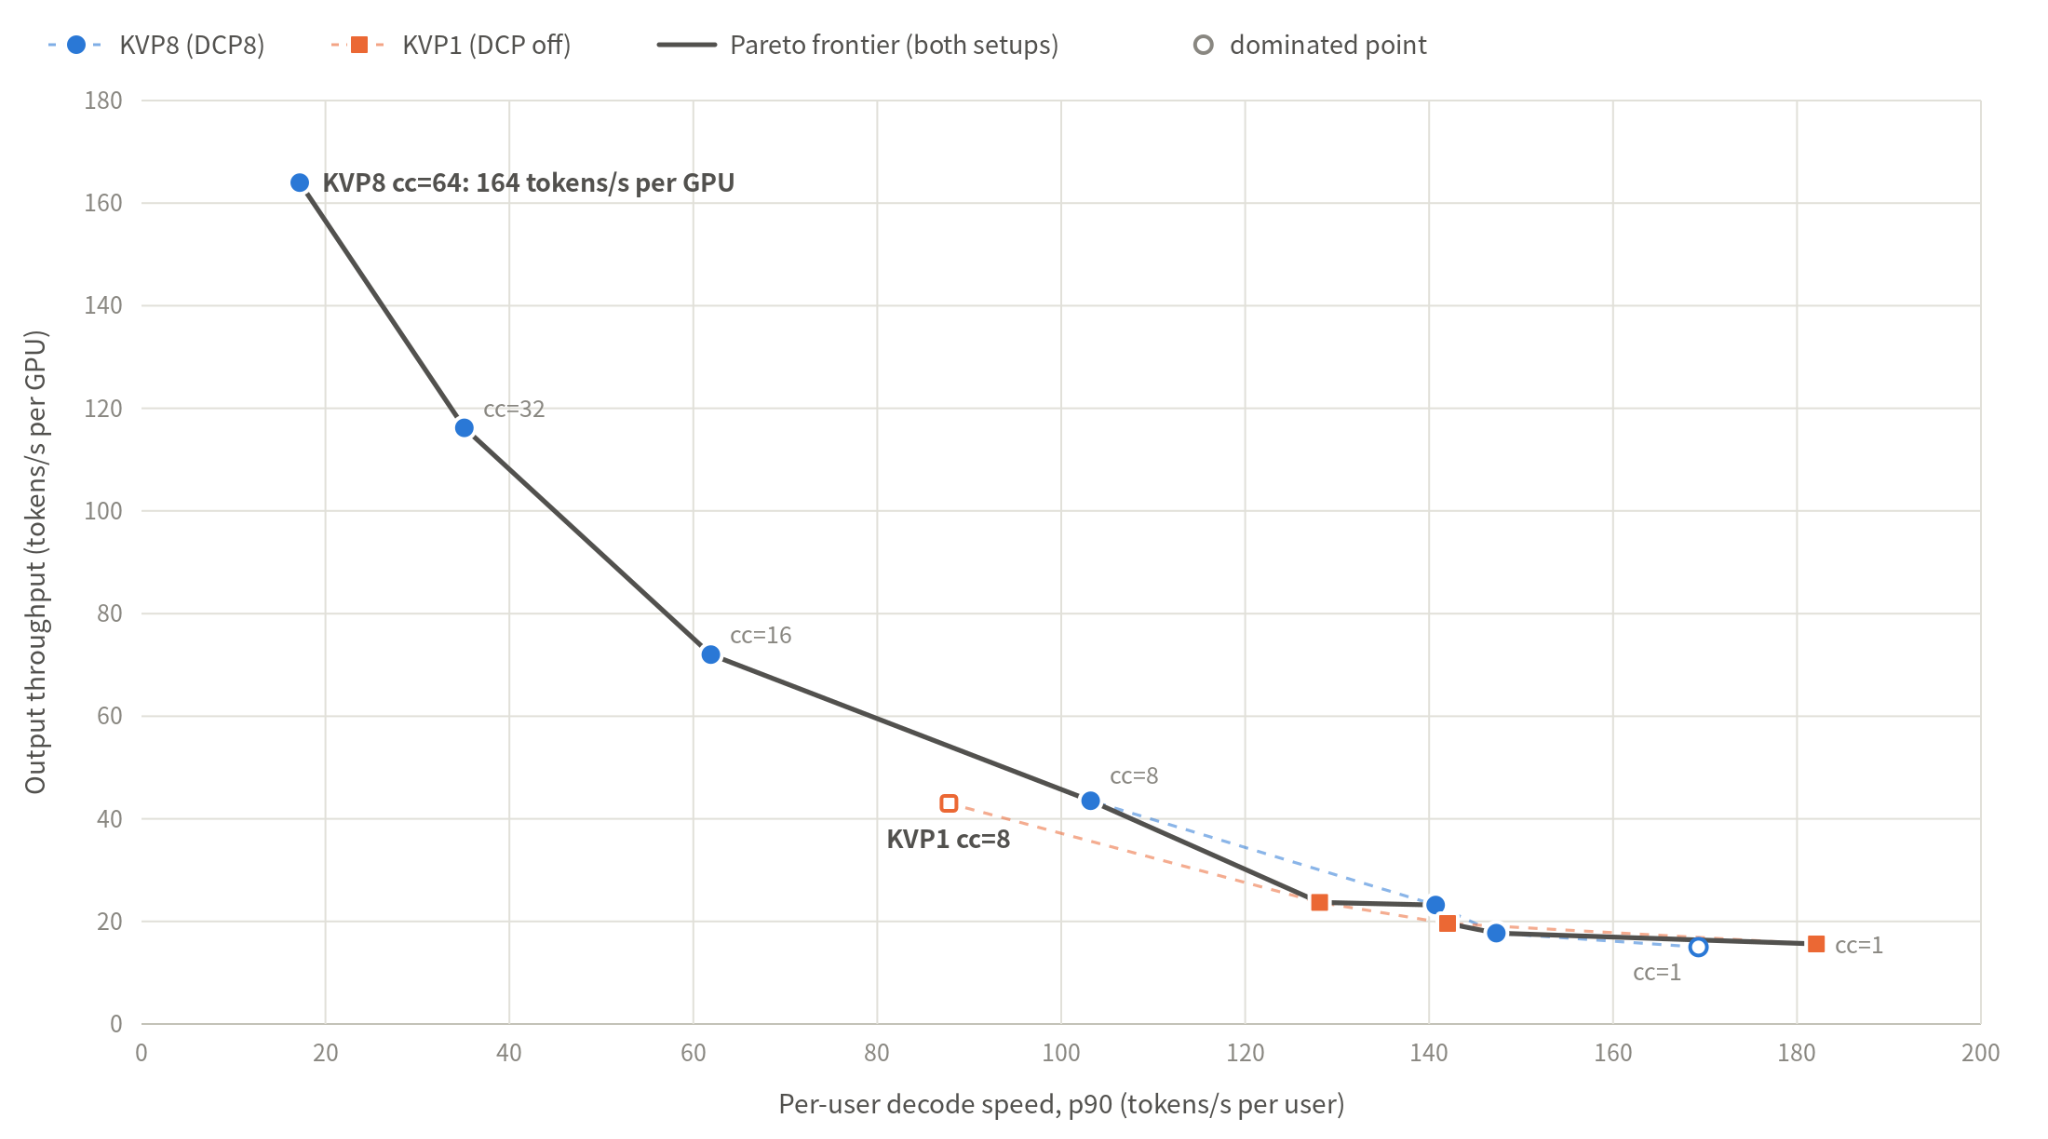
Figure 6. Output throughput per GPU and per-user decode speed based on p90 inter-token latency on 8 GB300 GPUs. Labels marked cc indicate concurrency.
DCP optimizations. Two isolated comparisons used earlier builds with 4 speculative steps. Their results are separate from the 7-step serving experiment above:
- Decode path. Each rank selects candidates only from the portion of each row that covers the request, exchanges candidates once per layer, and attends only to the selected rows it owns. At KVP8, each rank handles about one eighth of the selected rows. In a separate 16-GPU A/B run with prefill and decode on separate instances, these changes raised output throughput per GPU to 2.4× the baseline at concurrency 16.
- Attention kernel. Switching DCP from the Triton fallback to TRTLLM-GEN made the kernel 7× faster, but initially left serving throughput unchanged. After removing five surrounding PyTorch copies and fills, sparse attention time per 16K-token prefill pass fell from 335 to 163 ms, and throughput increased by 7.7% in that comparison.
The benchmark build also includes a host-cache fix from TokenSpeed main. The available results do not quantify the combined improvement over the initial capability-flag-only build.
Day 0 support on NVIDIA Vera Rubin
The Vera Rubin implementation builds on TokenSpeed MLA 2, a dense MLA decode kernel tuned for the K3 family's 96 attention heads. K3.1 Pro runs as one instance on 8 Vera Rubin GPUs across two 4-GPU nodes. The configuration uses TP8 attention with KVP8 and DCP8, TP8 mixture-of-experts (MoE) layers, and DSpark speculative decoding.
The port reuses Blackwell kernel paths with three changes:
- Extend the supported architecture checks for the MXFP4 MoE kernels and fused MoE all-reduce.
- Use FlashInfer's source-form CuTeDSL kernel for KDA prefill. It compiles for Rubin and matches the reference implementation.
- Support CUDA graph capture for KDA and sparse-attention prefill, including with KV parallelism.
End-to-end execution is working; Vera Rubin performance measurements are not yet reported here.
Current limits and next steps
TokenSpeed's Kimi K3.1 Pro implementation reuses the flat KV cache and sparse-attention backend with no vendor-specific model code. The measurements in this post cover text generation on MI350X and GB300; Vera Rubin performance tuning is still in progress.
Next steps include wide expert parallelism, prefill-decode disaggregation, multimodal input, and a faster decode-context-parallel path on MI350X. These features are outside the scope of the results reported here.
Acknowledgments
We thank Moonshot AI for the partnership and early access to Kimi K3.1 Pro, AMD for CDNA4 compiler and Gluon support, NVIDIA DevTech for Blackwell kernel support, and the FlashInfer community.