PD Disaggregation
Prefill-Decode (PD) disaggregation runs the two phases of LLM inference on separate workers. Prefill workers process the prompt and build its KV cache. Decode workers take over that cache and generate the output tokens. For every request, SMG picks a prefill/decode pair, runs the KV handoff the way the engine expects, and returns the decode worker's output to the client.
Overview
Optimized TTFT
Prefill workers only process prompts, so a new prompt never waits behind a decode batch.
Optimized TPOT
Decode workers only generate tokens, so their batches are not interrupted by prompt processing.
Independent Scaling
Size and scale the prefill and decode pools separately, each with its own routing policy.
KV Handoff
SMG speaks each engine's handoff protocol: bootstrap rooms for SGLang and TokenSpeed, kv_transfer_params relay for vLLM.
Why Disaggregate?
Traditional LLM inference has two distinct phases with different characteristics:
| Phase | Compute Pattern | Bottleneck | Optimization |
|---|---|---|---|
| Prefill | Compute-bound, parallel | GPU compute | Batch similar-length prompts |
| Decode | Memory-bound, sequential | Memory bandwidth | Maximize batch size |
Running both phases on the same worker creates inefficiencies:
- Prefill batches are delayed waiting for decode slots
- Decode batches are small due to prefill memory pressure
- Neither phase is optimally configured
PD disaggregation solves this by dedicating workers to each phase.
Supported Engines
| Engine | Worker transport | Dispatch | KV transfer |
|---|---|---|---|
| SGLang | HTTP or gRPC | Parallel, bootstrap room | Mooncake or NIXL (engine flag --disaggregation-transfer-backend) |
| vLLM | HTTP or gRPC | Sequential, kv_transfer_params relay; MoRI-IO WRITE optionally concurrent |
NixlConnector or MooncakeConnector (engine flag --kv-transfer-config); MoRIIOConnector over HTTP, on main after v1.11.0 |
| TokenSpeed | gRPC | Parallel, KV bootstrap room | Mooncake |
- The worker URL scheme selects the path.
http://workers go through the HTTP PD router, which forwards the client's JSON body to both legs and adds the handoff fields.grpc://workers go through the gRPC pipeline, where SMG tokenizes the prompt and parses the output itself. - Other runtimes have no PD protocol. TensorRT-LLM and MLX cannot serve as PD legs. A gRPC PD request that lands on another runtime fails with 400
runtime_pd_not_supported. - Direct ZMQ workers are rejected. An
ipc://worker registered as prefill, decode, or encode fails registration, because the ZMQ wire carries no KV-transfer metadata. See ZMQ Workers. - EPD adds an encode leg. For multimodal models on TokenSpeed, EPD moves the vision tower onto separate encode workers.
How It Works
Parallel Dispatch (SGLang, TokenSpeed)
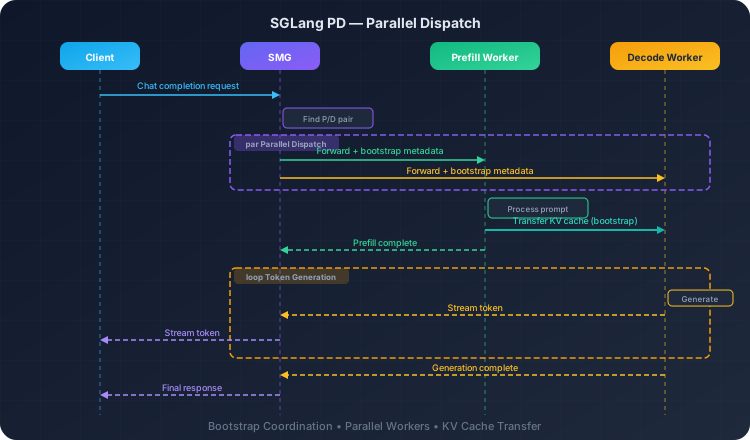
- Select a pair. The prefill policy picks a prefill worker, then the decode policy picks one of the decode workers that can pair with it (see Pairing).
- Mint a rendezvous. SMG generates a bootstrap room and points both legs at the prefill worker's bootstrap server: its host and the bootstrap port the worker was registered with. Over HTTP, SMG adds
bootstrap_host,bootstrap_port, andbootstrap_roomto the JSON body of both legs. Over gRPC, SGLang receives them as disaggregation parameters and TokenSpeed as KV bootstrap fields. - Dispatch both legs at once. The engines use the room to find each other, and the prefill engine transfers the KV cache it computes to the decode engine.
- Stream the decode output back to the client.
Register every prefill worker with its bootstrap port (--prefill <url> <port>). Over gRPC, a prefill worker without one is addressed on port 8998. Over HTTP, SMG forwards the registered value as it is. With --dp-aware, SGLang legs carry the DP rank of the selected worker. TokenSpeed places both legs by bootstrap_room % dp_size, so SMG mints the room to land on the prefill worker's rank.
Sequential Dispatch (vLLM)
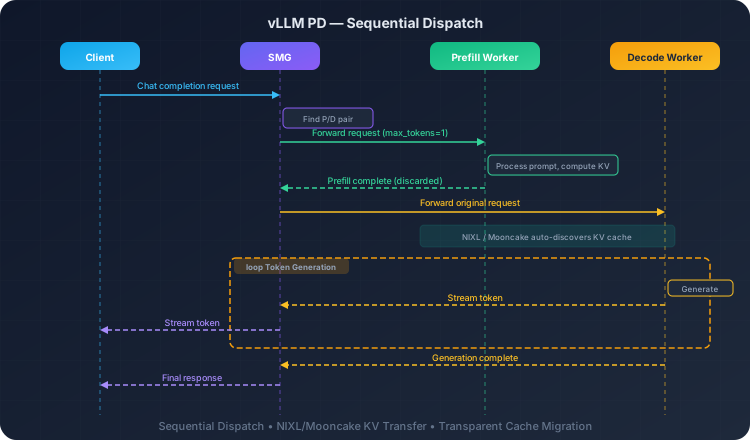
- Send prefill a one-token request. The prefill leg carries the prompt with the output capped at one token, streaming off, and
nset to 1. Over HTTP, SMG sets the endpoint's own cap field (max_tokens,max_completion_tokenswhen the chat request used it, ormax_output_tokenson/v1/responses) and dropsmin_tokensandstream_options. It also tags the leg with the connector'skv_transfer_params(see below). - Wait for prefill to finish. The prefill engine computes the KV cache and holds it for the handoff.
- Relay the handoff. SMG adds
kv_transfer_paramsto the original request and sends it to decode. - Decode receives the KV cache from prefill and streams tokens back to the client.
Connector Modes
The prefill worker's KV connector decides how SMG tags the prefill leg and what the decode leg carries:
| Prefill connector | Prefill leg | Decode leg kv_transfer_params |
|---|---|---|
NixlConnector |
{"do_remote_decode": true, "do_remote_prefill": false} |
The params the prefill response returns (for example remote_engine_id, remote_request_id, remote_block_ids, remote_host/remote_port, tp_size), forwarded verbatim |
MooncakeConnector |
The same tag plus a transfer_id that SMG mints |
Synthesized by SMG, because Mooncake pushes the KV and returns nothing: {"do_remote_decode": false, "do_remote_prefill": true} plus transfer_id, remote_engine_id (the prefill's KV engine id), and remote_bootstrap_addr = http://<bootstrap_host>:<bootstrap_port> (port 8998 when the worker has none) |
MoRIIOConnector (HTTP) |
The same tag plus a minted transfer_id, remote_dp_size: 1, and the decode's TP as remote_tp_size when the decode has a tp_size label. WRITE mode also names the decode's side channel: remote_host, remote_handshake_port, remote_notify_port. The leg also gets ignore_eos: true and loses stop and stop_token_ids |
The params the prefill response returns, forwarded verbatim only after SMG checks that they carry the minted transfer_id and the prefill peer (remote_engine_id, remote_block_ids, remote_host, remote_handshake_port, remote_notify_port), each in a shape the decode engine parses. Under concurrent WRITE dispatch, minted up front by SMG instead: {"do_remote_decode": false, "do_remote_prefill": true} plus the minted transfer_id, remote_dp_size: 1, the prefill's side channel (remote_host, remote_handshake_port, remote_notify_port), and the prefill's tp_size label as remote_tp_size when set. See MoRI-IO |
| None or another connector | No tag ("passthrough") | Whatever kv_transfer_params the prefill response returns, if any |
The handoff falls back to a local recompute in these cases:
- NIXL prefill returns nothing. SMG increments
smg_pd_kv_transfer_failures_totaland decode recomputes the prompt. The usual causes are an outdated servicer or a worker without--kv-transfer-config. - Mooncake without an engine id. Minting needs the prefill's KV engine id. Without it, gRPC falls back to injecting the bootstrap host and port, and over HTTP decode recomputes the prompt.
n>1. The handoff is single-consumer, so no KV is handed off and decode computes the prompt itself. Over HTTP, SMG skips the prefill leg entirely. Over gRPC, the prefill leg still runs, untagged, and a Mooncake decode leg still receives the legacy bootstrap host and port.
A MoRI-IO decode engine never recomputes the prompt, so MoRI-IO has no such fallback: SMG fails the request instead (see MoRI-IO).
Where the Connector Comes From
| Worker transport | Source |
|---|---|
| gRPC | The vLLM servicer reports kv_connector, kv_role, and kv_engine_id from the engine's --kv-transfer-config. A MultiConnector that wraps exactly one NixlConnector or MooncakeConnector is reported as that connector, with the child's engine id (or the parent's when the child sets none). Any other MultiConnector stays passthrough. |
| HTTP | The vLLM OpenAI server reports no connector, so set it when you register the worker: the kv_connector field of POST /workers (plus kv_engine_id and bootstrap_port for Mooncake), or the smg.ai/kv-connector and smg.ai/kv-engine-id pod annotations under service discovery. A vLLM HTTP worker registered by URL alone runs passthrough, and decode recomputes every prompt. |
A restarted vLLM process without a pinned engine_id comes back with a new KV engine id. When a gRPC prefill worker recovers from the failed or not-ready state, SMG re-reads its engine id before routing to it again. Workers registered over HTTP keep the engine id they were registered with.
MoRI-IO (HTTP)
vLLM's MoRIIOConnector moves the KV cache over RDMA with MoRI-IO in one of two modes. In READ mode ("read_mode": true in kv_connector_extra_config on both engines), the decode engine pulls the KV after the prefill leg returns. In WRITE mode, the default, the prefill engine pushes the KV into blocks the decode engine allocates. SMG sends the legs sequentially by default in both modes; a WRITE pair can opt into concurrent dispatch with the decode worker's moriio_write_dispatch label (see below).
A MoRI-IO decode engine never recomputes the prompt. Without a valid handoff it answers with text computed over KV that never arrived (READ) or waits for a push that never comes (WRITE). SMG therefore takes the MoRI-IO path whenever the decode worker is a MoRIIOConnector worker, and fails a request rather than sending a decode leg without its handoff.
HTTP vLLM workers report none of the MoRI-IO settings, so set them as worker labels when you register each leg, matching the engine's kv_connector_extra_config:
| Label | Default | Meaning |
|---|---|---|
moriio_mode |
none (required) | read or write. Both legs of a pair must use the same mode |
moriio_host |
The worker URL's host | The address on which the peer engine reaches this worker's MoRI-IO side channel (used in WRITE mode). The prefill engine pushes to the decode worker's; under concurrent dispatch the decode engine also dials the prefill worker's |
moriio_handshake_port |
6301 |
The engine's handshake_port |
moriio_notify_port |
61005 |
The engine's notify_port |
moriio_write_dispatch |
sequential |
sequential or concurrent: whether SMG sends the two WRITE legs one after the other or at once. Honored on the decode worker; a READ pair stays sequential. Any other value on either worker refuses the pair |
tp_size |
Unset: both legs have the same TP | The decode engine's tensor-parallel size, sent to the prefill as remote_tp_size. Under concurrent dispatch, the prefill worker's value is likewise sent to the decode leg. With vLLM 0.30.1rc1.dev396+gac68c3087, a TP4 prefill with a TP8 decode worked in READ mode, but in WRITE mode the decode request never completed, through vllm-router as well: only half of the decode ranks received KV (vllm-project/vllm#60101). Until that is fixed, use READ mode or the same TP on both engines |
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{"url": "http://prefill-0:8000", "worker_type": "prefill", "runtime_type": "vllm",
       "kv_connector": "MoRIIOConnector", "labels": {"moriio_mode": "write"}}'
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{"url": "http://decode-0:8000", "worker_type": "decode", "runtime_type": "vllm",
       "kv_connector": "MoRIIOConnector", "labels": {"moriio_mode": "write"}}'
The engines do not need proxy_ip and proxy_ping_port, which only register them with vllm-router.
Before either leg is contacted, SMG refuses:
- A misconfigured pair with 503
moriio_pair_misconfigured: a leg that is not aMoRIIOConnectorworker, legs in different modes, a worker with DP>1, a missing, unparsable, or invalid label (including amoriio_write_dispatchvalue other thansequentialorconcurrent), or, in WRITE mode, a decode side channel the prefill cannot reach: a loopback or unspecified decode host (localhost,127.0.0.1,0.0.0.0,[::]) while the prefill is not, or the prefill's own side channel. Under concurrent dispatch the decode engine dials the prefill's side channel as labeled, so the same refusal applies to a loopback or unspecified prefill host while the decode is not. The reason is in the gateway log. Pairing already keeps READ and WRITE workers apart, because their transports aremoriio-readandmoriio-write. - Requests that would share one handoff with 400
moriio_fanout_unsupported:n>1, a batchedpromptorprompt_embedslist, anduse_beam_search. - Request ids carrying peer addresses with 400
moriio_request_id_reserved: the connector reads its peer from markers in the request id (___prefill_addr_,___decode_addr_) before the explicit fields, and vLLM takes the request id fromX-Request-Idor, without that header, from the body'srequest_id. SMG checks everyX-Request-Idvalue it forwards and the body field. - Other routes with 501
moriio_route_unsupported: only/v1/chat/completionsand/v1/completionsare supported.
The connector returns a handoff only when the prefill leg ends at its one-token cap. That token is discarded, so SMG sets ignore_eos and removes stop conditions on the prefill leg; the decode leg keeps the client's. A prefill response whose handoff is missing, carries a transfer_id other than the minted one, or has a field the decode engine cannot parse fails the request with 502 moriio_handoff_invalid: under sequential dispatch no decode leg is sent, and under concurrent dispatch SMG drops the decode leg already in flight. The decode engine's connector parses these fields in its scheduler step, where a value of the wrong shape raises instead of failing one request — a relayed malformed handoff could break the decode engine's scheduling, not just this request. SMG therefore refuses a handoff unless:
remote_engine_idis a non-empty string.remote_block_idsis a flat list of integer block ids, or one list per KV cache group.remote_hostis a non-empty string without whitespace. It is not compared with the prefill worker'smoriio_hostlabel: a hostname or an address on another interface is accepted, and a sequential decode leg dials the address the prefill engine reports. A concurrent decode leg was already told the label.remote_handshake_portandremote_notify_portare non-zero ports, each written as a number or a string.remote_dp_size,remote_dp_size_local,remote_dp_rank,tp_size, andremote_tp_size, when present and notnull, parse as integer counts, as a number or a decimal string.
The gRPC pipeline does not speak MoRI-IO and refuses such pairs with 501 moriio_grpc_pd_unsupported.
Under concurrent dispatch, SMG mints the decode leg's kv_transfer_params up front instead of relaying the prefill's handoff (see Connector Modes): the decode engine dials the side channel named by the prefill worker's moriio_host, moriio_handshake_port, and moriio_notify_port labels, which must therefore match the prefill engine's configuration. SMG still validates the handoff the prefill returns, with one extra check: it must report the same handshake and notify ports the decode leg was told. The decode response — even one that has already arrived — is forwarded only after the handoff passes; otherwise the request fails with 502 moriio_handoff_invalid and SMG drops the decode leg, whose engine would wait for a push that never comes.
With both legs in flight, the first leg to fail ends the request, and SMG drops the other leg, which makes its engine abort it. A prefill error status passes through as prefill_upstream_error, a decode transport error answers 502 decode_request_failed, and a decode engine that refuses the request takes no push, so its error status is returned without waiting for the prefill.
Failures, Cancellation, and Streaming
- Retries re-select both legs. Each attempt picks a new pair under the router's retry settings.
- A failed leg fails fast (gRPC, parallel dispatch). The first leg that fails to start answers the client right away. SMG drops the other leg as soon as its dispatch lands, which aborts its bootstrap room instead of leaving it to the engine's deadline. Over HTTP, a transport error on either leg cancels the other.
- Prefill failures stay on the prefill worker (sequential dispatch). A failed prefill leg never reaches the decode worker's circuit breaker, because decode was never contacted. Under concurrent MoRI-IO WRITE dispatch (see MoRI-IO) both legs are in flight: the first leg to fail answers the client, and the leg SMG drops records no outcome on its worker.
- Decode aborts wait for the handoff (gRPC). When the client disconnects, a prefill leg still running is aborted at once. The decode leg's abort waits for the leg's first response or a terminal event, for at most 30 seconds, to avoid tearing a decode engine down mid-transfer.
- HTTP streams start on the response heads (parallel dispatch). For a streamed request that does not ask for logprobs, SMG starts streaming decode output as soon as both legs return a 2xx response head. It drains the prefill body in the background, because closing it early would abort the KV transfer, and records the prefill worker's outcome when the drain ends. Requests with logprobs wait for the prefill body.
- Non-streaming HTTP responses keep a JSON content type. Streamed HTTP PD responses are sent as
text/event-stream. A non-streaming decode body without logprobs is relayed with the decode worker's response headers, so itsContent-Typecomes from the engine. When the request asks for logprobs, SMG builds the response body itself — the logprob-merged body, or the plain decode body when the prefill body is missing or the merge fails — and setsContent-Type: application/jsonon it, rather than theapplication/octet-streamdefault of a raw byte response.
Parallel Sampling (n>1)
On the gRPC path, a text-only n>1 request to SGLang or TokenSpeed fans out into n single-sample PD dispatches. Each sample gets its own bootstrap room and request id (<id>-<i>); on TokenSpeed, a pinned seed is also offset by the sample index. The dispatches fail fast together, and their responses merge back into one response with one choice per sample. Multimodal requests keep a single dispatch.
The HTTP PD router has no per-sample fan-out: a /v1/completions request with one prompt and n>1 sends every sample to the same rendezvous, and on SGLang the extra samples stall. Serve n>1 SGLang traffic through gRPC workers. vLLM needs no fan-out, because n>1 skips the KV handoff (see above).
Multimodal Requests
Over HTTP, both legs receive the request's media as sent. On the gRPC path:
- The decode leg is a copy of the request without pixel tensors, so pixels travel only to prefill. TokenSpeed decode keeps the per-item metadata it needs.
- vLLM decode keeps each image's identity and its M-RoPE grid tensors (
image_grid_thw,video_grid_thw, and the video timing tensor), so it computes the same positions as prefill. - With worker-side media processing, vLLM processes each image or video once, on the prefill leg. Prefill returns a media identity without pixels, and SMG passes it to decode. With
n>1there is no handoff, so decode processes the media itself. - vLLM decode workers started with
--language-model-onlyreceive only the prefill-expanded token ids, the KV handoff, and per-image content hashes. Requests such a pool cannot serve fail with a non-retryable 400: M-RoPE models (pd_decode_language_model_only_mrope), worker-side media references (pd_decode_language_model_only_media_refs), and multimodaln>1(pd_decode_language_model_only_n_samples).
See Multimodal for media processing modes and tensor transport.
Supported APIs
| API | HTTP PD | gRPC PD |
|---|---|---|
Chat Completions (/v1/chat/completions), Completions (/v1/completions), /generate |
✓ | ✓ |
Anthropic Messages (/v1/messages) |
✓ | ✓ |
Responses (/v1/responses) |
✓ proxied; stored-response features belong to the engine | ✓ |
Messages token counting (/v1/messages/count_tokens) |
✓ one prefill worker, no decode leg | ✓ answered by SMG, no leg involved |
Rerank (/v1/rerank) |
✓ | ✗ |
| Embeddings, classification | ✗ | ✗ |
Token counting generates nothing. Over HTTP, SMG sends it to a single prefill worker and adds no bootstrap fields. Over gRPC, SMG answers it from the model's tokenizer and contacts no leg at all. See the Messages API.
Gateway-side token counting on gRPC PD is newer than v1.12.0: v1.12.0 and earlier answer /v1/messages/count_tokens on gRPC PD with 501 Not Implemented.
Configuration
Flags
| Flag | Default | Description |
|---|---|---|
--pd-disaggregation |
off | Enable PD mode |
--prefill <url> [bootstrap_port] |
— | Prefill worker. Repeat per worker. The optional second value is the worker's bootstrap port (SGLang, TokenSpeed, vLLM Mooncake) or none |
--decode <url> |
— | Decode worker. Repeat per worker |
--prefill-policy |
--policy |
Routing policy for the prefill leg |
--decode-policy |
--policy |
Routing policy for the decode leg |
--pd-pairing-mode |
lenient |
off, lenient, or strict: how strictly the legs must share a KV transfer protocol. See Pairing |
--pd-admission-wait-secs |
30 |
gRPC only: how long a dispatch waits for a free decode slot before it is shed |
--dp-aware |
off | Register one worker per data-parallel rank. vLLM Mooncake needs it to mint engine ids for DP>1 prefill workers |
--model-path, --tokenizer-path |
— | gRPC only: a tokenizer SMG loads at startup, also used for workers that report no tokenizer or model path |
The startup worker lists may be empty: add legs at runtime with POST /workers and "worker_type": "prefill" or "decode" (see Worker Management). For every option, see the configuration reference.
Examples
smg launch \
  --pd-disaggregation \
  --prefill http://prefill-0:8000 8998 \
  --prefill http://prefill-1:8000 8998 \
  --decode http://decode-0:8000 \
  --decode http://decode-1:8000 \
  --prefill-policy cache_aware \
--decode-policy power_of_two# Workers run with --smg-grpc-mode (SGLang 0.5.16+; --grpc-mode before)
smg launch \
--pd-disaggregation \
--prefill grpc://prefill-0:50051 8998 \
--decode grpc://decode-0:50061 \
--model-path meta-llama/Llama-3.1-8B-Instruct# NIXL: no bootstrap port
smg launch \
--pd-disaggregation \
--prefill grpc://prefill-0:50051 \
--decode grpc://decode-0:50052 \
--model-path meta-llama/Llama-3.1-8B-Instruct# Mooncake: pass each prefill worker's VLLM_MOONCAKE_BOOTSTRAP_PORT
smg launch
--pd-disaggregation
--prefill grpc://prefill-0:50051 8998
--prefill grpc://prefill-1:50051 8999
--decode grpc://decode-0:50052
--model-path meta-llama/Llama-3.1-8B-Instruct
# Start PD mode without startup workers...
smg launch --pd-disaggregation --host 0.0.0.0 --port 30000
# ...then register each leg with its KV connector
curl -X POST http://localhost:30000/workers
  -H "Content-Type: application/json"
  -d '{"url": "http://prefill-0:8000", "worker_type": "prefill", "kv_connector": "NixlConnector"}'
curl -X POST http://localhost:30000/workers
  -H "Content-Type: application/json"
  -d '{"url": "http://decode-0:8000", "worker_type": "decode", "kv_connector": "NixlConnector"}'
smg launch
  --pd-disaggregation
  --prefill grpc://prefill-0:50051 8998
  --decode grpc://decode-0:50052
  --model-path meta-llama/Llama-3.1-8B-Instruct
Worker launch commands for each engine are in Getting Started: PD Disaggregation.
Per-Phase Policies
The prefill and decode legs each run their own policy instance, so a stateful policy such as round_robin keeps a separate rotation per leg. The prefill policy chooses among prefill workers that have an available compatible decode worker, then the decode policy chooses among that prefill's compatible decode workers. A leg without its own policy uses --policy. Both legs take the same tuning flags as --policy, such as --cache-threshold or the --least-load-* flags.
| Policy | Prefill | Decode | Notes |
|---|---|---|---|
cache_aware |
✓ | ✓ | Prompt-prefix affinity; the prompt's KV cache is computed on prefill |
prefix_hash, consistent_hashing |
✓ | ✓ | Hash-based affinity |
power_of_two, least_load |
✓ | ✓ | Load-based. At startup, --prefill-policy power_of_two or --decode-policy power_of_two needs at least two workers on that leg (not checked with service discovery or --enable-igw) |
round_robin, random |
✓ | ✓ | Even or random spread |
manual |
✓ | ✓ | Sticky keys are tracked per leg |
bucket |
✓ | ✗ | Rejected as a decode policy at startup |
smg launch \
  --pd-disaggregation \
  --prefill http://prefill-0:8000 8998 \
  --prefill http://prefill-1:8000 8998 \
  --decode http://decode-0:8000 \
  --decode http://decode-1:8000 \
  --prefill-policy cache_aware \
  --decode-policy least_load
Prefill/Decode Pairing
A prefill worker can hand its KV cache only to a decode worker that speaks the same KV transfer protocol. SMG gives each prefill and decode worker a pairing descriptor and pairs a prefill only with decode workers whose descriptor is compatible. Compatibility is worked out when workers join or leave, not on every request.
What Is Compared
| Component | Source |
|---|---|
| Runtime | The detected engine: sglang, vllm, or tokenspeed |
| Transport | vLLM: the worker's KV connector, reduced to nixl, mooncake, or moriio (any other connector name is compared as is, lower-cased). A moriio worker with a moriio_mode label becomes moriio-read or moriio-write; v1.11.0 has neither and compares moriioconnector as is. SGLang: the disaggregation_transfer_backend label. TokenSpeed: the same label, mooncake when absent |
| KV layout | The kv_cache_dtype, page_size (vLLM's block_size), attention_backend, and model_dtype labels, each compared on its own |
| Engine version | The version label. Compared only in strict mode, and only when both legs report one |
gRPC workers report these facts at registration. SGLang reports its transfer backend, kv_cache_dtype, page_size, attention_backend, and version. TokenSpeed reports the same except page_size. vLLM reports its connector, kv_cache_dtype, block_size, attention_backend, and model_dtype, but no version. HTTP workers report no transport or KV layout, only the runtime and engine version, so an HTTP vLLM worker's transport comes from its registered kv_connector.
GET /workers shows each prefill and decode worker's key in pd_pairing: the explicit protocol if one is set, otherwise runtime/transport/layout with ? for an unknown part, for example vllm/nixl/dtype=auto,page=16,attn=flash_attn,model=torch.bfloat16. The version is not part of the key.
Pairing Modes
--pd-pairing-mode |
A prefill and a decode do not pair when |
|---|---|
off |
Never. Every prefill may pair with every decode, although gRPC still keeps both legs on one runtime |
lenient (default) |
Both legs report a runtime, transport, or KV layout fact and the values differ. Unknown components and engine versions are ignored |
strict |
As lenient, and also when the runtime or transport is unknown on either leg, a KV layout fact is reported by only one leg, only one leg has an explicit protocol, or the legs report different engine versions |
lenient keeps a fleet that reports nothing pairing as before, and lets a rolling engine upgrade mix versions. Under strict, HTTP workers need an explicit protocol (or, for vLLM, a registered kv_connector), because they report no transport.
Explicit Pairing Protocol
Set a pairing protocol to declare compatibility yourself. Two legs that both carry one pair only when the values are equal, and nothing except the runtime is compared. When only one leg carries one, lenient falls back to the derived facts and strict refuses the pair. SMG reads it from these sources, highest precedence first:
- A
pairing_protocolworker label, for example in thelabelsofPOST /workers. - The
SMG_PAIRING_PROTOCOLenvironment variable of the engine process. The vLLM, SGLang, and TokenSpeed gRPC servicers report it in their server info.
The worker spec also has a pairing_protocol field, but v1.11.0 does not apply it when it registers the worker; use the label instead.
On Kubernetes, set SMG_PAIRING_PROTOCOL in the engine container; there is no pod annotation for it.
When no prefill shares a protocol with any decode, requests fail with 503 no_compatible_pd_pair. The message names the components that differ and each leg's keys, and SMG logs the same at warn level. A prefill worker with no compatible decode is skipped as long as other prefill workers can pair.
Admission and Errors
Decode Admission Window (gRPC)
Before a gRPC PD or EPD dispatch goes out, SMG claims one room for each backend request on the decode worker, within the running window that engine reports: SGLang's max_running_requests or TokenSpeed's max_num_seqs (the engines' --max-running-requests and --max-num-seqs flags). When the window is full, the request waits up to --pd-admission-wait-secs (default 30) and is then shed with 503 worker_overload_protection_shed and a Retry-After header. 0 sheds immediately. Keep the wait well under the engine's bootstrap deadline (120 seconds on TokenSpeed). Decode workers that report no window, such as vLLM, are not gated. smg_pd_admission_waits_total counts dispatches admitted after a wait, and smg_pd_admission_sheds_total counts the sheds. See Overload Protection.
Context Length (gRPC)
On the gRPC path, SMG counts the prompt tokens itself and rejects a prompt longer than the model's context window with 400 context_length_exceeded before dispatch. In PD mode the smaller window of the two legs applies. Workers that advertise no window are not checked, and the HTTP path leaves the check to the engine.
Error Codes
| Status | Code | Meaning |
|---|---|---|
| 503 | no_available_workers |
A leg has no available worker (unhealthy or circuit open). Over HTTP, the message names the leg. Same code as the regular HTTP and gRPC routers |
| 503 | no_compatible_pd_pair |
No prefill shares a KV transfer protocol with any decode |
| 503 | worker_overload_protection_shed |
The decode admission window stayed full, or overload protection vetoed a leg. Sent with Retry-After |
| 400 | context_length_exceeded |
gRPC: the prompt exceeds the smaller context window of the two legs |
| 400 | runtime_pd_not_supported |
gRPC: the selected runtime has no PD protocol |
| Engine status | prefill_worker_failed_to_start, decode_worker_failed_to_start |
gRPC: the engine refused that leg |
| Upstream status | prefill_upstream_error |
vLLM over HTTP: the prefill worker returned an error status, which SMG passes through |
| 503 | moriio_pair_misconfigured |
vLLM MoRI-IO over HTTP: the selected pair is not configured for MoRI-IO. The reason is in the gateway log |
| 400 | moriio_fanout_unsupported |
MoRI-IO: n>1, a batched prompt or prompt embeddings, or beam search |
| 400 | moriio_request_id_reserved |
MoRI-IO: a request id carries the connector's peer-address markers |
| 501 | moriio_route_unsupported |
MoRI-IO: the route is not /v1/chat/completions or /v1/completions |
| 502 | moriio_handoff_invalid |
MoRI-IO: the prefill returned no usable handoff — missing, foreign, or with fields the decode engine cannot parse. Sequential dispatch sends no decode leg; concurrent dispatch drops the one already sent |
| 501 | moriio_grpc_pd_unsupported |
gRPC: MoRI-IO PD is supported only by the HTTP PD router |
The moriio_* codes are newer than v1.11.0.
/readiness reports ready only when at least one prefill worker and one decode worker are healthy (and an encode worker in EPD mode).
EPD (Encode-Prefill-Decode)
EPD adds a third worker role for multimodal models. Encode workers run the vision tower, and prefill and decode workers run the language model. SMG assigns each media item to an encode worker, the encode worker ships the resulting embeddings to the prefill worker over Mooncake, and prefill and decode then proceed as in PD. EPD requires gRPC workers running TokenSpeed; SMG refuses to start an EPD router for HTTP workers.
| Flag | Default | Description |
|---|---|---|
--epd-disaggregation |
off | Enable EPD mode (instead of --pd-disaggregation) |
--encode <url> [bootstrap_port] |
— | Encode worker. Repeat per worker. The port is the encode worker's Mooncake bootstrap port, where prefill reads the embeddings (8998 when omitted) |
--prefill <url> [bootstrap_port], --decode <url> |
— | Prefill and decode workers, as in PD mode |
--encode-policy |
consistent_hashing |
random, round_robin, or consistent_hashing. The default keys each media item by its content hash, so a repeated image goes to the same encode worker |
--encode-selector |
— | Kubernetes label selector for encode pods. EPD discovery needs all three role selectors |
smg launch \
  --epd-disaggregation \
  --encode grpc://encode-0:50060 8995 \
  --prefill grpc://prefill-0:50061 8998 \
  --decode grpc://decode-0:50062 \
--model-path "$MODEL"- Each media item gets its own encode worker and rendezvous, so the items of one request can be encoded on different workers.
- Text-only requests skip the encode leg.
- SMG preprocesses the media for the encode workers. Encode workers never take raw media references, so with
--mm-processing workeran EPD request that carries media fails with 400multimodal_not_supported. - EPD mode does not serve
/v1/responses(501). - EPD keeps all three legs on one runtime but does not apply
--pd-pairing-mode.
Worker launch commands are in Getting Started: PD Disaggregation.
Kubernetes Service Discovery
smg launch \
  --service-discovery \
  --pd-disaggregation \
  --prefill-selector app=sglang role=prefill \
  --decode-selector app=sglang role=decode \
  --service-discovery-namespace inference \
  --service-discovery-port 8000 \
  --prefill-policy cache_aware \
  --decode-policy least_load
SMG assigns each pod the role of the selector it matches. Prefill (and encode) pods advertise their bootstrap port with the sglang.ai/bootstrap-port annotation. vLLM pods declare their KV connector and engine id with the smg.ai/kv-connector and smg.ai/kv-engine-id annotations. Service discovery turns on IGW mode automatically; PD and EPD mode and the per-role policies are kept. See PD Disaggregation Discovery for the annotation formats and a pod example.
Sizing Guidelines
Prefill Workers
Prefill is compute-bound. Its cost grows with prompt length, and every request's time to first token includes the prefill and the KV transfer. Add prefill capacity when time to first token (smg_pd_ttft_seconds) climbs while the decode workers have headroom.
Decode Workers
Decode is memory-bandwidth-bound. Its throughput depends on how many sequences fit in the decode batch, which the KV cache capacity limits. Add decode capacity when dispatches wait for or are shed at the decode admission window (smg_pd_admission_waits_total, smg_pd_admission_sheds_total), or when time per output token grows.
Prefill:Decode Ratio
Long prompts with short outputs need relatively more prefill capacity. Short prompts with long outputs need relatively more decode capacity. Start from your workload's prompt and output lengths, then scale each pool independently based on the signals above.
Monitoring
PD Metrics
| Metric | Type | Labels | Recorded |
|---|---|---|---|
smg_pd_ttft_seconds |
Histogram | backend_type, model, runtime |
Prefill dispatch to the first decode output. HTTP PD, and gRPC streaming on SGLang and TokenSpeed pairs |
smg_pd_prefill_duration_seconds |
Histogram | backend_type, model, runtime |
Prefill-leg duration. HTTP PD and gRPC vLLM |
smg_pd_kv_transfer_duration_seconds |
Histogram | backend_type, model, runtime |
Prefill completion to decode dispatch. gRPC vLLM |
smg_pd_kv_connector_mode_total |
Counter | mode (nixl, mooncake, moriio, passthrough; moriio is newer than v1.11.0) |
vLLM dispatches, sequential and MoRI-IO concurrent |
smg_pd_kv_transfer_failures_total |
Counter | — | A NIXL prefill returned no kv_transfer_params, so decode recomputed the prompt; or, newer than v1.11.0, a MoRI-IO pair or handoff check failed, so the request failed |
smg_pd_bootstrap_failures_total |
Counter | — | HTTP bootstrap injection failed |
smg_pd_admission_waits_total |
Counter | — | gRPC dispatches admitted after waiting for a decode slot |
smg_pd_admission_sheds_total |
Counter | — | gRPC dispatches shed at the decode admission window |
Related series:
smg_worker_selection_totalcounts picks per leg (worker_typeisprefill,decode, orencode), withconnection_mode,model, andpolicylabels.smg_worker_requests_activeshows in-flight requests per worker (workerlabel).smg_router_ttft_secondswithbackend_type="pd"(gRPC) measures only the decode leg. Usesmg_pd_ttft_secondsfor the time the client waits.smg_engine_pd_kv_transfer_latency_ms,smg_engine_pd_kv_transfer_speed_gb_s,smg_engine_pd_prefill_queue_reqs, andsmg_engine_pd_decode_queue_reqs(labelsworker,role,dp_rank) are published when an engine's load report includes disaggregation statistics, as the SGLang gRPC servicer's does.
See the Metrics Reference for every metric.
PromQL Queries
Time to First Token
# p95 PD time to first token by model
histogram_quantile(0.95,
  sum by (le, model) (rate(smg_pd_ttft_seconds_bucket[5m])))
vLLM Dispatches Without a KV Connector
# Share of vLLM PD dispatches running passthrough
sum(rate(smg_pd_kv_connector_mode_total{mode="passthrough"}[5m]))
  / sum(rate(smg_pd_kv_connector_mode_total[5m]))
Decode Admission Sheds
# gRPC PD dispatches shed at the decode window
rate(smg_pd_admission_sheds_total[5m])
Active Requests by Worker
# In-flight requests per worker
smg_worker_requests_activeTroubleshooting
| Symptom | Cause | Solution |
|---|---|---|
503 no_available_workers |
A leg has no healthy worker with a closed circuit (over HTTP, the message names it) | Check /workers; restore or add workers on that leg |
503 no_compatible_pd_pair |
No prefill shares a KV transfer protocol with any decode | Compare the pd_pairing keys in /workers; align the engines or set a shared pairing protocol |
503 worker_overload_protection_shed |
The decode admission window stayed full, or a leg is overloaded | Add decode workers or raise the engine's running window |
400 context_length_exceeded (gRPC) |
The prompt exceeds the smaller context window of the two legs | Shorten the prompt or give both legs the same context length |
| vLLM PD answers correctly but decode recomputes prompts | The prefill worker has no KV connector (mode="passthrough"), or a NIXL prefill returned no params (smg_pd_kv_transfer_failures_total) |
Register HTTP workers with kv_connector; check --kv-transfer-config; upgrade the servicer |
SGLang n>1 completions stall over HTTP |
The HTTP PD router has no per-sample fan-out | Serve n>1 traffic through gRPC workers |
| High TTFT with idle decode workers | The prefill pool is saturated | Add prefill workers |
Debug Logging
RUST_LOG=smg=info,smg::routers=debug smg launch --pd-disaggregation ...At debug level SMG logs each selected pair and, on the gRPC vLLM path, whether it relayed the prefill's kv_transfer_params.
Verify Configuration
# Role, health, and pairing key of every worker
curl -s http://localhost:30000/workers | jq '.workers[] | {url, worker_type, is_healthy, pd_pairing}'

# Ready only when both legs have a healthy worker
curl -i http://localhost:30000/readiness