PD Disaggregation
Prefill-Decode (PD) disaggregation runs the two phases of LLM inference on separate workers. Prefill workers process the prompt and build its KV cache. Decode workers take over that cache and generate the output tokens. For every request, SMG picks a prefill/decode pair, runs the KV handoff the way the engine expects, and returns the decode worker's output to the client.
Overview
Optimized TTFT
Prefill workers only process prompts, so a new prompt never waits behind a decode batch.
Optimized TPOT
Decode workers only generate tokens, so their batches are not interrupted by prompt processing.
Independent Scaling
Size and scale the prefill and decode pools separately, each with its own routing policy.
KV Handoff
SMG speaks each engine's handoff protocol: bootstrap rooms for SGLang and TokenSpeed, kv_transfer_params relay for vLLM.
Why Disaggregate?
Traditional LLM inference has two distinct phases with different characteristics:
| Phase | Compute Pattern | Bottleneck | Optimization |
|---|---|---|---|
| Prefill | Compute-bound, parallel | GPU compute | Batch similar-length prompts |
| Decode | Memory-bound, sequential | Memory bandwidth | Maximize batch size |
Running both phases on the same worker creates inefficiencies:
- Prefill batches are delayed waiting for decode slots
- Decode batches are small due to prefill memory pressure
- Neither phase is optimally configured
PD disaggregation solves this by dedicating workers to each phase.
Supported Engines
| Engine | Worker transport | Dispatch | KV transfer |
|---|---|---|---|
| SGLang | HTTP or gRPC | Parallel, bootstrap room | Mooncake or NIXL (engine flag --disaggregation-transfer-backend) |
| vLLM | HTTP or gRPC | Sequential, kv_transfer_params relay; MoRI-IO WRITE optionally concurrent |
NixlConnector or MooncakeConnector (engine flag --kv-transfer-config); MoRIIOConnector over HTTP; shared-store connectors |
| TokenSpeed | gRPC or direct ZMQ | Parallel, KV bootstrap room | Mooncake |
- The worker URL scheme selects the path.
http://workers go through the HTTP PD router, which forwards the client's JSON body to both legs and adds the handoff fields.grpc://workers go through the gRPC pipeline, where SMG tokenizes the prompt and parses the output itself. - Other runtimes have no PD protocol. TensorRT-LLM and MLX cannot serve as PD legs. A gRPC PD request that lands on another runtime fails with 400
runtime_pd_not_supported. - Direct ZMQ legs are TokenSpeed only. A TokenSpeed engine on the direct ZMQ lane can serve as a prefill, decode, or encode leg: its wire carries the rendezvous and the encode request, and its legs rendezvous at the bootstrap address the engine declares at its handshake unless the worker was registered with one. A ZMQ worker (
ipc://ortcp://) of any other runtime registered for one of those roles fails registration: as a prefill or decode leg because its wire carries no KV-transfer metadata, as an encode leg because its backend has no encode path. See ZMQ Workers. - EPD adds an encode leg. For multimodal models on TokenSpeed and vLLM, EPD moves the vision tower onto separate encode workers.
How It Works
Parallel Dispatch (SGLang, TokenSpeed)
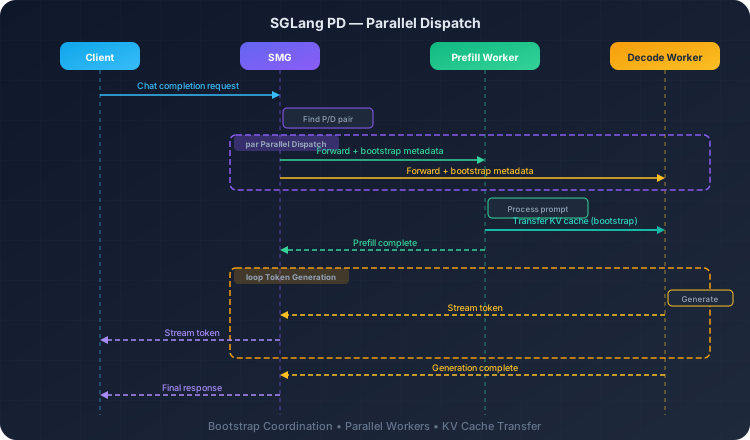
- Select a pair. The prefill policy picks a prefill worker, then the decode policy picks one of the decode workers that can pair with it (see Pairing).
- Mint a rendezvous. SMG generates a bootstrap room and points both legs at the prefill worker's bootstrap server: its host and the bootstrap port the worker was registered with. Over HTTP, SMG adds
bootstrap_host,bootstrap_port, andbootstrap_roomto the JSON body of both legs. Over gRPC, SGLang receives them as disaggregation parameters and TokenSpeed as KV bootstrap fields. - Dispatch both legs at once. The engines use the room to find each other, and the prefill engine transfers the KV cache it computes to the decode engine.
- Stream the decode output back to the client.
Register every prefill worker with its bootstrap port (--prefill <url> <port>). Over gRPC, a prefill worker without one is addressed on port 8998. Over HTTP, SMG forwards the registered value as it is. A TokenSpeed worker on the direct ZMQ lane without one is addressed at the bootstrap address its engine declared at the handshake; an engine that declares none fails the worker's connection with an error naming the gap, so a direct-ZMQ prefill leg never falls back to a default port.
With --dp-aware, SGLang legs carry the DP rank of the selected worker. Over HTTP, SMG also mints every room — the request's single room, or one per prompt in a batch — to land on the selected prefill worker's rank: SGLang's prefill engine, under its default follow_bootstrap_room placement, fails a request whose bootstrap_room % dp_size is not the rank it runs on. Over gRPC, SGLang legs carry the rank in their data_parallel_rank field, and the room is unconstrained. TokenSpeed places both legs by bootstrap_room % dp_size, so SMG mints the room to land on the prefill worker's rank.
Once an HTTP or gRPC prefill or encode worker is registered, SMG probes the bootstrap port its partners will be handed — the registered port, or the default 8998 for a worker registered without one — at the worker URL's host, with a single TCP connection and a 2-second timeout. A worker on the direct ZMQ lane is never probed: its ipc:// or tcp:// URL names the gateway's own ZMQ bind, not a rendezvous host, so there is no address to probe (its legs rendezvous as described under Supported Engines). The probe runs in the background and is not a registration gate: the worker is registered and serves whether or not the port answers. A port that does not accept the connection is reported once: a gateway warning names the worker, the port and its source (registered or default), and the error; the failure is counted in smg_pd_rendezvous_failures_total{phase="probe"} (see Monitoring).
A vLLM prefill worker registered without a port is probed only on the Mooncake connector; on any other connector, or none, its partners are handed no bootstrap port and there is nothing to probe. A port registered on a prefill worker whose KV connector writes to a shared store is reported unused instead of probed: its decode partners read the KV blocks back from the store, and no rendezvous happens on the port.
Sequential Dispatch (vLLM)
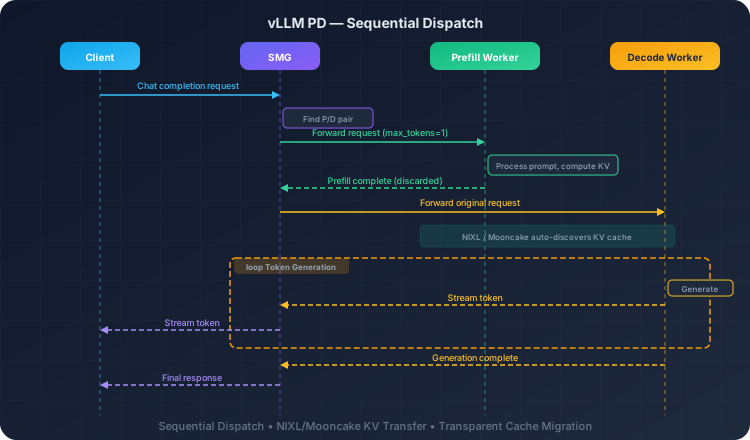
- Send prefill a one-token request. The prefill leg carries the prompt with the output capped at one token, streaming off, and
nset to 1. Over HTTP, SMG sets the endpoint's own cap field (max_tokens,max_completion_tokenswhen the chat request used it, ormax_output_tokenson/v1/responses) and dropsmin_tokensandstream_options. It also tags the leg with the connector'skv_transfer_params(see below). - Wait for prefill to finish. The prefill engine computes the KV cache and holds it for the handoff.
- Relay the handoff. SMG adds
kv_transfer_paramsto the original request and sends it to decode. - Decode receives the KV cache from prefill and streams tokens back to the client.
Connector Modes
The prefill worker's KV connector decides how SMG tags the prefill leg and what the decode leg carries:
| Prefill connector | Prefill leg | Decode leg kv_transfer_params |
|---|---|---|
NixlConnector |
{"do_remote_decode": true, "do_remote_prefill": false} |
The params the prefill response returns (for example remote_engine_id, remote_request_id, remote_block_ids, remote_host/remote_port, tp_size), forwarded verbatim |
MooncakeConnector |
The same tag plus a transfer_id that SMG mints |
Synthesized by SMG, because Mooncake pushes the KV and returns nothing: {"do_remote_decode": false, "do_remote_prefill": true} plus transfer_id, remote_engine_id (the prefill's KV engine id), and remote_bootstrap_addr = http://<bootstrap_host>:<bootstrap_port> (port 8998 when the worker has none) |
MoRIIOConnector (HTTP) |
The same tag plus a minted transfer_id, the decode's remote_dp_size, the pinned remote_dp_rank for DP>1, and the decode's TP as remote_tp_size when the decode has a tp_size label. WRITE mode also names the decode's side channel: remote_host, remote_handshake_port, remote_notify_port. The leg also gets ignore_eos: true and loses stop and stop_token_ids |
The params the prefill response returns, forwarded verbatim only after SMG checks that they carry the minted transfer_id and the prefill peer (remote_engine_id, remote_block_ids, remote_host, remote_handshake_port, remote_notify_port), each in a shape the decode engine parses. Under concurrent WRITE dispatch, minted up front by SMG instead: {"do_remote_decode": false, "do_remote_prefill": true} plus the minted transfer_id, the prefill's remote_dp_size, the pinned remote_dp_rank for DP>1, the prefill's side channel (remote_host, remote_handshake_port, remote_notify_port), and the prefill's tp_size label as remote_tp_size when set. See MoRI-IO |
A store connector (MooncakeStoreConnector, SharedStorageConnector, the FlexKV and HF3FS families) |
No tag | Whatever params the prefill response returns, relayed for a store that runs a handoff of its own. The legs meet in the shared store — the decode engine reads the prefill's blocks back by prefix hash — so SMG mints nothing and only orders decode after prefill |
| None or another connector | No tag ("passthrough") | Whatever kv_transfer_params the prefill response returns, if any |
The handoff falls back to a local recompute in these cases:
- NIXL prefill returns nothing. SMG increments
smg_pd_kv_transfer_failures_totaland decode recomputes the prompt. The usual causes are an outdated servicer or a worker without--kv-transfer-config. - Mooncake without an engine id. Minting needs the prefill's KV engine id. Without it, gRPC falls back to injecting the bootstrap host and port, and over HTTP decode recomputes the prompt.
n>1. The handoff is single-consumer, so no KV is handed off and decode computes the prompt itself. Over HTTP, SMG skips the prefill leg entirely. Over gRPC, the prefill leg still runs, untagged, and a Mooncake decode leg still receives the legacy bootstrap host and port.
A MoRI-IO decode engine never recomputes the prompt, so MoRI-IO has no such fallback: SMG fails the request instead (see MoRI-IO).
Where the Connector Comes From
| Worker transport | Source |
|---|---|
| gRPC | The vLLM servicer reports kv_connector, kv_role, and kv_engine_id from the engine's --kv-transfer-config. A MultiConnector is reported as the child that moves the KV between the legs — its one NixlConnector, MooncakeConnector, or MoRIIOConnector child, or its one store child when it wraps none of those — with the child's engine id (or the parent's when the child sets none); a MoRIIOConnector child beside a single store child steps aside for the store. Any other MultiConnector stays passthrough. |
| HTTP | The vLLM OpenAI server reports no connector, so set it when you register the worker: the kv_connector field of POST /workers (plus kv_engine_id and bootstrap_port for Mooncake), or the smg.ai/kv-connector and smg.ai/kv-engine-id pod annotations under service discovery. A vLLM HTTP worker registered by URL alone runs passthrough, and decode recomputes every prompt. |
A restarted vLLM process without a pinned engine_id comes back with a new KV engine id. When a gRPC prefill worker recovers from the failed or not-ready state, SMG re-reads its engine id before routing to it again. Workers registered over HTTP keep the engine id they were registered with.
MoRI-IO (HTTP)
vLLM's MoRIIOConnector moves the KV cache over RDMA with MoRI-IO in one of two modes. In READ mode ("read_mode": true in kv_connector_extra_config on both engines), the decode engine pulls the KV after the prefill leg returns. In WRITE mode, the default, the prefill engine pushes the KV into blocks the decode engine allocates. SMG sends the legs sequentially by default in both modes; a WRITE pair can opt into concurrent dispatch with the decode worker's moriio_write_dispatch label (see below).
One TP size must be a multiple of the other, both engines must use the same number of tokens per attention block, and each TP size must divide or be divisible by the model's KV head count. For hybrid models whose automatic block size changes with TP, set the same --block-size on both engines, at least the larger of their automatic sizes. On a single node, the xGMI backend still cannot serve WRITE with a larger decode TP than prefill TP; the required sessions to additional decode GPUs cannot be opened. A larger prefill TP works on xGMI. The RDMA backend does not have this xGMI restriction.
The validated heterogeneous-TP WRITE configurations use deepseek-ai/DeepSeek-R1-0528 (FP8 weights and fp8 KV), TP4 → TP8 and TP8 → TP4, on two MI355X nodes over RDMA. Other GPUs, xGMI, and combined heterogeneous TP with DP>1 require separate validation.
A MoRI-IO decode engine never recomputes the prompt. Without a valid handoff it answers with text computed over KV that never arrived (READ) or waits for a push that never comes (WRITE). SMG therefore takes the MoRI-IO path whenever the decode worker is a MoRIIOConnector worker, and fails a request rather than sending a decode leg without its handoff.
HTTP vLLM workers report none of the MoRI-IO settings, so set them as worker labels when you register each leg, matching the engine's kv_connector_extra_config:
| Label | Default | Meaning |
|---|---|---|
moriio_mode |
none (required) | read or write. Both legs of a pair must use the same mode |
moriio_host |
The worker URL's host | The address on which the peer engine reaches this worker's MoRI-IO side channel (used in WRITE mode). The prefill engine pushes to the decode worker's; under concurrent dispatch the decode engine also dials the prefill worker's |
moriio_handshake_port |
6301 |
The engine's handshake_port |
moriio_notify_port |
61005 |
The engine's notify_port |
moriio_write_dispatch |
sequential |
sequential or concurrent: whether SMG sends the two WRITE legs one after the other or at once. Honored on the decode worker; a READ pair stays sequential. Any other value on either worker refuses the pair |
tp_size |
Unset: both legs have the same TP | The engine's tensor-parallel size. The decode's value is sent to prefill as remote_tp_size; under concurrent dispatch, the prefill's value is likewise sent to decode. For different TP sizes, label both workers and meet the vLLM build requirement above |
dp_size |
The worker's DP size, otherwise 1 |
The engine's data-parallel size. Both engines must have the same value. Register each engine once; rank-expanded --dp-aware workers are unsupported |
For DP>1, SMG selects one rank per request, round-robin, and pins both legs to it with X-data-parallel-rank. It also includes that rank in the transfer params and rejects a handoff from another rank. This applies to READ, sequential WRITE and concurrent WRITE. For DP1, SMG sends no rank header and keeps remote_dp_size: 1.
If either engine combines DP>1 with TP>1, both engines additionally need the MoRI-IO port-offset correction from vLLM source revision 4e123050ee6ff2a8c86ccf678735380ad87eea6f, or an equivalent backport. Listeners and peer notifications must consistently use the listening instance's TP size in dp_rank * tp_size + tp_rank. Without that correction, two ranks can bind the same port or notifications can reach the wrong rank. The separate DP8/TP1 and DP1 heterogeneous-TP results do not exercise this combined configuration.
For example, register two engines already configured with DP8 and TP1 as follows. These labels describe the running engines; they do not configure vLLM. For DP1, omit dp_size or set it to "1" on both registrations.
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{"url": "http://prefill-0:8000", "worker_type": "prefill", "runtime_type": "vllm",
       "kv_connector": "MoRIIOConnector",
       "labels": {"moriio_mode": "write", "dp_size": "8", "tp_size": "1"}}'
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{"url": "http://decode-0:8000", "worker_type": "decode", "runtime_type": "vllm",
       "kv_connector": "MoRIIOConnector",
       "labels": {"moriio_mode": "write", "dp_size": "8", "tp_size": "1"}}'
The engines do not need proxy_ip and proxy_ping_port, which only register them with vllm-router.
DP8 with expert parallelism was validated separately on two MI355X nodes with deepseek-ai/DeepSeek-R1-0528 (FP8), vLLM ac68c3087 and MoRI v1.2.3.post1: READ and both WRITE dispatch modes completed with the legs pinned to the same rotating rank, full KV transfer over RoCE and no cross-request output. This DP result and the heterogeneous-TP result above cover separate configurations.
Before either leg is contacted, SMG refuses:
- A misconfigured pair with 503
moriio_pair_misconfigured: a leg that is not aMoRIIOConnectorworker, legs in different modes, engines with differentdp_sizevalues, rank-expanded--dp-awareworkers, a missing, unparsable, or invalid label (including amoriio_write_dispatchvalue other thansequentialorconcurrent), or, in WRITE mode, a decode side channel the prefill cannot reach: a loopback or unspecified decode host (localhost,127.0.0.1,0.0.0.0,[::]) while the prefill is not, or the prefill's own side channel. Under concurrent dispatch the decode engine dials the prefill's side channel as labeled, so the same refusal applies to a loopback or unspecified prefill host while the decode is not. The reason is in the gateway log. Pairing already keeps READ and WRITE workers apart, because their transports aremoriio-readandmoriio-write. - Requests that would share one handoff with 400
moriio_fanout_unsupported:n>1, a batchedpromptorprompt_embedslist, anduse_beam_search. - Request ids carrying peer addresses with 400
moriio_request_id_reserved: the connector reads its peer from markers in the request id (___prefill_addr_,___decode_addr_) before the explicit fields, and vLLM takes the request id fromX-Request-Idor, without that header, from the body'srequest_id. SMG checks everyX-Request-Idvalue it forwards and the body field. - Other routes with 501
moriio_route_unsupported: only/v1/chat/completionsand/v1/completionsare supported.
The connector returns a handoff only when the prefill leg ends at its one-token cap. That token is discarded, so SMG sets ignore_eos and removes stop conditions on the prefill leg; the decode leg keeps the client's. A prefill response whose handoff is missing, carries a transfer_id other than the minted one, or has a field the decode engine cannot parse fails the request with 502 moriio_handoff_invalid: under sequential dispatch no decode leg is sent, and under concurrent dispatch SMG drops the decode leg already in flight. The decode engine's connector parses these fields in its scheduler step, where a value of the wrong shape raises instead of failing one request — a relayed malformed handoff could break the decode engine's scheduling, not just this request. SMG therefore refuses a handoff unless:
remote_engine_idis a non-empty string.remote_block_idsis one list per KV cache group, containing non-negative JSON integer block ids and at least one block overall. Flat lists are refused.remote_hostis a non-empty string without whitespace. It is not compared with the prefill worker'smoriio_hostlabel: a hostname or an address on another interface is accepted, and a sequential decode leg dials the address the prefill engine reports. A concurrent decode leg was already told the label.remote_handshake_portandremote_notify_portare non-zero ports, each written as a number or a string.remote_dp_size,remote_dp_size_local,remote_dp_rank,tp_size, andremote_tp_size, when present and notnull, are non-negative JSON integers. Decimal strings, floats and booleans are refused. These handoff fields differ from worker labels, whose values are strings.- For DP>1,
remote_dp_rankmust equal the rank SMG selected for both legs.
The gRPC pipeline does not speak MoRI-IO and refuses such pairs with 501 moriio_grpc_pd_unsupported.
Under concurrent dispatch, SMG mints the decode leg's kv_transfer_params up front instead of relaying the prefill's handoff (see Connector Modes): the decode engine dials the side channel named by the prefill worker's moriio_host, moriio_handshake_port, and moriio_notify_port labels, which must therefore match the prefill engine's configuration. SMG still validates the handoff the prefill returns, with one extra check: it must report the same handshake and notify ports the decode leg was told. The decode response — even one that has already arrived — is forwarded only after the handoff passes; otherwise the request fails with 502 moriio_handoff_invalid and SMG drops the decode leg, whose engine would wait for a push that never comes.
With both legs in flight, the first leg to fail ends the request, and SMG drops the other leg, which makes its engine abort it. A prefill error status passes through as prefill_worker_failed_to_start, a decode transport error answers 502 decode_worker_failed_to_start, and a decode engine that refuses the request takes no push, so its error status is returned under the same code without waiting for the prefill.
Failures, Cancellation, and Streaming
- Retries re-select both legs. Each attempt picks a new pair under the router's retry settings.
- A failed leg fails fast (gRPC, parallel dispatch). The first leg that fails to start answers the client right away. SMG drops the other leg as soon as its dispatch lands, which aborts its bootstrap room instead of leaving it to the engine's deadline. Over HTTP, a transport error on either leg cancels the other.
- Prefill failures stay on the prefill worker (sequential dispatch). A failed prefill leg never reaches the decode worker's circuit breaker, because decode was never contacted. Under concurrent MoRI-IO WRITE dispatch (see MoRI-IO) both legs are in flight: the first leg to fail answers the client, and the leg SMG drops records no outcome on its worker.
- Decode aborts wait for the handoff (gRPC). When the client disconnects, a prefill leg still running is aborted at once. The decode leg's abort waits for the leg's first response or a terminal event, for at most 30 seconds, to avoid tearing a decode engine down mid-transfer.
- A refused vLLM decode request still frees the prefill side's blocks (gRPC). A decode request refused before its engine holds it — an invalid parameter, or a client that gives up while the worker is still admitting the request (a media fetch can take seconds) — would leave the prefill side's KV blocks pinned for the handoff. The vLLM gRPC worker therefore sends its engine the same release notice vLLM's own frontend would send, so those blocks are freed right away; once the engine holds the request, the engine's own abort covers it. Where a Mooncake connector runs in the decode engine (the top-level connector of
--kv-transfer-config, or any child aMultiConnectorlists, at any depth), the notice is withheld and the worker logs one warning line,KV-transfer rejection notice withheld on the Mooncake connector; the prefill side's blocks are released at the connector's own abort timeout instead. - HTTP streams start on the response heads (parallel dispatch). For a streamed request that does not ask for logprobs, SMG starts streaming decode output as soon as both legs return a 2xx response head. It drains the prefill body in the background, because closing it early would abort the KV transfer, and records the prefill worker's outcome when the drain ends. Requests with logprobs wait for the prefill body.
- Non-streaming HTTP responses keep a JSON content type. Streamed HTTP PD responses are sent as
text/event-stream. A non-streaming decode body without logprobs is relayed with the decode worker's response headers, so itsContent-Typecomes from the engine. When the request asks for logprobs, SMG builds the response body itself — the logprob-merged body, or the plain decode body when the prefill body is missing or the merge fails — and setsContent-Type: application/jsonon it, rather than theapplication/octet-streamdefault of a raw byte response.
Parallel Sampling (n>1)
On the gRPC path, a text-only n>1 request to SGLang or TokenSpeed fans out into n single-sample PD dispatches. Each sample gets its own bootstrap room and request id (<id>-<i>); on TokenSpeed, a pinned seed is also offset by the sample index. The dispatches fail fast together, and their responses merge back into one response with one choice per sample. Multimodal requests keep a single dispatch.
The HTTP PD router has no per-sample fan-out: a /v1/completions request with one prompt and n>1 sends every sample to the same rendezvous, and on SGLang the extra samples stall. Serve n>1 SGLang traffic through gRPC workers. vLLM needs no fan-out, because n>1 skips the KV handoff (see above).
Multimodal Requests
Over HTTP, both legs receive the request's media as sent. On the gRPC path:
- The decode leg is a copy of the request without pixel tensors, so pixels travel only to prefill. TokenSpeed decode keeps the per-item metadata it needs.
- vLLM decode keeps each image's identity and its M-RoPE grid tensors (
image_grid_thw,video_grid_thw, and the video timing tensor), so it computes the same positions as prefill. - With worker-side media processing, vLLM processes each image or video once, on the prefill leg. Prefill returns a media identity without pixels, and SMG passes it to decode. With
n>1there is no handoff, so decode processes the media itself. - vLLM decode workers started with
--language-model-onlyreceive only the prefill-expanded token ids, the KV handoff, and per-image content hashes. Requests such a pool cannot serve fail with a non-retryable 400: M-RoPE models (pd_decode_language_model_only_mrope), worker-side media references (pd_decode_language_model_only_media_refs), and multimodaln>1(pd_decode_language_model_only_n_samples).
See Multimodal for media processing modes and tensor transport.
Supported APIs
| API | HTTP PD | gRPC PD |
|---|---|---|
Chat Completions (/v1/chat/completions), Completions (/v1/completions), /generate |
✓ | ✓ |
Anthropic Messages (/v1/messages) |
✓ | ✓ |
Responses (/v1/responses) |
✓ proxied; stored-response features belong to the engine | ✓ |
Messages token counting (/v1/messages/count_tokens) |
✓ one prefill worker, no decode leg | ✓ answered by SMG, no leg involved |
Rerank (/v1/rerank) |
✓ | ✗ |
| Embeddings, classification | ✗ | ✗ |
Token counting generates nothing. Over HTTP, SMG sends it to a single prefill worker and adds no bootstrap fields. Over gRPC, SMG answers it from the model's tokenizer and contacts no leg at all. See the Messages API.
Configuration
Flags
| Flag | Default | Description |
|---|---|---|
--pd-disaggregation |
off | Enable PD mode |
--prefill <url> [bootstrap_port] |
— | Prefill worker. Repeat per worker. The optional second value is the worker's bootstrap port (SGLang, TokenSpeed, vLLM Mooncake) or none |
--decode <url> |
— | Decode worker. Repeat per worker |
--prefill-policy |
--policy |
Routing policy for the prefill leg |
--decode-policy |
--policy |
Routing policy for the decode leg |
--pd-pairing-mode |
lenient |
off, lenient, or strict: how strictly the legs must share a KV transfer protocol. See Pairing |
--pd-admission-wait-secs |
30 |
gRPC only: how long a dispatch waits for a free decode slot before it is shed |
--prefill-max-inflight-requests-per-worker |
-1 (off) |
Per-worker prefill admission cap, with the --prefill-queue-* flags. See Prefill Admission |
--dp-aware |
off | Register one worker per data-parallel rank. vLLM Mooncake needs it to mint engine ids for DP>1 prefill workers |
--model-path, --tokenizer-path |
— | gRPC only: a tokenizer SMG loads at startup, also used for workers that report no tokenizer or model path |
The startup worker lists may be empty: add legs at runtime with POST /workers and "worker_type": "prefill" or "decode" (see Worker Management). For every option, see the configuration reference.
Examples
smg launch \
  --pd-disaggregation \
  --prefill http://prefill-0:8000 8998 \
  --prefill http://prefill-1:8000 8998 \
  --decode http://decode-0:8000 \
  --decode http://decode-1:8000 \
  --prefill-policy cache_aware \
--decode-policy power_of_two# Workers run with --grpc-mode
smg launch \
--pd-disaggregation \
--prefill grpc://prefill-0:50051 8998 \
--decode grpc://decode-0:50052 \
--model-path meta-llama/Llama-3.1-8B-Instruct# NIXL: no bootstrap port
smg launch \
--pd-disaggregation \
--prefill grpc://prefill-0:50051 \
--decode grpc://decode-0:50052 \
--model-path meta-llama/Llama-3.1-8B-Instruct# Mooncake: pass each prefill worker's VLLM_MOONCAKE_BOOTSTRAP_PORT
smg launch
--pd-disaggregation
--prefill grpc://prefill-0:50051 8998
--prefill grpc://prefill-1:50051 8999
--decode grpc://decode-0:50052
--model-path meta-llama/Llama-3.1-8B-Instruct
# Start PD mode without startup workers...
smg launch --pd-disaggregation --host 0.0.0.0 --port 30000
# ...then register each leg with its KV connector
curl -X POST http://localhost:30000/workers
  -H "Content-Type: application/json"
  -d '{"url": "http://prefill-0:8000", "worker_type": "prefill", "kv_connector": "NixlConnector"}'
curl -X POST http://localhost:30000/workers
  -H "Content-Type: application/json"
  -d '{"url": "http://decode-0:8000", "worker_type": "decode", "kv_connector": "NixlConnector"}'
smg launch
  --pd-disaggregation
  --prefill grpc://prefill-0:50051 8998
  --decode grpc://decode-0:50052
  --model-path meta-llama/Llama-3.1-8B-Instruct
Worker launch commands for each engine are in Getting Started: PD Disaggregation.
Per-Phase Policies
The prefill and decode legs each run their own policy instance, so a stateful policy such as round_robin keeps a separate rotation per leg. The prefill policy chooses among prefill workers that have an available compatible decode worker, then the decode policy chooses among that prefill's compatible decode workers. A leg without its own policy uses --policy. Both legs take the same tuning flags as --policy, such as --cache-threshold or the --least-load-* flags.
| Policy | Prefill | Decode | Notes |
|---|---|---|---|
cache_aware |
✓ | ✓ | Prompt-prefix affinity; the prompt's KV cache is computed on prefill |
prefix_hash, consistent_hashing |
✓ | ✓ | Hash-based affinity |
power_of_two, least_load |
✓ | ✓ | Load-based. At startup, --prefill-policy power_of_two or --decode-policy power_of_two needs at least two workers on that leg (not checked with service discovery, --enable-igw or --dp-aware, under which each URL registers one worker per DP rank) |
round_robin, random |
✓ | ✓ | Even or random spread |
manual |
✓ | ✓ | Sticky keys are tracked per leg |
bucket |
✓ | ✗ | Rejected as a decode policy at startup — except in PD mode outside IGW with service discovery configured, where the decode leg runs without buckets and every pick warns and falls back to a random worker (see Bucket) |
smg launch \
  --pd-disaggregation \
  --prefill http://prefill-0:8000 8998 \
  --prefill http://prefill-1:8000 8998 \
  --decode http://decode-0:8000 \
  --decode http://decode-1:8000 \
  --prefill-policy cache_aware \
  --decode-policy least_load
Prefill/Decode Pairing
A prefill worker can hand its KV cache only to a decode worker that speaks the same KV transfer protocol. SMG gives each prefill and decode worker a pairing descriptor and pairs a prefill only with decode workers whose descriptor is compatible. Compatibility is worked out when workers join or leave, not on every request.
What Is Compared
| Component | Source |
|---|---|
| Runtime | The detected engine: sglang, vllm, or tokenspeed |
| Transport | vLLM: the worker's KV connector, reduced to nixl, mooncake, or moriio; a store variant of those families becomes its own <transport>-store (MooncakeStoreConnector compares as mooncake-store, never with a rendezvous worker), and any other connector name is compared as is, lower-cased. A moriio worker with a moriio_mode label becomes moriio-read or moriio-write. SGLang: the disaggregation_transfer_backend label. TokenSpeed: the same label, mooncake when absent |
| KV layout | The kv_cache_dtype, page_size (vLLM's block_size), attention_backend, and model_dtype labels, each compared on its own |
| Engine version | The version label. Compared only in strict mode, and only when both legs report one |
gRPC workers report these facts at registration. SGLang reports its transfer backend, kv_cache_dtype, page_size, attention_backend, and version. TokenSpeed reports the same except page_size. vLLM reports its connector, kv_cache_dtype, block_size, attention_backend, and model_dtype, but no version. HTTP workers report no transport or KV layout, only the runtime and engine version, so an HTTP vLLM worker's transport comes from its registered kv_connector.
GET /workers shows each prefill and decode worker's key in pd_pairing: the explicit protocol if one is set, otherwise runtime/transport/layout with ? for an unknown part, for example vllm/nixl/dtype=auto,page=16,attn=flash_attn,model=torch.bfloat16. The version is not part of the key.
Pairing Modes
--pd-pairing-mode |
A prefill and a decode do not pair when |
|---|---|
off |
Never. Every prefill may pair with every decode, although gRPC still keeps both legs on one runtime |
lenient (default) |
Both legs report a runtime, transport, or KV layout fact and the values differ. Unknown components and engine versions are ignored |
strict |
As lenient, and also when the runtime or transport is unknown on either leg, a KV layout fact is reported by only one leg, only one leg has an explicit protocol, or the legs report different engine versions |
lenient keeps a fleet that reports nothing pairing as before, and lets a rolling engine upgrade mix versions. Under strict, HTTP workers need an explicit protocol (or, for vLLM, a registered kv_connector), because they report no transport.
Explicit Pairing Protocol
Set a pairing protocol to declare compatibility yourself. Two legs that both carry one pair only when the values are equal, and nothing except the runtime is compared. When only one leg carries one, lenient falls back to the derived facts and strict refuses the pair. SMG reads it from these sources, highest precedence first:
- The
pairing_protocolfield of the worker spec, for example in the body ofPOST /workers. - A
pairing_protocolworker label, for example in thelabelsofPOST /workers. - The
SMG_PAIRING_PROTOCOLenvironment variable of the engine process. The vLLM, SGLang, and TokenSpeed gRPC servicers report it in their server info.
On Kubernetes, set SMG_PAIRING_PROTOCOL in the engine container; there is no pod annotation for it.
When no prefill shares a protocol with any decode, requests fail with 503 no_compatible_pd_pair. The message names the components that differ and each leg's keys, and SMG logs the same at warn level. A prefill worker with no compatible decode is skipped as long as other prefill workers can pair.
Admission and Errors
Decode Admission Window (gRPC)
Before a gRPC PD or EPD dispatch goes out, SMG claims one room for each backend request on the decode worker, within the running window that engine reports: SGLang's max_running_requests, or vLLM's and TokenSpeed's max_num_seqs (the engines' --max-running-requests and --max-num-seqs flags). A max_running_requests or max_num_seqs label set by hand on the worker is its only window, whatever the engine reports. When the window is full, the request waits up to --pd-admission-wait-secs (default 30) and is then shed with 503 worker_overload_protection_shed and a Retry-After header; a room that frees goes to the request that has waited longest. 0 sheds immediately. Keep the wait well under the engine's bootstrap deadline (120 seconds on TokenSpeed). Decode workers that report no window are not gated; the smg_pd_admission_window gauge shows each decode worker's window, 0 for an ungated one. smg_pd_admission_waits_total counts dispatches admitted after a wait, and smg_pd_admission_sheds_total counts the sheds. See Overload Protection.
When some of the decode workers a prefill can pair with have a free room and others are full, the decode pick keeps only the candidates with a room, so the policy does not queue a request behind a full worker while a sibling could take it. A consistent-hashing pick that names an explicit target is never narrowed and waits at its own worker's gate.
Prefill Admission
The prefill side has an opt-in gate of its own: --prefill-max-inflight-requests-per-worker (off by default; any value of 0 or less turns it off) caps the in-flight prefill requests SMG itself has started on each prefill worker, in PD and EPD mode on both transports. A request that finds every eligible prefill worker at its cap joins a first-come, first-served queue of up to --prefill-queue-size requests (default 100 with the gate on) for at most --prefill-queue-timeout-secs (default 60 with the gate on; on the gRPC path the wait also stays within --queue-timeout-secs). A full queue answers 429 pd_prefill_queue_full, and a request that waits out the timeout 429 pd_prefill_queue_timeout. The smg_pd_prefill_admission_inflight, smg_pd_prefill_admission_queued, smg_pd_prefill_admission_wait_seconds, and smg_pd_prefill_admission_rejections_total series track the gate; the flags are in the configuration reference.
Context Length (gRPC)
On the gRPC path, SMG counts the prompt tokens itself and rejects a prompt longer than the model's context window with 400 context_length_exceeded before dispatch. In PD mode the smaller window of the two legs applies. Workers that advertise no window are not checked, and the HTTP path leaves the check to the engine.
Error Codes
| Status | Code | Meaning |
|---|---|---|
| 503 | no_available_workers |
A leg has no available worker: all of its workers are unhealthy or circuit-open, or no worker is registered on it at all while the other leg has workers (the pair is incomplete). Sent with Retry-After. Same code as the regular HTTP and gRPC routers |
| 503 | no_compatible_pd_pair |
No prefill shares a KV transfer protocol with any decode |
| 503 | worker_overload_protection_shed |
The decode admission window stayed full, or overload protection vetoed a leg. Sent with Retry-After |
| 429 | pd_prefill_queue_full |
The prefill admission queue is full |
| 429 | pd_prefill_queue_timeout |
The request waited out --prefill-queue-timeout-secs without a prefill slot |
| 400 | context_length_exceeded |
gRPC: the prompt exceeds the smaller context window of the two legs |
| 400 | runtime_pd_not_supported |
gRPC: the selected runtime has no PD protocol |
| Engine status, or 502 | prefill_worker_failed_to_start, decode_worker_failed_to_start |
The leg never started, on either transport: the engine refused it and its status is kept, or the call to its worker failed below HTTP (502) |
| 504 | prefill_worker_silent, decode_worker_silent |
gRPC: the leg produced nothing within its liveness bound. Retryable, and the retry window closes on that worker alone — its partner stays selectable |
| Engine status, or 502 | prefill_stream_error, decode_stream_error |
The leg's stream ended with an error after it began, answered as a whole error response on either transport: over gRPC the failure's own status is kept, and over HTTP a leg body that could not be read to its end answers 502. A response already streaming to the client keeps its status and ends with a typed stream_error event instead |
| 500 | pd_rendezvous_failed |
gRPC: the decode engine failed the request without a reason of its own, and the bootstrap probe, rerun against the prefill leg's port, found it dead. The message says the prefill leg's bootstrap port did not accept a connection; the gateway log names the port, and the failure counts in smg_pd_rendezvous_failures_total{phase="request"} |
| 502 | prefill_count_tokens_failed |
HTTP: the /v1/messages/count_tokens call to its one prefill worker failed below HTTP, or its response body could not be read |
| 503 | moriio_pair_misconfigured |
vLLM MoRI-IO over HTTP: the selected pair is not configured for MoRI-IO. The reason is in the gateway log |
| 400 | moriio_fanout_unsupported |
MoRI-IO: n>1, a batched prompt or prompt embeddings, or beam search |
| 400 | moriio_request_id_reserved |
MoRI-IO: a request id carries the connector's peer-address markers |
| 501 | moriio_route_unsupported |
MoRI-IO: the route is not /v1/chat/completions or /v1/completions |
| 502 | moriio_handoff_invalid |
MoRI-IO: the prefill returned no usable handoff — missing, foreign, or with fields the decode engine cannot parse. Sequential dispatch sends no decode leg; concurrent dispatch drops the one already sent |
| 501 | moriio_grpc_pd_unsupported |
gRPC: MoRI-IO PD is supported only by the HTTP PD router |
The no_available_workers message names the missing leg of an incomplete pair (prefill, decode, or, in EPD mode, encode) on both transports, instead of calling the registered leg unhealthy; retry once that leg is back. When a leg's workers are all unhealthy or circuit-open, the message names the leg over HTTP but not over gRPC.
A model whose only workers are the legs of an incomplete pair is answered by the pair's own router — the gRPC PD or EPD router for gRPC legs, the HTTP PD router for HTTP legs — with that retryable 503. Only a model with no worker on any leg answers 404 model_not_found, as for any unknown model.
/readiness reports ready only when at least one prefill worker and one decode worker are healthy (and an encode worker in EPD mode). The readiness gates (--prefill-min-ready-workers, --prefill-expected-workers, --prefill-min-ready-percent and their --decode-* counterparts) raise that bar per role to an absolute minimum, a percentage of an expected fleet size, or both.
EPD (Encode-Prefill-Decode)
EPD adds a third worker role for multimodal models. Encode workers run the vision tower, and prefill and decode workers run the language model; prefill and decode proceed as in PD once the encode output reaches the prefill worker. EPD requires gRPC workers running TokenSpeed or vLLM (TokenSpeed legs may also be direct ZMQ workers); SMG refuses to start an EPD router for HTTP workers. The encode handoff is the runtime's:
- TokenSpeed: a rendezvous per media item. SMG preprocesses the media, assigns each item its own encode worker and bootstrap room, and dispatches the encode jobs beside the pair; the prefill worker pulls the embeddings from each encode worker's Mooncake bootstrap server. Encode workers never take raw media references, so with
--mm-processing workeran EPD request that carries media fails with 400multimodal_not_supported. - vLLM: a push over the engines' EC connector. The engines run vLLM's encoder-cache (EC) transfer connectors, and the gRPC servicer reports each worker's EC connector and role. SMG pairs an encode worker that produces with a prefill worker that consumes on the same EC connector, and answers 503
ec_incompatible_pairwhen none pair. The encode worker answers first, with the prompt's expanded identity and one transfer handle per media item; the prefill leg consumes a pixel-less prompt that names them, and SMG releases pushed transfers the prefill side never takes. The encode worker processes the request's media itself, so worker-side media references are supported when the encode workers advertise worker-side processing. One encode worker takes the whole prompt; only an image-only request whose images reach the encode worker as media references (worker-side processing) can fan its images out over several encode workers.
| Flag | Default | Description |
|---|---|---|
--epd-disaggregation |
off | Enable EPD mode (instead of --pd-disaggregation) |
--encode <url> [bootstrap_port] |
— | Encode worker. Repeat per worker. The port is a TokenSpeed encode worker's Mooncake bootstrap port, where prefill reads the embeddings (8998 when omitted) |
--prefill <url> [bootstrap_port], --decode <url> |
— | Prefill and decode workers, as in PD mode |
--encode-policy |
consistent_hashing |
random, round_robin, or consistent_hashing. The default keys each assignment by content hash — per media item on TokenSpeed, per prompt on vLLM (per media item for an image-only request whose images reach the encode worker as references) — so a repeated input goes to the same encode worker |
--encode-selector |
— | Kubernetes label selector for encode pods. EPD discovery needs all three role selectors |
smg launch \
  --epd-disaggregation \
  --encode grpc://encode-0:50060 8995 \
  --prefill grpc://prefill-0:50061 8998 \
  --decode grpc://decode-0:50062 \
--model-path "$MODEL"- Text-only requests skip the encode leg.
- EPD mode does not serve
/v1/responses(501). - EPD keeps all three legs on one runtime. The prefill and decode legs pair under
--pd-pairing-modeas in PD mode, and a vLLM encode worker pairs only with a prefill worker on its EC connector.
Worker launch commands are in Getting Started: PD Disaggregation.
Kubernetes Service Discovery
smg launch \
  --service-discovery \
  --pd-disaggregation \
  --prefill-selector app=sglang role=prefill \
  --decode-selector app=sglang role=decode \
  --service-discovery-namespace inference \
  --service-discovery-port 8000 \
  --prefill-policy cache_aware \
  --decode-policy least_load
SMG assigns each pod the role of the selector it matches. Prefill (and encode) pods advertise their bootstrap port with the sglang.ai/bootstrap-port annotation. vLLM pods declare their KV connector and engine id with the smg.ai/kv-connector and smg.ai/kv-engine-id annotations. Service discovery turns on IGW mode automatically; PD and EPD mode and the per-role policies are kept. See PD Disaggregation Discovery for the annotation formats and a pod example.
Sizing Guidelines
Prefill Workers
Prefill is compute-bound. Its cost grows with prompt length, and every request's time to first token includes the prefill and the KV transfer. Add prefill capacity when time to first token (smg_pd_ttft_seconds) climbs while the decode workers have headroom.
Decode Workers
Decode is memory-bandwidth-bound. Its throughput depends on how many sequences fit in the decode batch, which the KV cache capacity limits. Add decode capacity when dispatches wait for or are shed at the decode admission window (smg_pd_admission_waits_total, smg_pd_admission_sheds_total), or when time per output token grows.
Prefill:Decode Ratio
Long prompts with short outputs need relatively more prefill capacity. Short prompts with long outputs need relatively more decode capacity. Start from your workload's prompt and output lengths, then scale each pool independently based on the signals above.
Monitoring
PD Metrics
| Metric | Type | Labels | Recorded |
|---|---|---|---|
smg_pd_ttft_seconds |
Histogram | backend_type, model, runtime |
Prefill dispatch to the first decode output. HTTP PD (the decode response head), and streamed requests on gRPC PD |
smg_pd_decode_ttft_seconds |
Histogram | backend_type, model, runtime |
Decode dispatch to the first decode token; under parallel dispatch, the whole TTFT. Recorded with smg_pd_ttft_seconds on gRPC PD |
smg_pd_prefill_duration_seconds |
Histogram | backend_type, model, runtime |
Prefill-leg duration. HTTP PD and gRPC vLLM |
smg_pd_kv_transfer_duration_seconds |
Histogram | backend_type, model, runtime |
Prefill completion to decode dispatch. gRPC vLLM |
smg_pd_kv_connector_mode_total |
Counter | mode (nixl, mooncake, moriio, store, passthrough) |
vLLM dispatches, sequential and MoRI-IO concurrent |
smg_pd_kv_transfer_failures_total |
Counter | — | A NIXL prefill returned no kv_transfer_params, so decode recomputed the prompt; or a MoRI-IO pair or handoff check failed, so the request failed |
smg_pd_bootstrap_failures_total |
Counter | — | HTTP bootstrap injection failed |
smg_pd_rendezvous_failures_total |
Counter | leg (the worker type of the leg whose rendezvous failed), phase |
A rendezvous failed: a bootstrap port did not accept the registration probe (probe); or, on the gRPC path, the same probe — rerun when a decode engine failed a request without a reason — found the prefill leg's port dead (request, counted on the prefill leg), or an engine reported that the legs never met (bootstrap) or that the KV handoff after they met failed (transfer) |
smg_pd_admission_waits_total |
Counter | — | gRPC dispatches admitted after waiting for a decode slot |
smg_pd_admission_sheds_total |
Counter | — | gRPC dispatches shed at the decode admission window |
smg_pd_admission_window |
Gauge | worker |
The running window the decode admission gate bounds a worker by; 0 when the engine reports none and the gate is off for it |
smg_pd_prefill_admission_inflight, smg_pd_prefill_admission_queued, smg_pd_prefill_admission_wait_seconds, smg_pd_prefill_admission_rejections_total |
Gauge / Gauge / Summary / Counter | worker (inflight), reason (rejections) |
The prefill admission gate: admitted in-flight requests per worker, queued waiters, queue wait, and refusals by reason |
Related series:
smg_worker_selection_totalcounts picks per leg (worker_typeisprefill,decode, orencode), withconnection_mode,model, andpolicylabels.smg_worker_requests_activeshows in-flight requests per worker (workerlabel).smg_router_ttft_secondswithbackend_type="pd"(gRPC, streamed answers only) starts at the same prefill-dispatch anchor assmg_pd_ttft_seconds, so a sample carries both legs' delays.smg_engine_pd_kv_transfer_latency_ms,smg_engine_pd_kv_transfer_speed_gb_s,smg_engine_pd_prefill_queue_reqs, andsmg_engine_pd_decode_queue_reqs(labelsworker,role,dp_rank) are published when an engine's load report includes disaggregation statistics, as the SGLang gRPC servicer's does.
See the Metrics Reference for every metric.
PromQL Queries
Time to First Token
# p95 PD time to first token by model
histogram_quantile(0.95,
  sum by (le, model) (rate(smg_pd_ttft_seconds_bucket[5m])))
vLLM Dispatches Without a KV Connector
# Share of vLLM PD dispatches running passthrough
sum(rate(smg_pd_kv_connector_mode_total{mode="passthrough"}[5m]))
  / sum(rate(smg_pd_kv_connector_mode_total[5m]))
Decode Admission Sheds
# gRPC PD dispatches shed at the decode window
rate(smg_pd_admission_sheds_total[5m])
Active Requests by Worker
# In-flight requests per worker
smg_worker_requests_activeTroubleshooting
| Symptom | Cause | Solution |
|---|---|---|
503 no_available_workers |
A leg has no healthy worker with a closed circuit (over HTTP, the message names it) | Check /workers; restore or add workers on that leg |
503 no_available_workers naming a missing leg |
No worker is registered on that leg while the other leg has workers: the pair is incomplete (a leg restarting or not yet discovered) | Register or bring back the missing leg; clients can retry after Retry-After |
503 no_compatible_pd_pair |
No prefill shares a KV transfer protocol with any decode | Compare the pd_pairing keys in /workers; align the engines or set a shared pairing protocol |
503 worker_overload_protection_shed |
The decode admission window stayed full, or a leg is overloaded | Add decode workers or raise the engine's running window |
400 context_length_exceeded (gRPC) |
The prompt exceeds the smaller context window of the two legs | Shorten the prompt or give both legs the same context length |
| vLLM PD answers correctly but decode recomputes prompts | The prefill worker has no KV connector (mode="passthrough"), or a NIXL prefill returned no params (smg_pd_kv_transfer_failures_total) |
Register HTTP workers with kv_connector; check --kv-transfer-config; upgrade the servicer |
SGLang n>1 completions stall over HTTP |
The HTTP PD router has no per-sample fan-out | Serve n>1 traffic through gRPC workers |
| High TTFT with idle decode workers | The prefill pool is saturated | Add prefill workers |
| Slow KV transfer and high TTFT on a cross-host NIXL pair without RDMA | NIXL moves the KV over UCX's TCP transport, and workers outside the SMG engine images fragment it at UCX's 8 KiB default segment | Raise the UCX TCP segment size to 1 MiB; see Cross-Host KV Transfer over TCP |
Cross-Host KV Transfer over TCP (UCX Segment Size)
A NIXL prefill/decode pair on different hosts without an RDMA device moves the KV cache over UCX's TCP transport, and the data travels in fragments of the transport's send segment, each staged through host memory on both ends. At UCX's 8 KiB default the fragment count, not the link, sets the rate. The SMG engine images (see Getting Started) therefore ship /etc/ucx/ucx.conf with:
UCX_TCP_TX_SEG_SIZE=1m
UCX_TCP_RX_SEG_SIZE=1m
The receive segment (64 KiB by UCX's default) must be at least the send segment; UCX refuses the combination otherwise.
On the one measured pair (a hybrid-attention checkpoint whose linear-attention state moves whole, TP 2, about 100 MB moved per rank per request), 1 MiB segments raised the pull from about 2.2 Gbit/s to about 11 Gbit/s per rank stream, the rate of a plain socket between the same pods. At 4 req/s offered, the same change took the pair from a 2.7 req/s ceiling with a median first token of 33 s to 3.93 req/s with 0.35 s. Treat those figures as one measurement, not a guarantee.
Segments of 256 KiB already give most of the gain, and segments above 1 MiB buy nothing on a single socket. The cost is host memory, not GPU memory: UCX stages TCP transfers through per-process buffer pools of the segment size.
Scope. The two keys configure only UCX's TCP transport: a pair over RDMA, or on one host over CUDA IPC, is unaffected. The pip NIXL wheels compile /etc/ucx in as their configuration directory, so the UCX that NIXL bundles — the one behind vLLM's NixlConnector and SGLang's NIXL transfer backend — reads the file in every process that creates a UCX context, the engine's tensor-parallel workers included. Mooncake and MoRI-IO do not use UCX. TensorRT-LLM's release images build their own UCX under /usr/local/ucx, and that UCX never opens the file; TensorRT-LLM cannot serve as a PD leg in any case (see Supported Engines). Workers launched outside the SMG engine images do not have the file and run UCX's defaults.
Overriding and verifying. The image sets the segment size in a file rather than an environment variable because UCX reads its settings in each worker process, and worker processes do not always inherit the container's environment. UCX layers its configuration, each source overriding the one before: the image's /etc/ucx/ucx.conf (lowest), a ucx.conf in a directory named by UCX_CONFIG_DIR, a ucx.conf in the process's working directory, and UCX_* variables in the worker processes' environment (highest). To check what is in force, set UCX_PROTO_INFO=y in any of those layers: UCX prints its protocol selection once per peer at the first transfer.
Debug Logging
RUST_LOG=smg=info,smg::routers=debug smg launch --pd-disaggregation ...At debug level SMG logs each selected pair and, on the gRPC vLLM path, whether it relayed the prefill's kv_transfer_params.
Verify Configuration
# Role, health, and pairing key of every worker
curl -s http://localhost:30000/workers | jq '.workers[] | {url, worker_type, is_healthy, pd_pairing}'

# Ready only when both legs have a healthy worker
curl -i http://localhost:30000/readiness