gRPC Pipeline
When workers connect over gRPC, SMG runs the whole OpenAI-compatible serving pipeline itself. It renders the chat template, tokenizes, builds constrained-decoding grammars, detokenizes, extracts reasoning, parses tool calls, and runs MCP tool loops. Workers only run inference on token IDs. Workers on the ZMQ direct backend go through the same pipeline.
Overview
Chat Templates
Jinja2 chat templates for most models, plus native prompt encoders for DeepSeek-V3.2, V4 and V4.1 and Kimi-K3 checkpoints.
Tokenization Caching
Optional L0 (exact match) and L1 (prefix) caches skip re-encoding prompt content the gateway has already seen.
Reasoning Extraction
21 registered reasoning parsers move chain-of-thought into reasoning_content for DeepSeek, Qwen, Kimi, GLM, MiniMax, Nemotron, and more.
Tool Call Parsing
26 registered tool-call parsers turn each model family's native call format into OpenAI tool_calls. MCP tools run in the gateway.
Constrained Decoding
XGrammar structural tags and JSON schemas make forced tool calls and structured outputs match the declared schemas.
Pipeline Architecture
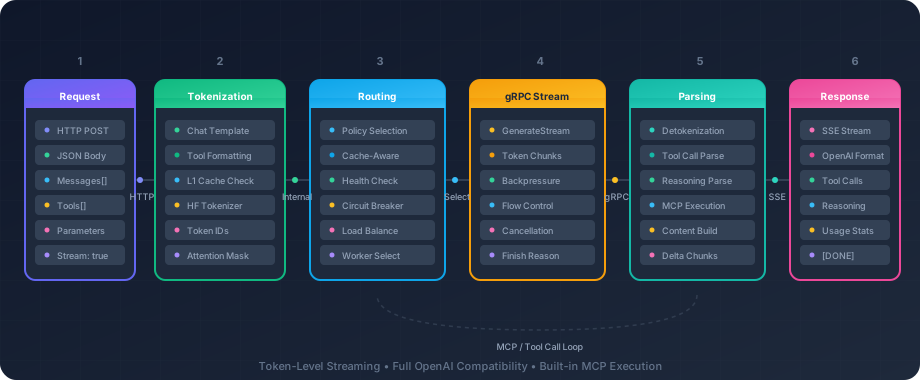
gRPC Mode
Gateway = Full Server
SMG handles tokenization, chat templates, tool parsing, MCP loops, and detokenization. Workers run raw inference.
HTTP Mode
Gateway = Smart Proxy
SMG handles routing, load balancing, and failover. Workers run full OpenAI-compatible servers.
Responsibility Comparison
| Capability | gRPC Mode (Gateway) | HTTP Mode (Worker) |
|---|---|---|
| Chat template | Gateway | Worker |
| Tokenization | Gateway (cached) | Worker |
| Constrained decoding (XGrammar) | Gateway builds, worker enforces | Worker |
| Cache-aware routing key | Token IDs from the gateway's tokenizer | Request text, or token IDs when the request is pre-tokenized |
| Reasoning extraction | Gateway | Worker |
| Tool call parsing | Gateway | Worker |
| MCP execution (Responses API) | Gateway | Not handled by the gateway |
The same pipeline serves Chat Completions, the Messages API and the Responses API. gpt-oss models use a separate Harmony pipeline. SMG selects it when a worker's model card lists the GptOssForCausalLM architecture or the gpt_oss model type, or when the model name contains gpt-oss. Harmony has its own encoding and output channels, so the chat templates and parser registries on this page don't apply to it.
Parser Selection
Every request resolves one tool-call parser and one reasoning parser for its model. SMG checks these sources in order:
- Per-model override: the
tool_parser/reasoning_parserof the model's card on its workers. - Gateway flag:
--tool-call-parser/--reasoning-parser, which applies to every model. - Automatic detection from the model name.
Under the default --parser symphony, the gateway reads Chat Completions, Messages API and Responses API responses with Symphony tables; the same names then pick the table per model, with Symphony's checkpoint registry between the per-model overrides and the flags, as that section describes. --parser legacy keeps these per-model parsers as the readers.
The gateway checks the flag values when it starts, against the configured --parser. Under the default --parser symphony, an unknown name stops startup with unknown tool-call parser '<name>' or unknown reasoning parser '<name>', ending neither a legacy parser nor a Symphony table (Table Names has the full rules). Under --parser legacy, a --tool-call-parser or --reasoning-parser value naming none of that flag's legacy parsers stops startup with unknown tool-call parser '<name>' or unknown reasoning parser '<name>'; when the rejected name is one --parser symphony reads with — a table's own name, muse, llama4_pythonic or hf — the error says so, ending which --parser symphony reads with. The pip smg launch rejects a name outside the combined legacy and Symphony lists earlier, as an invalid choice. Names must match exactly (deepseek_r1, not deepseek-r1).
Per-Model Overrides
The process-wide flags suit a gateway that serves one model family. To serve several families from one gateway, give each model its own parsers when you register its workers. Either form works:
- Labels:
tool_parserandreasoning_parserkeys in the worker'slabels. - Model card:
tool_parserandreasoning_parserfields on an explicit entry in the worker'smodelslist. An explicit card keeps its own values; labels only fill the fields it leaves empty.
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer ${ADMIN_TOKEN}" \
  -d '{
    "url": "grpc://coder-worker:50051",
    "models": [
      {"id": "my-coder", "tool_parser": "qwen_xml", "reasoning_parser": "qwen3"}
    ]
  }'
Registration fails if an override names an unknown parser (worker <url> declares a parser override for model '<id>' the gateway cannot read with: unknown tool-call parser '<name>'). Workers of the same model should agree. If they don't, for example during a rolling upgrade, SMG logs a warning at registration and uses the lexicographically smallest name. Kubernetes service discovery sets no parser labels, so discovered workers rely on the flags. See the Admin API for the worker endpoints.
Under the default --parser symphony, an override may also name a Symphony table or hf, giving one model its own table without touching the rest; naming a legacy tool-call parser no table answers to sends just that model back to the legacy parsers.
Automatic Detection
Without an override or a flag, SMG matches the request's model field against name patterns. It uses the canonical name, after model aliases resolve. Matching is case-insensitive and finds the pattern anywhere in the name, so Qwen/Qwen3.8-2.4T-A95B matches qwen3.8. The two registries break ties differently:
- Tool-call parsers: the longest matching pattern wins, so
deepseek-v4.1beatsdeepseek-v4. If nothing matches, SMG doesn't parse tool calls and returns the text ascontent. - Reasoning parsers: the first match in the reference table's order wins, which is why the specific DeepSeek, Qwen-thinking, Kimi and MiniMax patterns come before the broad
qwen,kimiandminimaxones. If nothing matches, reasoning stays incontent.
The reference tables under Reasoning Parsers and Tool Call Parsers list every pattern.
Chat Templates and Native Renderers
In gRPC mode the gateway builds the prompt text itself. Most models use a Jinja2 chat template. An explicit template wins: a model card's chat_template path first, then --chat-template. Otherwise SMG searches the model directory in this order: a chat_template.jinja file, then the chat_template field of tokenizer_config.json, then the legacy chat_template.json file (read only when tokenizer_config.json carries no template), and finally any other .jinja file.
The chat_template field of tokenizer_config.json may also hold a list of named templates, read the way HuggingFace Transformers reads it: the default entry renders a plain request, and the tool_use entry renders a request that declares tools. A template file replaces the config's templates, named ones included.
A checkpoint may also ship a processor chat_template.json beside the tokenizer's template. Requests without tools then render through the processor's template, and requests with tools keep the tokenizer's — provided the processor file compiles, differs from the tokenizer's default template, and agrees with it on how a request's thinking is prepared and read, and on how a history tool call's arguments are written. A processor file that disagrees or does not compile is left unused with a logged warning, and every request renders through the tokenizer's templates. A template given by a model card or --chat-template stands alone: the processor file is ignored, unless the given path is the model directory's own chat_template.jinja, which counts as the checkpoint's template.
Templates render with minijinja 2.24, so two Python Jinja2 behaviors work: conditional expressions inside keyword arguments (namespace(name=x if x else '')) compile, and booleans and none render as True, False and None.
Native Renderers
Some checkpoints ship a Python prompt encoder instead of a Jinja template. For these, SMG uses a native Rust port of that encoder, tested against the reference output. The tokenizer picks the renderer from the config.json next to the tokenizer files. The DeepSeek-V3.2, DeepSeek-V4.1 and Kimi-K3 renderers replace the Jinja template entirely, so --chat-template has no effect on those checkpoints. The DeepSeek-V4 renderer stands in only while the checkpoint has no chat template: when the checkpoint ships one or --chat-template names one, a V4 checkpoint renders through that template.
| Renderer | Selected when config.json has |
Thinking key (renderer default) | Native reasoning_effort values |
Notes |
|---|---|---|---|---|
| DeepSeek-V3.2 | architecture DeepseekV32ForCausalLM |
thinking (default off) |
None | Tools are attached to the leading system or developer message |
| DeepSeek-V4 | architecture DeepseekV4ForCausalLM |
thinking or its enable_thinking alias (default on) |
high, max (the 0731 refresh also low) |
Thinking stays on for every reasoning_effort except "none" |
| DeepSeek-V4.1 | architecture DeepseekV41ForCausalLM or model_type: deepseek_v41 |
thinking or its enable_thinking alias (default on) |
low, medium, high, xhigh, max, or an integer budget from 1 to 100 |
Continues a trailing assistant message natively with continue_final_message; reads tool-call arguments as written |
| Kimi-K3 | architecture KimiK3ForConditionalGeneration or model_type: kimi_k3 |
thinking or its enable_thinking alias (default on) |
low, high, max (default max; rendered only while thinking is on) |
Encodes the prompt piece by piece, so control-token text inside a message stays text; reads tool-call arguments as written |
| Kimi-K2.5 | architecture KimiK25ForConditionalGeneration or model_type: kimi_k25 |
From the Jinja template | None | Keeps the Jinja template, but renders tool declarations as TypeScript with a port of the checkpoint's tool_declaration_ts.py |
DeepSeek-V4 effort-prompt revisions are identified from the checkpoint's own encoding/encoding_dsv4.py. Under the refreshed (0731) encoder's table — also the fallback without the file (a tokenizer directory streamed from a worker carries no encoding/) — while thinking is on, low writes no effort prefix, high writes the "Absolute maximum" prompt, and max a stronger "Beyond maximum" one; a thinking request that sets no reasoning_effort renders high's prompt. Under the first published encoder, which DeepSeek-V4-Flash and -Pro ship, only max writes a prefix — the "Absolute maximum" prompt.
DeepSeek-V4.1 revisions are identified from the checkpoint's own encoding/encoding.py. Under the refreshed encoder's table — also the fallback without the file (a tokenizer directory streamed from a worker carries no encoding/) — low, medium, high and max render budgets 50, 62, 75 and 100, and xhigh renders high's budget. Under the first published encoder, low, high, xhigh and max render 25, 50, 75 and 100, and medium renders high's budget.
A request goes through SMG's DeepSeek request profile when a /-separated part of its model name is deepseek-v4-flash, deepseek-v4-pro, deepseek-v4.1-flash, deepseek-v4.1-flash-1017 or deepseek-flash (in any case), as in deepseek-ai/DeepSeek-V4-Flash. The profile resolves the thinking toggle once — on unless the request turns it off — and writes the answer to chat_template_kwargs.thinking when that key is unset (see Defaults and Rewrites).
Kimi-K3 appends a channel-opener stub after the assistant header — the think channel while thinking is on, the response channel otherwise. The engine receives the stub, but the prompt_tokens that clients see leave it out, matching Moonshot's billing.
Thinking and Reasoning Effort
Reasoning controls reach the template as template variables. The request fields are documented in the OpenAI-Compatible API.
- Template kwargs:
reasoning_effort(orthinking.effort, which takes precedence),tool_choiceandresponse_formatare passed to the template as kwargs of the same name. An entry inchat_template_kwargsoverridestool_choiceandresponse_format, but not the effort: areasoning_effortentry applies only when the request sets no effort of its own. - Thinking on or off:
thinking.type(enabledordisabled) sets the preference (for how it ranks against a conflictingreasoning_effortorchat_template_kwargsentry, see Thinking and Reasoning Effort). Without it, areasoning_effortof"none"or"minimal"means off, with three exceptions: the DeepSeek-V4 renderer keeps thinking on for every value but"none"; on MiniMax models no effort value turns thinking off (MiniMax reads"none"as the model's default thinking depth and"minimal"aslow); and a Hunyuan-4 (Hy4) template takes the toggle fromreasoning_effort's own words —"no_think"turns thinking off, and any other value leaves it on. SMG writes the preference under the key the template actually reads:enable_thinking(Qwen3, GLM, Nemotron),thinking(DeepSeek, Kimi),thinking_modeset to"enabled"or"disabled"(MiniMax-M3), orreasoning_effortset to"high"or"no_think"(Hy4). A value you pass for that key inchat_template_kwargswins. - Native effort names: the DeepSeek-V4, V4.1 and Kimi-K3 renderers turn the values in the table above into their own effort prompt text.
- Parser arming: the reasoning parser follows the same decision. When thinking is on, it starts in reasoning mode, so the prompt and the parser agree.
Reasoning Parsers
Reasoning parsers separate chain-of-thought from the final answer. Models that emit thinking tokens before their response need one.
Configuration
| Option | --reasoning-parser |
|---|---|
| Default | Per-model override, otherwise auto-detected from the model name |
Supported Parsers
| Model family | Parser |
|---|---|
| DeepSeek-R1 | deepseek_r1 |
| DeepSeek-V3.1 | deepseek_v31 |
| DeepSeek-V4 | deepseek_v4 |
| DeepSeek-V4.1 | deepseek_v41 |
| Qwen3 and later hybrid-thinking Qwen models | qwen3 |
Qwen3 -Thinking checkpoints |
qwen3_thinking |
| GLM-4.5, GLM-4.7, GLM-5.x | glm45 |
| Gemma-4 | gemma4 |
| Hunyuan-4 (Hy4) | hy_v4 |
| Kimi-K2 (Instruct) | kimi |
| Kimi-K2-Thinking | kimi_thinking |
| Kimi-K2.5 | kimi_k25 |
| Kimi-K3 | kimi_k3 |
| MiniMax-M2 | minimax |
| MiniMax-M3 | minimax_m3 |
| Nemotron Nano, Nemotron Super, Nemotron-3 family | nano_v3 |
| Command-R, Command-A | cohere_cmd |
| Step-3 | step3 |
| Inkling | inkling |
Complete Parser Reference
All 21 registered reasoning parsers, in auto-detection order (the first match wins):
| Parser | Auto-detected when the model name contains | Markers | Starts in reasoning |
|---|---|---|---|
gemma4 |
gemma-4, gemma4 |
Thought channel <|channel>thought … <channel|>; tool-call frames stay opaque to reasoning |
No |
hy_v4 |
hy4, hy_v4 |
<think> / </think>, each tag carrying the checkpoint's optional :suffix |
No |
deepseek_r1 |
deepseek-r1 |
<think> / </think> |
Yes |
deepseek_v41 |
deepseek-v4.1, deepseek_v41, deepseek-v41 |
<think> / </think>; a <|DSML| calls> tool block also ends reasoning |
No |
deepseek_v4 |
deepseek-v4, deepseek_v4 |
<think> / </think> |
No |
deepseek_v31 |
deepseek-v3.1, deepseek-v3-1 |
<think> / </think> |
No |
qwen3_thinking |
qwen3-thinking, qwen-thinking |
<think> / </think> |
Yes |
qwen3 |
qwen3, qwen |
<think> / </think> |
No |
glm45 |
glm45, glm47, glm-5 |
<think> / </think> |
No |
kimi_thinking |
kimi-k2-thinking |
<think> / </think> |
Yes |
kimi_k25 |
kimi-k2.5 |
<think> / </think> |
No |
kimi_k3 |
kimi-k3, kimi_k3 |
XTML think channel (<|open|>think<|sep|> ... <|close|>think<|sep|>) |
No |
kimi |
kimi |
◁think▷ / ◁/think▷ |
No |
step3 |
step3 |
<think> / </think> |
Yes |
minimax_m3 |
minimax-m3, mm-m3 |
<mm:think> / </mm:think>; stray </mm:think> markers before the answer are dropped |
No |
minimax |
minimax, minimax-m2, mm-m2 |
<think> / </think> |
Yes |
cohere_cmd |
command-r, command-a, c4ai-command, cohere |
<|START_THINKING|> / <|END_THINKING|> |
No |
nano_v3 |
nemotron-nano, nemotron-super, nano-v3, nemotron-3 |
<think> / </think> |
No |
inkling |
inkling |
TML typed blocks such as <|content_thinking|>; decoded with special tokens kept |
No |
base |
Not auto-detected | <think> / </think> |
No |
passthrough |
Not auto-detected | None; all text stays in content |
No |
"Starts in reasoning" is the parser's own default. The gateway also starts a parser in reasoning mode when a request has thinking on for a template or renderer with a thinking toggle, such as Qwen3, GLM, Nemotron, DeepSeek-V4 and V4.1, and Kimi-K3. The model's first tokens then count as reasoning.
Output Format
Reasoning separation is on by default (separate_reasoning defaults to true). The extracted text is returned in reasoning_content:
{
  "choices": [{
    "message": {
      "role": "assistant",
      "content": "The answer is 42.",
      "reasoning_content": "Let me think step by step..."
    }
  }]
}
Set "separate_reasoning": false in a request to leave the reasoning text in content. When streaming, a parser holds back text that might be the start of a marker, such as a trailing </thi. At the end of the stream it releases that text to the correct field instead of dropping it.
Tool Call Parsers
Tool call parsers turn each model's native tool-call syntax into OpenAI tool_calls.
Configuration
| Option | --tool-call-parser |
|---|---|
| Default | Per-model override, otherwise auto-detected from the model name |
Supported Parsers
| Model family | Parser |
|---|---|
| GPT, Claude, Gemini, Gemma, and other Llama and GLM models that emit plain JSON | json |
| Llama 3.2 | llama |
| Llama 4 | pythonic |
| Mistral, Mixtral | mistral |
| Qwen2.5, Qwen3 | qwen |
| Qwen3-Coder, Qwen3.5, Qwen3.6, Qwen3.8 | qwen_xml |
| Nemotron-3 family (Nano, Super, Ultra, 3.5) | qwen_xml (alias nemotron) |
| DeepSeek-V3 | deepseek |
| DeepSeek-V3.1, DeepSeek-V3.2-Exp | deepseek31 |
| DeepSeek-V3.2 | deepseek32 |
| DeepSeek-V4 | deepseek_v4 |
| DeepSeek-V4.1 | deepseek_v41 |
| GLM-4.5, GLM-4.6 | glm45_moe |
| GLM-4.7, GLM-5.x | glm47_moe |
| Gemma-4 | gemma4 |
| Hunyuan-4 (Hy4) | hy_v4 |
| Kimi-K2 | kimik2 |
| Kimi-K3 | kimi_k3 |
| MiniMax-M2 | minimax_m2 |
| MiniMax-M3 | minimax_m3 |
| Command-R, Command-A | cohere |
| Step-3 | step3 |
| Sarashina | sarashina |
| Inkling | inkling |
Complete Parser Reference
All 26 registered tool-call parsers. For auto-detection, the longest matching pattern wins. The last column shows the constraint sent for a forced tool_choice when the parser is set by --tool-call-parser or an override (see Constrained Decoding).
| Parser | Auto-detected when the model name contains | Format | Forced-call constraint |
|---|---|---|---|
passthrough |
Not auto-detected | No parsing; text is returned unchanged | JSON schema |
json |
gpt-4, gpt-3.5, claude-, gemini-, gemma-, palm-, llama-, meta-llama-, glm- |
{"name": ..., "arguments": {...}}, or an array of these (parameters is also accepted) |
JSON schema |
gemma4 |
gemma-4, gemma4 |
<|tool_call>call:NAME{KEY:<|"|>VALUE<|"|>}<tool_call|> |
None: no constraint is sent; the forced call is parsed from the model's native output |
mistral |
mistral-, mixtral- |
[TOOL_CALLS] [{"name": ..., "arguments": {...}}] |
Structural tag |
qwen |
qwen |
<tool_call>{"name": ..., "arguments": {...}}</tool_call> |
JSON schema |
qwen_xml |
qwen3.5, qwen3.6, qwen3.8, qwen3-coder, nemotron-3 |
<tool_call><function=NAME><parameter=KEY>VALUE</parameter></function></tool_call> |
JSON schema |
qwen_coder |
Not auto-detected (alias of qwen_xml) |
Same as qwen_xml |
JSON schema |
nemotron |
Not auto-detected (alias of qwen_xml) |
Same as qwen_xml |
JSON schema |
pythonic |
llama-4, meta-llama-4, deepseek- |
[get_weather(city="SF"), ...] with Python literals |
JSON schema |
llama |
llama-3.2, meta-llama-3.2 |
<|python_tag|>{"name": ..., "parameters": {...}} (the tag is optional) |
JSON schema |
deepseek |
deepseek-v3 |
<|tool▁call▁begin|>function<|tool▁sep|>NAME followed by a fenced JSON block |
JSON schema |
deepseek31 |
deepseek-v3.1, deepseek-v3.2-exp |
<|tool▁call▁begin|>NAME<|tool▁sep|>{json}<|tool▁call▁end|> |
JSON schema |
deepseek32 |
deepseek-v3.2 |
DSML: <|DSML|invoke name="..."> and <|DSML|parameter name="..." string="true|false"> inside a <|DSML|function_calls> block |
JSON schema |
deepseek_v4 |
deepseek-v4 |
DSML inside a <|DSML|tool_calls> block |
JSON schema |
deepseek_v41 |
deepseek-v4.1, deepseek-v41, deepseek_v41 |
Spaced DSML: <|DSML| calls>, <|DSML| invoke ...>, <|DSML| parameter ...> |
Structural tag |
glm45_moe |
glm-4.5, glm-4.6 |
<tool_call>NAME, then <arg_key>K</arg_key> / <arg_value>V</arg_value> pairs on separate lines |
JSON schema |
glm47_moe |
glm-4.7, glm-5 |
<tool_call>NAME<arg_key>K</arg_key><arg_value>V</arg_value></tool_call> |
Structural tag, reasoning-aware |
step3 |
step3, step-3 |
<|tool_call_begin|>function<|tool_sep|><steptml:invoke name="..."> with <steptml:parameter> elements |
JSON schema |
kimik2 |
kimi-k2 |
<|tool_call_begin|>functions.NAME:IDX<|tool_call_argument_begin|>{json}<|tool_call_end|> |
Structural tag |
kimi_k3 |
kimi-k3, kimi_k3 |
XTML tools channel: <|open|>call tool="NAME" index="N"<|sep|> with argument elements |
Structural tag |
inkling |
inkling |
TML: <|message_model|>NAME<|content_invoke_tool_json|>{"name": ..., "args": {...}}<|end_message|> |
Structural tag |
minimax_m2 |
minimax |
<minimax:tool_call><invoke name="..."><parameter name="...">V</parameter></invoke></minimax:tool_call> |
JSON schema |
minimax_m3 |
minimax-m3, mm-m3 |
Every tag is prefixed with ]<]minimax[>[; parameters nest as XML elements |
Structural tag, reasoning-aware |
hy_v4 |
hy4; a model named exactly hy_v4 also matches |
<tool_calls> block holding <tool_call>NAME with <arg_key>K</arg_key> / <arg_value>V</arg_value> pairs; a checkpoint's :suffix on the tags is learned from the opening marker |
Structural tag, reasoning-aware |
cohere |
command-r, command-a, c4ai-command, cohere |
<|START_ACTION|>{"tool_name": ..., "parameters": {...}}<|END_ACTION|> |
JSON schema |
sarashina |
sarashina |
[{'name': ..., 'arguments': {...}}] as a Python literal, with an optional <|tool_calls|> prefix |
JSON schema |
Parsing Behavior
- Schema-aware arguments: the XML-style parsers (
qwen_xmland its aliases,glm45_moe,glm47_moe,hy_v4,minimax_m2,minimax_m3) andgemma4convert argument values to the types the tool's JSON schema declares.minimax_m3also resolves properties declared underoneOf,anyOforallOf. It turns an empty container element into[]or{}, and recovers the missing closing tag of an empty nested container. - Special tokens: when a request carries tools and
tool_choiceisn'tnone, the gateway decodes with special tokens kept, so the parser sees its trigger tokens. Under a JSON-schema constraint the output has no trigger tokens, so the request's ownskip_special_tokensapplies. - Streaming: arguments stream as deltas. If a parser buffers text as a possible tool call and it never becomes one, the text is sent as
contentinstead of being dropped. Thejson,llama,mistral,qwenandcohereparsers do this, as do the DeepSeek DSML parsers andminimax_m3, which releases a false tool-call start as soon as it can no longer match.qwen_xmlkeeps each call's arguments separate, even when several calls arrive in one chunk or a value contains}. - Tool call IDs:
call_plus 24 hex characters by default. For model names containingkimi, IDs follow the Kimi reference format instead:functions.NAME:N, orNAME_Nwhen the name also containsk3.Ncounts tool calls across the whole conversation.
Tool Execution Flow
- Parse: the resolved parser extracts calls from the model output. Text outside the calls stays in
content. - Return: Chat Completions returns the calls in
tool_callswithfinish_reason: "tool_calls", unless the engine stopped forlengthor an error. The Messages API returnstool_useblocks withstop_reason: "tool_use". - Execute (Responses API): on
/v1/responses, the gateway runs calls to MCP tools itself, appends the results to the conversation, and resumes generation. The request'smax_tool_calls, capped by the gateway, bounds the loop. See MCP.
Symphony Parsing
Under the default --parser symphony, the gateway reads a model's output with a Symphony table: one description of the model's output format that yields the reasoning, content and tool calls together, in place of the separate reasoning and tool-call parsers above. --parser legacy keeps those parsers for the whole gateway. Symphony applies to Chat Completions, the Messages API and the Responses API on this pipeline; every other endpoint keeps the legacy parsers. On /v1/responses it reads every model turn, the turns of an MCP tool loop included. The response shape does not change: the streaming deltas and message fields clients see are the same as under the legacy parsers.
Which Table Reads a Model
Three sources decide, in order: the model's tool_parser / reasoning_parser per-model overrides, the registry of checkpoints Symphony knows, and the --tool-call-parser / --reasoning-parser flags. The overrides decide when they select anything (the selection rules below). When they select nothing, the registry's table reads a checkpoint it knows — ahead of the flags, so a fleet-wide flag never reads a family the registry has a table for. The flags decide only for models the registry does not know; when they too select nothing, the legacy parsers read with their own auto-detection. Within a source, when both names are set, the tool-call name decides.
| Names a source sets | What they select |
|---|---|
| A table's name, or another name a table answers to (see Table Names) | That table, for every request for the model |
hf |
The table the model's response_template compiles into (below) |
Any other legacy tool-call parser's name, passthrough included |
The legacy parsers — the per-model escape hatch when a table misreads |
| No names | Nothing: the next source decides |
A name selects the legacy parsers only when it is a legacy tool-call name no table answers to, or passthrough as the reasoning name alone. A reasoning name alone that no table answers to, such as deepseek_r1, selects nothing, since every table reads the thought channel; a known checkpoint still reads with the registry's table.
When the registry's table reads a model whose overrides select no reader while the flags select a different reader, registration logs a warning saying so, once per model.
The registry matches the repository name — the text after the last path separator — exactly and without regard to case, under any organization or path: Qwen/Qwen3-8B, qwen3-8b and a local path ending in Qwen3-8B all read with the same table. Unlike legacy auto-detection, which finds a pattern anywhere in the name, a renamed or quantized checkpoint the registry does not know, such as Qwen3-8B-FP8, matches nothing: the flags read it, or the legacy parsers when the flags name no table. The x-smg-parser response header tells you which parser read a given response.
Table Names
The 35 tables are named qwen3, qwen3_tagged, qwen3_tagged_direct, qwen2.5, deepseek_v3, deepseek_v3.1, deepseek_v3.2, deepseek_v4, deepseek_v4.1, seed_oss, hy4, ling, iquest, olmo3, lfm2.5, xlam, json, llama4, minimax_m2, minimax_m3, mistral, mistral_v13, llama_nemotron, kimi_k2, kimi_k3, inkling, minicpm5, dots3, gemma4, function_gemma, glm, glm4, k2_horizon, muse_spark and plain. A table's name is valid wherever a parser name is: the flags, worker labels and model cards.
A table also answers to the names of the legacy parsers that read its format, so a model whose override already sets one of these names reads with the table under the default --parser symphony, with no change to the override. Two names in the table below are no legacy parser's: muse, the name downstream launchers pass for Muse models, and llama4_pythonic, an engine's exact name for the Llama 4 table.
| Name | Reads with table |
|---|---|
qwen |
qwen3 |
qwen_xml, qwen_coder, nemotron |
qwen3_tagged |
glm47_moe |
glm |
glm45_moe |
glm4 |
hy_v4 |
hy4 |
deepseek |
deepseek_v3 |
deepseek31, deepseek_v31 |
deepseek_v3.1 |
deepseek32 |
deepseek_v3.2 |
deepseek_v41 |
deepseek_v4.1 |
llama |
json |
llama4_pythonic |
llama4 |
minimax |
minimax_m2 |
muse |
muse_spark |
kimik2, kimi_thinking, kimi_k25 |
kimi_k2 |
Several legacy parser names — json, qwen3, deepseek_v4, gemma4, kimi_k3, inkling, minimax_m2, minimax_m3 and mistral — are a table's own name and read with that table. A legacy tool-call name no table answers to, such as pythonic, step3, sarashina or cohere, keeps the legacy parsers for its model.
The gateway checks the names at startup and at worker registration, against the configured --parser. A legacy parser's name counts only for its own flag — --reasoning-parser qwen_xml fails under either --parser — while a table's own name, muse, llama4_pythonic and hf pass in either flag under symphony. Under symphony, any other name fails with unknown tool-call parser '<name>': neither a legacy parser nor a Symphony table. Under legacy, when a flag's value is rejected and Symphony reads with it — a table's own name, muse, llama4_pythonic or hf — the error ends ... which --parser symphony reads with, as noted under Parser Selection.
A name that selects a table but is none of its flag's legacy parsers — qwen3 in --tool-call-parser, muse or muse_spark in either flag — binds the other name: it must name the same table (the table's own name, or muse for muse_spark) or be unset; a legacy name the table answers to is refused there, so qwen3_tagged pairs with qwen3_tagged or nothing, not with qwen_xml. hf binds the same way: the other name must be hf or unset.
The hf Name: the Response Template's Table
The name hf (the same name vLLM uses, and the same for both flags) reads each model with the table that the response_template in its tokenizer's tokenizer_config.json compiles into — transformers' description of how the output splits into a thought, content and tool calls. The table is compiled once per model and tokenizer; registering a new tokenizer under the model compiles it again. A model whose template is missing or does not compile refuses every request that reads with hf: 400 with code invalid_parser_configuration.
Per-Request Switch and Response Header
A request's X-SMG-Parser header, legacy or symphony, overrides the --parser flag for that one request, in either direction. Any other value is refused: 400 with code invalid_parser_header.
The response's x-smg-parser header names the parser that actually read it. It reports legacy when Symphony was chosen but no table took the request — the model's names select the legacy parsers, the registry does not know the checkpoint and the flags name no table, or a forced call fell back to a JSON-schema constraint (below) — so a client comparing the two modes can tell which one read each answer. Chat Completions and Messages responses carry the header; a /v1/responses response does not, though the request header still switches the parser for its turns.
What the Table Reads
A request's options select a variant of the table rather than a different reader, matching what the legacy path would run:
- With no tools declared, the table reads without its calls, so call syntax stays in
contentas text. Atool_choiceofnoneover declared tools keeps the table's calls instead: the prompt keeps the tool declarations, and the reader drops any call the model writes, delivering it neither astool_callsnor ascontent. - With
separate_reasoning: false, the table reads without its thought, so reasoning stays incontent. On the Messages API, thinking blocks are always separate, so only the calls vary.
Constraints Under Symphony
When a table reads a request, its structural tag stands in for the constraint of a forced or required tool_choice, and for a JSON response_format, so the engine's constrained output is in exactly the syntax the table parses. The engine receives the tag alone, never the tag and a competing constraint:
- A registry table with no tag for the forced call leaves the decision to the legacy constraint rules. When those send a JSON schema, the output has no table markers, so the legacy parsers read that response and
x-smg-parserreportslegacy. - A registry table with no tag for the JSON answer, or a request that continues the assistant's message, leaves
response_formatto the engine's JSON schema, as the legacy path does; the table still reads that response. hfrefuses what its table cannot both constrain and read, with 400invalid_parser_configuration: a forced call or a JSONresponse_formatits table has no tag for, aregexorebnfconstraint, andcontinue_final_messagecombined with a tag, since a tag writes a turn from its start.
These hf rules have one exception: a worker whose constrained_decoding policy is always and whose constrained_decoding_start label is first_token — an engine that takes a grammar on every turn and starts it at the first generated token. gRPC engines can report both in server info, and under PD disaggregation the decode worker's settings count.
When such a worker serves an hf-read request whose table can spell a whole turn (its calls name the tool they call), one grammar holds the whole turn instead: the thought, then either calls to the tools the tool_choice allows, each held to its schema, or the answer, with the request's JSON response_format, regex or ebnf composed into the grammar rather than sent beside it. A prompt that continues the assistant's message can take this grammar too: it resumes where the prompt leaves the model, inside or past its thought, or inside an answer or a call the prompt opened.
The whole-turn grammar refuses what it cannot hold, with 400 invalid_parser_configuration: a declared tool or parameter name the calls cannot carry, a strict: true tool it would hold to its schema more loosely, an ebnf in Lark's syntax (write it as xgrammar's root ::= ...), and, under auto, a strict tool or parallel_tool_calls: false together with the request's own regex or ebnf.
On any other worker — the default requested policy, or a constrained_decoding_start of after_reasoning or missing — and wherever the whole turn's grammar cannot start, the rules above stand.
Grammar on auto Tool Choice
A worker whose constrained_decoding policy is always — set as a worker label or spec field, or reported by the engine itself — tells the gateway its engine takes a grammar on every turn. When a table reads a chat or Messages request that allows calls under auto (or no tool_choice), the gateway then sends the table's tag for the request's callable tools: no call required, at most one when parallel_tool_calls is false (Messages: disable_parallel_tool_use). The default policy, requested, sends a grammar only when the request asks for one.
Nothing is sent, and nothing refused, when the request carries a constraint of its own (a JSON response_format, regex, ebnf), has no callable tools, forbids calls with tool_choice: none, continues the assistant's message, or the table has no tag for the calls. On an hf-read model, a worker whose engine starts its grammar at the first token gets the whole-turn grammar in this tag's place, where that grammar starts.
Under PD disaggregation the decode worker's policy applies. The gateway decides the constraint on the worker selected for the request, and a retry re-shapes the tag for the worker it picks. When the policy chose the constraint — this tag, or the whole-turn grammar — a retry re-selects only workers that decide it the same way; a constraint the request itself asked for suits any worker.
Constrained Decoding (XGrammar)
When a request forces a tool call or asks for structured output, SMG attaches a constraint to the gRPC request. The engine compiles it with its guided-decoding backend (XGrammar) and enforces it token by token, so the output matches the declared schemas before SMG's parsers ever see it.
Where It Runs in the Pipeline
In the regular gRPC pipeline, the tool constraint is generated after the prompt is rendered and tokenized (model_gateway/src/routers/grpc/regular/stages/chat/preparation.rs):
- Resolve the tools the template renders: an
allowed_toolschoice narrows them to its subset; a namedtool_choiceandnonekeep every declared tool in the prompt - Render the prompt (chat template or native renderer)
- Tokenize
- Process multimodal inputs (see Multimodal Pipeline)
- Build the tool constraint (
generate_tool_constraint) - Build the stop decoder, then worker selection and dispatch
The Harmony pipeline (gpt-oss) builds its structural tags before encoding (model_gateway/src/routers/grpc/harmony/stages/preparation.rs). It rejects a request that combines a forced tool call with response_format.
When a Constraint Is Sent
| Request | Constraint |
|---|---|
No tools, or tool_choice is auto or none |
None. Under auto the parser extracts calls from free-form output; under none no tool parser runs (a Symphony table instead drops any call the model writes) |
tool_choice is required, names a function, or is allowed_tools with mode: "required" |
A structural tag when --tool-call-parser or an override sets a parser that has one; otherwise a JSON schema |
| Type | Parsers | What it constrains |
|---|---|---|
structural_tag |
mistral, deepseek_v41, glm47_moe, hy_v4, kimik2, kimi_k3, inkling, minimax_m3 |
The model's own format: trigger tokens, call framing, and argument JSON. The model-specific parser reads the result |
json_schema |
Fallback for every other case, auto-detected parsers included | Plain JSON. A named function constrains its parameters. required constrains an array of {"name", "parameters"} objects, with $defs merged across tools; conflicting definitions return 400 invalid_tool_configuration |
gemma4 is the one exception: set by the flag or an override, it sends no constraint at all, and the forced call is parsed from the model's native output.
When a Symphony table reads the request, its own structural tag takes the place of this choice (see Constraints Under Symphony), and a worker whose constrained_decoding policy is always gets a tag for auto tool choice too (see Grammar on auto Tool Choice).
Some parsers add rules on top of their structural tag:
glm47_moe,hy_v4,minimax_m3: when thinking is on, these families' templates end the prompt inside the thinking block, so a grammar applied from the model's first token would force the call into the thought, where the reasoning parser would absorb it. SMG instead wraps the tag so the model reasons first, in the shape the selected worker's engine needs. The worker'sconstrained_decoding_startlabel, which the gRPC servicers advertise from the engine's configuration, says where that engine starts a grammar on a thinking prompt (vLLM reports either value, from its structured-outputs config):after_reasoning(SGLang running a reasoning parser): the engine defers the grammar behind its own reasoning parser, so the tag holds the bare calls, forced right at the thought's end.first_token(TokenSpeed always; SGLang without a reasoning parser): the engine applies the grammar from the first generated token, so the tag opens with a thought block — free text without the think and call markers, closed by the family's thought-end marker (</think>,</mm:think>) — and the calls follow.- No label: free text that writes none of the call markers and isn't required to end with any marker, then the calls — a shape that fits either kind of engine.
Under PD disaggregation the decode worker's label counts, and a retry re-shapes the tag for the worker it picks.
kimi_k3: each argument grammar carries the tool schema's$defs/definitionsblock, so parameters that use$refcompile instead of failing the request.
Combining with Structured Output
A request carries at most one constraint. response_format becomes a JSON schema (json_object is {"type": "object"}), and text adds nothing. The regex and ebnf request extensions each add a constraint of their own. For SGLang, vLLM and TokenSpeed workers, the gateway rejects a request that sets more than one of these with 400 invalid_request_parameters. If a forced tool call applies as well, the gateway keeps the output-format constraint and drops the tool one for SGLang, TensorRT-LLM and TokenSpeed workers, and keeps only the tool constraint for vLLM workers.
Enforcement
The constraint travels in the request's SamplingParams.constraint oneof (crates/grpc_client/proto/). The oneof has json_schema, regex, ebnf_grammar (grammar on vLLM) and structural_tag fields, and vLLM also accepts json_object and choice. TensorRT-LLM receives the same constraint as GuidedDecodingParams. The engine needs a grammar backend to enforce it:
- TokenSpeed: start it with
--grammar-backend xgrammar. Its default is none. - TensorRT-LLM: set
guided_decoding_backend: xgrammarin its--extra_llm_api_optionsfile. - MLX: doesn't support constraints. It rejects a chat request with a forced tool call or a
response_format(400) and ignores the chatregexandebnfextensions.
See gRPC Workers for the launch commands.
Older XGrammar Releases
The structural tags Symphony's tables build can carry the optional, plus, star and token nodes, which xgrammar compiles from release 0.1.33 on. On an older xgrammar, a tag that carries one is refused at compile time (Format type not recognized), and the request fails.
Each Rust servicer reads the version of the xgrammar installed beside its engine once, at launch. When that version predates 0.1.33 and the engine's grammar backend runs xgrammar — the backend is named xgrammar, is vLLM's auto, or is one the servicer cannot resolve (the engines default to xgrammar where one runs) — the servicer advertises the structural_tag_vocabulary: older worker label.
For a worker that carries the label, the gateway spells Symphony's tags without optional, plus and star: the same language, written with the nodes every xgrammar release compiles, so the tag compiles instead of failing the request. One exception: a marker the table writes as a single token of the model's vocabulary stays as built, so a tag that carries one still fails on the older compiler.
Without the label — a current xgrammar, another grammar backend, or a servicer that doesn't report it — every tag is sent as the table built it. Only Symphony's tags are respelled; the legacy parsers' structural tags are always sent as built.
The selected worker's label decides each request (under PD disaggregation, the decode worker's). A forced call's tag is built before a worker is selected, so it takes the older spelling — which every compiler accepts — when any of the model's token-generating workers advertises the label.
The Python servicers and the ZMQ direct backend do not report the label; when such a worker's engine runs an older xgrammar, set structural_tag_vocabulary: older among the labels of its worker spec yourself.
Configuration
Parser CLI Options
| Option | Default | Description |
|---|---|---|
--parser |
symphony |
Which parser reads a Chat Completions, Messages or Responses API response: symphony (Symphony tables) or legacy (the per-model parsers on this page). A request's X-SMG-Parser header overrides it for that request |
--reasoning-parser |
Auto | Reasoning parser for every model without a per-model override. Under the default --parser symphony, may name a Symphony table or hf, and reads only the models Symphony's registry does not know |
--tool-call-parser |
Auto | Tool-call parser for every model without a per-model override. Also opts the parser into structural-tag constraints. Under the default --parser symphony, may name a Symphony table or hf, and reads only the models Symphony's registry does not know |
--chat-template |
None | Jinja chat template file. A model card's chat_template path wins over it; without either, SMG searches the model directory (lookup order). The DeepSeek-V3.2, V4.1 and Kimi-K3 native renderers ignore it; a DeepSeek-V4 checkpoint renders through it instead of its native renderer |
--mcp-config-path |
None | Path to MCP server configuration file |
MCP Integration
When MCP is configured, the gateway executes MCP tool calls on /v1/responses:
smg launch \
  --worker-urls grpc://worker:50051 \
  --model-path meta-llama/Llama-3.2-3B-Instruct \
  --tool-call-parser llama \
  --mcp-config-path /path/to/mcp.json
See the MCP Guide for detailed configuration.
Recommended Configurations
Thinking Model
DeepSeek-R1 with reasoning extraction.
smg launch \
  --model-path deepseek-ai/DeepSeek-R1 \
  --reasoning-parser deepseek_r1 \
  --worker-urls grpc://worker1:50051
Tool Calling Model
Llama 3.2 with MCP tool execution.
smg launch \
  --model-path meta-llama/Llama-3.2-3B-Instruct \
  --tool-call-parser llama \
  --mcp-config-path /config/mcp.json \
  --worker-urls grpc://worker:50051
Full Pipeline
Qwen3 with reasoning, tool calls, MCP, and tokenizer caching.
smg launch \
  --model-path Qwen/Qwen3-32B \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen \
  --mcp-config-path /config/mcp.json \
  --tokenizer-cache-enable-l0 \
  --tokenizer-cache-enable-l1 \
--worker-urls grpc://worker:50051Monitoring
Pipeline Metrics
This pipeline records the metrics below. The smg_router_* series carry router_type="grpc"; the MCP metrics have no router_type label:
| Metric | Description |
|---|---|
smg_router_requests_total |
Requests routed, by model, endpoint and streaming |
smg_router_ttft_seconds |
Time to first token (streaming requests) |
smg_router_tpot_seconds |
Time per output token (streaming requests) |
smg_router_tokens_total |
Input and output tokens, by token_type (streaming and non-streaming requests) |
smg_mcp_tool_calls_total |
MCP tool invocations, by model, tool_name and result |
smg_mcp_tool_iterations_total |
Responses API tool-loop iterations |
See the Metrics Reference for every metric and label.
Debug Logging
RUST_LOG, when set, replaces the filter built from --log-level. Targets are crate and module paths. Keep a base level such as warn,smg=info so the rest of the gateway still logs:
# gRPC pipeline stages (preparation, worker selection, response processing)
RUST_LOG=warn,smg=info,smg::routers::grpc=debug smg launch ...

# Tool-call and reasoning parsers
RUST_LOG=warn,smg=info,tool_parser=debug,reasoning_parser=debug smg launch ...

# Tokenizers, chat templates and native renderers
RUST_LOG=warn,smg=info,llm_tokenizer=debug smg launch ...Troubleshooting
| Symptom | Cause | Solution |
|---|---|---|
Reasoning stays in content |
No reasoning parser matched the model name, or the request set separate_reasoning: false |
Set --reasoning-parser or a per-model override; compare the name with the patterns above |
Tool calls come back as text in content |
No tool parser matched, or the parser doesn't fit the model's format | Set --tool-call-parser or a tool_parser override for that model |
Gateway exits at startup with unknown tool-call parser or unknown reasoning parser, or the pip smg launch reports invalid choice |
The name isn't one the configured --parser can read with; an error ending which --parser symphony reads with means Symphony reads with the name, but the gateway was started with --parser legacy |
Use a name from the reference tables above (names use underscores), or drop --parser legacy so the default Symphony reads a table's name |
The x-smg-parser response header says legacy under --parser symphony |
No table took the request: the model's names keep the legacy parsers, the registry doesn't know the checkpoint's exact repository name and the flags name no table, or a forced call fell back to a JSON-schema constraint | Name a table or hf in the model's tool_parser override, or in --tool-call-parser for a checkpoint the registry doesn't know; see Symphony Parsing |
Worker registration fails with declares a parser override ... the gateway cannot read with |
A label or model card names a parser the configured --parser can't read with — under --parser legacy, Symphony table names and hf among them |
Fix the override name, or drop --parser legacy so the default Symphony reads a table's name |
Forced tool calls or response_format not enforced |
The engine runs without a grammar backend | Start TokenSpeed with --grammar-backend xgrammar; give TensorRT-LLM guided_decoding_backend: xgrammar |
| MCP tools time out | Slow tool execution | Check MCP server configuration |