Health Checks
Background health checks continuously probe every worker, take unhealthy workers out of the selection pool without waiting for requests to fail, and return them when they recover.
Overview
Proactive Monitoring
Detect worker failures before they impact requests—not after.
Automatic Isolation
Unhealthy workers stop receiving traffic without manual intervention.
Self-Healing
Workers rejoin the pool when they recover, including after a restart on the same address.
Configurable Sensitivity
Tune detection speed vs. tolerance for temporary issues, globally or per worker.
Why Health Checks?
Without proactive health checks:
- Reactive detection: Failures only discovered when real requests fail
- Wasted requests: Multiple requests may fail before worker is marked unhealthy
- Slower recovery: No way to know when a worker has recovered without trying it
With health checks:
- Proactive detection: Unhealthy workers leave the pool without waiting for requests to fail
- Fast recovery: Workers rejoin the pool as soon as they're healthy
- Fewer wasted requests: Real requests only go to verified healthy workers
How It Works
SMG probes each registered worker on its own schedule. A newly registered worker is probed immediately, then once every --health-check-interval-secs. Probes run concurrently, up to 128 at a time, so a slow worker does not delay the others.
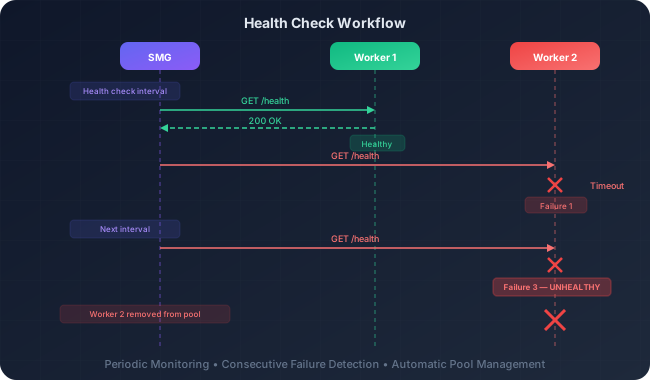
Probes by Worker Type
| Worker | Probe | Healthy when |
|---|---|---|
| HTTP | GET on the worker URL plus --health-check-endpoint (default /health), sending the worker's API key as a bearer token when one is configured |
The response is 2xx within --health-check-timeout-secs |
| gRPC | The engine's HealthCheck RPC; --health-check-endpoint does not apply |
The engine reports healthy within --health-check-timeout-secs |
ZMQ (ipc:// or tcp://) |
A local check of the engine connection; nothing is sent to the engine | The engine's handshake has completed and its connection is still alive |
| External providers (OpenAI, Anthropic, and others) | Not probed unless the worker spec sets health.disable_health_check: false |
— |
The ZMQ probe is also what reconnects a restarted engine, so health checks stay on for ZMQ workers even when they are disabled in configuration. Under --upstream-http2, HTTP probes use the same protocol as request traffic: HTTP/2 for workers that negotiated it at registration, HTTP/1.1 for the rest (see Request Streaming).
The HTTP probe sends the API key in the Authorization header, as regular-mode HTTP requests do, so on a plain http:// worker URL the key crosses the network unencrypted.
Worker States
| State | Meaning | Traffic |
|---|---|---|
| Pending | Freshly registered, not yet verified | No requests |
| Ready | Passing health checks | Receives requests |
| NotReady | Consecutive probe failures reached the readiness threshold | No requests; still probed |
| Failed | Failures continued to the liveness threshold, or Pending ran out of probe attempts |
No requests; removed when within auto-recovery's removal scope, otherwise still probed |
| Draining | A Ready worker being removed (by service discovery or the worker API) |
No new requests; not probed |
HTTP and gRPC workers become Ready as soon as their registration completes, because registration has already reached the worker. ZMQ workers stay Pending until the engine completes its handshake, then become Ready immediately.
The smg_worker_health gauge collapses these to 1 (Ready) and 0 (anything else), so existing dashboards continue to work.
State Transitions
| Transition | Condition | At the defaults |
|---|---|---|
| Pending → Ready | --health-success-threshold consecutive successful probes, if registration or the ZMQ handshake has not already made the worker Ready (see above) |
2 probes |
| Pending → Failed | 10 × --health-failure-threshold probes without reaching the success threshold (keeps misconfigured URLs from lingering) |
30 probes |
| Ready → NotReady | --health-failure-threshold consecutive failed probes |
3 probes |
| NotReady → Ready | --health-success-threshold consecutive successful probes |
2 probes |
| NotReady → Failed | 3 × --health-failure-threshold further consecutive failed probes (the liveness threshold, analogous to a Kubernetes liveness probe) |
9 probes |
| Failed → Ready | --health-success-threshold consecutive successful probes, if the worker was not removed |
2 probes |
The failure count restarts when a worker enters NotReady, so a Ready worker that stops answering reaches Failed after 4 × --health-failure-threshold consecutive failed probes: 12 probes, about 12 minutes at the default 60-second interval.
Failed is not terminal. A failed worker that is not removed keeps being probed, so an engine that restarts on the same address rejoins without being registered again.
How Long a Restarted Engine Stays Out
The thresholds above count probes; the schedule turns them into time. Each worker is probed on its own clock, one probe every --health-check-interval-secs counted from the start of the previous probe, and a probe with no answer within --health-check-timeout-secs is a failure.
One case is paced faster: when a probe on a demoted (NotReady or Failed) worker passes without reaching the success threshold, the next probe follows at most a probe's timeout later (or an interval, if that is shorter), so the successes that return a worker are consecutive probes close together, not an interval apart. A failed probe, and every probe on a Pending or Ready worker, keeps the interval pacing.
At the defaults (interval 60, timeout 5, 3 failures out, 2 successes back), an engine that stops answering reads as follows.
Leaving routing. The first probe after the outage begins falls within one interval, and the third failed probe comes two intervals after it, so a Ready worker becomes NotReady between two and three intervals after the outage began: 125 to 185 seconds at the defaults, the last probe's timeout included. Until then, requests routed to the worker fail and are retried on another worker while one is left untried — in PD mode each attempt re-selects its prefill/decode pair from all available workers, so a retry can pick the failed worker again (Retries) — and --cb-failure-threshold failures (default 10) open its circuit breaker, which takes it out of selection on its own. A worker whose transport reports the failure (a gRPC worker's load poll or KV event stream failing on a reset connection) leaves routing within --worker-stall-secs (default 2) of the failure, as unreachable (When a Worker Dies or Loses Its Link); an HTTP worker's failed polls never arm that veto.
Returning. Once the engine answers again, how soon the worker takes requests depends on what excluded it:
| What excluded the worker | What brings it back | At the defaults |
|---|---|---|
The health check (NotReady or Failed), with probes as the only contact: an HTTP worker, or any worker nothing else reaches while it is out (the load monitor polls Ready workers only) |
The first passing probe falls within one interval of the engine's return; the second follows at most a probe's timeout later, promotes the worker, and the promotion readmits its circuit breaker | Within about one interval plus a probe timeout after the engine is back: up to roughly 65 seconds |
| The health check, after an unreachable veto, on a worker with a transport that reconnects on its own (a gRPC worker's KV event stream) | The first successful contact clears the veto and runs the worker's probe at once instead of at its next slot: success 1 now, success 2 at most a probe's timeout later | Within about one probe timeout of the first contact: 5 seconds at the default |
| The health check on a ZMQ worker | The engine's handshake is what the probe reads, so the handshake itself promotes the worker | As soon as the engine completes its handshake |
| The unreachable veto alone (an outage shorter than the probes needed to demote the worker) | Any successful contact: the next answered load poll, within --load-monitor-interval (default 10); the same contact closes a circuit the failures opened |
Within about 10 seconds of the engine's return |
| The circuit breaker alone (an HTTP worker whose outage was too short to demote it) | The circuit's own timeout, then a half-open trial (Circuit Breakers) | --cb-timeout-duration-secs (default 60) after the circuit opened |
Two consequences of the thresholds:
- A short outage never changes the health state. An engine down for 30 seconds meets at most one probe, and three consecutive failures are needed, so the worker stays
Readythroughout. What excludes it in the meantime, if anything, is the liveness veto or the circuit breaker, which lift as in the last two rows. - One passing probe is deliberately not a return. The success threshold of
2keeps a single good answer out of a flapping engine's run from putting it back in rotation: the engine has to keep answering across the gap to the next probe. That gap costs at most one more probe timeout, not another interval, so most of the wait is for the first passing probe, which still falls anywhere within one interval of the engine's return. To shorten the return, lower--health-check-interval-secs, which shortens the exclusion as well; lowering--health-success-thresholdto1saves only the probe-timeout gap, at the cost of the flap protection.
Under service discovery, a worker that reaches Failed is removed instead by default and comes back through discovery's registration, which waits for the engine to answer (Worker Auto-Recovery).
Worker Auto-Recovery
--remove-unhealthy-workers (alias --worker-auto-recovery) decides what happens to a worker that reaches Failed:
| Failed worker | What happens | How it comes back |
|---|---|---|
| Within the removal scope | Removed from the registry right away (it is not Ready, so there is no drain window) |
Service discovery registers it again while its pod is still Ready, and registration waits for the engine to answer |
| Outside the scope | Stays registered and out of rotation, and keeps being probed | Rejoins in place after --health-success-threshold consecutive successful probes |
The default follows --service-discovery, and how the flag was set decides the scope. Unset with discovery on, removal applies only to the workers the discovery provider registered — the provider re-registers them once their engine returns, while static and API-added workers, which nothing would re-add, stay registered and recover in place. The bare flag removes every failed local worker, static and API-added ones included, though nothing re-adds those; =false removes none. Unset without discovery, none are removed, so an outage cannot permanently shrink a static fleet.
| Command | Failed workers removed |
|---|---|
smg launch --service-discovery ... |
The workers discovery registered |
smg launch --worker-urls ... |
None |
smg launch --worker-urls ... --remove-unhealthy-workers |
Every local worker (bare flag) |
smg launch --service-discovery ... --no-remove-unhealthy-workers |
None |
smg launch (the Python launcher from pip, and the container image) also accepts the alias, as --worker-auto-recovery and --no-worker-auto-recovery. The smg binary has no --no- form; turn auto-recovery off there with --remove-unhealthy-workers=false.
Re-registration waits because it goes through the same startup-probe gate as every registration: no worker is created until a probe succeeds. An HTTP worker must answer GET /health with a 2xx, a gRPC worker must answer a health RPC and report itself healthy, and a bare host:port address is probed over both protocols, keeping the one that answers — HTTP, if both do. The startup probe always uses /health; --health-check-endpoint changes only the background probes.
Failed probes are retried every --worker-startup-check-interval seconds; when --worker-startup-timeout-secs elapses first, the job fails and a later reconcile pass submits it again (Worker Startup). An engine that is still down keeps its registration waiting instead of rejoining the pool only to fail out again.
The exception is a ZMQ URL (ipc:// or tcp://): SMG binds the sockets and the engine dials in, so there is no endpoint to probe. It registers without a probe, as Pending, and is promoted to Ready when the engine completes its handshake.
Removal targets are resolved from registered worker URLs and pinned to the failed worker's own revision, so only that registration is removed: sibling DP ranks behind the same address stay registered. Workers imported from mesh peers are never removed locally; the gateway that owns them manages them.
Configuration
smg \
  --worker-urls http://w1:8000 http://w2:8000 \
  --health-check-interval-secs 60 \
  --health-failure-threshold 3 \
  --health-success-threshold 2 \
  --health-check-timeout-secs 5 \
--health-check-endpoint /healthParameters
| Parameter | Default | Description |
|---|---|---|
--health-check-interval-secs |
60 |
Interval between probes of each worker |
--health-failure-threshold |
3 |
Consecutive failures before a Ready worker becomes NotReady; also scales the liveness threshold (3×) and the Pending probe cap (10×) |
--health-success-threshold |
2 |
Consecutive successes before a worker returns to Ready |
--health-check-timeout-secs |
5 |
Timeout for each probe |
--health-check-endpoint |
/health |
HTTP path for background probes of HTTP workers; the startup probe at registration always uses /health |
--disable-health-check |
false |
Disable background probing (ZMQ workers keep their local check) |
--remove-unhealthy-workers |
follows --service-discovery |
Remove workers that reach Failed: every local worker with the bare flag, only the discovery-registered ones when unset under service discovery (alias --worker-auto-recovery); see Worker Auto-Recovery |
--drain-settle-secs |
5 |
Seconds a Ready worker stays Draining before removal; 0 removes immediately |
Per-Worker Overrides
Workers registered through the worker API can override the gateway defaults in a health block of the worker spec; unset fields keep the gateway values. The same block can be changed later with PATCH /workers/{worker_id}.
{
  "url": "http://worker-3:8000",
  "health": {
    "check_interval_secs": 15,
    "timeout_secs": 3,
    "failure_threshold": 5,
    "success_threshold": 1,
    "drain_settle_secs": 30
  }
}| Field | Overrides |
|---|---|
check_interval_secs |
--health-check-interval-secs |
timeout_secs |
--health-check-timeout-secs |
failure_threshold |
--health-failure-threshold |
success_threshold |
--health-success-threshold |
disable_health_check |
--disable-health-check (ignored when a ZMQ worker registers) |
drain_settle_secs |
--drain-settle-secs |
The probe endpoint and the auto-recovery setting apply gateway-wide. Workers created by service discovery use the gateway defaults.
Recommended Configurations
Fast Detection
Sensitive to failures—detect issues quickly.
smg \
  --health-check-interval-secs 10 \
  --health-failure-threshold 2 \
  --health-check-timeout-secs 3
Use when: Critical availability, rapid failure response needed
Conservative Detection
Tolerant of network blips.
smg \
  --health-check-interval-secs 120 \
  --health-failure-threshold 5 \
  --health-success-threshold 3
Use when: Flaky networks, workers with occasional slow responses
Production Balanced
Balanced detection for typical deployments.
smg \
  --health-check-interval-secs 30 \
  --health-failure-threshold 3 \
  --health-success-threshold 2 \
  --health-check-timeout-secs 5
Use when: Standard production environments
✗ No Health Checks
Disable health checks entirely.
smg --disable-health-checkUse when: External health monitoring, testing scenarios
Worker Health Endpoint
SMG expects HTTP workers to provide a health endpoint that returns:
- 2xx status code: Worker is healthy
- Any other status or timeout: Worker is unhealthy
Example Health Endpoint (vLLM)
vLLM workers expose /health by default:
# vLLM automatically provides /health endpoint
vllm serve meta-llama/Llama-3.1-8B-Instruct --port 8000
Example Health Endpoint (SGLang)
SGLang workers expose /health by default:
# SGLang automatically provides /health endpoint
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct --port 8000
Custom Health Endpoint
If your worker uses a different health endpoint:
smg \
  --worker-urls http://worker:8000 \
  --health-check-endpoint /api/health
The custom path applies to the background probes. The startup probe at registration always sends GET /health, so the worker must answer that path with a 2xx too, or registration fails.
Gateway Probe Endpoints
The probes above are how SMG checks its workers. For Kubernetes, load balancers, and uptime monitors, SMG answers its own probes:
| Endpoint | Response |
|---|---|
/liveness |
200 OK while the process runs, including during shutdown |
/health |
Same as /liveness |
/readiness |
200 with {"status":"ready","healthy_workers":N,"total_workers":M} and the sections below when SMG can serve traffic, otherwise 503 with a reason |
/readiness returns 503 with one of these reasons:
reason |
Meaning |
|---|---|
insufficient healthy workers |
No Ready worker. In PD and EPD modes, a prefill or decode role below its readiness threshold — by default one Ready worker each (see below); EPD mode also needs a Ready encode worker |
tokenizer not yet registered |
A Ready gRPC or ZMQ worker's tokenizer is not registered: it is still loading, or loading failed (skipped with --disable-tokenizer-autoload) |
draining |
Graceful shutdown has started |
Except while draining, both the ready and the not-ready body carry a models section: one entry per served model, with model, ready, healthy_workers, total_workers, and on a model that is not ready a reason — no_healthy_worker (draining when every one of its workers is draining), no_healthy_prefill_worker, no_healthy_decode_worker, or no_healthy_encode_worker for a PD/EPD model that lacks the role (a model needs one Ready worker per role; the configurable minimums below apply to the gateway-level decision), or tokenizer_not_ready. The status keeps answering for the gateway as a whole, so a rollout or traffic switch can watch one model from the same probe, and one model's outage does not take a gateway that still serves others out of rotation. A model whose last worker left is no longer listed.
In PD and EPD modes, the gateway-level decision can require more than one Ready worker per role. --prefill-min-ready-workers and --decode-min-ready-workers set absolute minimums (default 1), and --prefill-min-ready-percent and --decode-min-ready-percent (1–100) require a percentage of --prefill-expected-workers or --decode-expected-workers, a fixed denominator that worker removal cannot shrink. A role's requirement is the larger of the two; the encode role always requires one Ready worker. PD/EPD responses expose each role's decision in a roles section (healthy, registered, expected, minimum, minimum_percent, required, ready).
Under worker-side media placement (--mm-processing worker), the ready body also lists models_without_media_processing: models whose workers report a vision encoder but none of which processes media references, so their requests that forward media references are refused while their text requests still serve. The gateway stays ready; a worker that processes media references takes the model off the list.
The readiness decision is recomputed from worker registry events (and at least once per second) and served from memory, so probes answer in constant time regardless of fleet size. Probe responses, including the expected 503s, are logged at DEBUG level, so polling does not flood the log with errors.
Set --health-check-port <port> to also serve /liveness, /readiness, and /health on a dedicated plain-HTTP listener with its own runtime thread, so a saturated gateway cannot starve its probes. The routes stay available on the main port. See Dedicated Probe Port for a Kubernetes example.
Interaction with Circuit Breakers
Health checks and circuit breakers are independent gates, and a worker is selected only when both allow it:
| Gate | Driven by | Excludes a worker when |
|---|---|---|
| Health check | Background probes | Its state is anything other than Ready |
| Circuit breaker | Real request outcomes | Its circuit is open (closed and half-open circuits allow requests) |
The gates exclude a worker independently, but recovery is coupled: a promotion back to Ready readmits the worker's circuit breaker. An open circuit moves to half-open at once instead of waiting out --cb-timeout-duration-secs, so a recovered worker — an engine restarted on the same address, for example — takes traffic as soon as its probes promote it, and a circuit the outage left closed forgets its consecutive-failure count.
The trial follows the usual half-open rules: --cb-success-threshold consecutive successes close the circuit, and one failure reopens it for a full timeout. Passing probes on a worker that is already Ready are not a promotion and start no new trial, so a flapping worker gets one trial per demotion-and-promotion cycle.
Key differences:
- Health checks: Proactive background monitoring (no request impact)
- Circuit breakers: Reactive detection based on real request failures
Both are recommended for production deployments. The hash-based policies (consistent_hashing and prefix_hash) also skip a worker whose circuit breaker is open, because the router removes unavailable workers before the policy runs.
Monitoring
Metrics
| Metric | Labels | Description |
|---|---|---|
smg_worker_health_checks_total |
worker_type, result |
Probe results; result is success or failure |
smg_worker_health |
worker |
1 when the worker is Ready, 0 otherwise; a removed worker's series is dropped from the scrape |
Useful PromQL Queries
Health Status
# Current health status per worker
smg_worker_health

# Count of unhealthy workers
count(smg_worker_health == 0)
Check Results
# Health check success rate
rate(smg_worker_health_checks_total{result="success"}[5m]) /
rate(smg_worker_health_checks_total[5m])

# Failed checks per minute
rate(smg_worker_health_checks_total{result="failure"}[1m]) * 60
Alert Thresholds
| Metric | Warning | Critical | Action |
|---|---|---|---|
| Unhealthy workers | 1 worker | >50% workers | Investigate worker health |
| Health check success rate | <90% | <70% | Check network connectivity |
Alerting Example
groups:
  - name: smg-health-checks
    rules:
      - alert: WorkerUnhealthy
        expr: smg_worker_health == 0
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "Worker {{ $labels.worker }} is unhealthy"

      - alert: MajorityUnhealthy
        # A removed worker's series leaves the scrape, so every series is a registered worker
        expr: count(smg_worker_health == 0) > count(smg_worker_health) / 2
        for: 1m
        labels:
          severity: critical
        annotations:
          summary: "Majority of workers are unhealthy"
Tuning Guidelines
| Symptom | Potential Adjustment |
|---|---|
| Workers marked unhealthy too quickly | Increase --health-failure-threshold |
| Slow failure detection | Decrease --health-check-interval-secs |
| Health checks timing out | Increase --health-check-timeout-secs |
| Workers slow to rejoin | Decrease --health-check-interval-secs: the first passing probe is most of the wait, and each further success adds at most a probe timeout |
| Too many health check requests | Increase --health-check-interval-secs |
| Workers vanish for good after an outage in a static fleet | Turn auto-recovery off (--remove-unhealthy-workers=false; Python launcher: --no-remove-unhealthy-workers) so failed workers rejoin in place |
Removed workers stay Draining too long |
Decrease --drain-settle-secs |